
0.9.7.2 did not pass the test fixed beforehand for CAFE 1.0 (Amendment 13 item 9 (applied unchanged by Amendment 15 item 4): 62 resolved pairs with the datasets resampled, 56 needed; A signal-to-noise 4.81, 6 needed), so 0.9.5 stays the CAFE 1.0 candidate. The test · all versions compared.
Main board
2 of 15 ranked models share tier 1, so the order inside that tier is no claim. On A, the no-encoder ZERO row (0.642) scores above 8 of the 15 ranked rows; only Mantis, pj_better_10m ◊, pj_better_3p7m ◊, pjgood-warp-xview-combo-10M ◊, pj_better_1m ◊, MantisV2, NuTime score above it. Without A (C and FE only), tier 1 is pj_better_10m ◊, Chronos-2, Mantis and the ◊ ranks move: pj_better_3p7m ◊ 3 to 4; pjgood-warp-xview-combo-10M ◊ 4 to 5. The board rests on 24 C, 13 A and 15 FE datasets. Main board: one readout per model.
Forgis runs CAFE and developed 5 of the 15 ranked models, marked ◊, with CAFE test scores visible during their development. They get no special colour here. You can take them out of every table with the switch above the board. Their weights are not public, so outsiders cannot rerun them. Forgis staff chose the A additions of 0.9.7.2 with the released 0.9.7 board and its per-dataset A signal-to-noise known (from 1.0 on UKWIND to 6.1 on KUKA), after four candidates had been measured without a model (Amendment 15). Forgis staff chose the 0.9.7 drops and additions with the 0.9.6 board known; six drops were informed by scores (C 3W, bosch, soredd_abc; FE ngafid_hastall, substorm_omni, epa_aqs_pm25), and the two C additions were accepted after a screening that scored a ◊ row (pjgood-warp-xview-combo-10M) against its random-init twin on them (see the card). ◊ rows: Forgis weights, not public checkpoints. Other variants scored on CAFE or PrecursorBench Eval data before each was submitted (lower bounds, see Known limitations): LeSaturn-warppool-factorized-7.4M 43, pjgood-warp-xview-combo-10M 59, pj_better_3p7m and pj_better_10m 64, and pj_better_1m 65.
◊ Forgis row. Kind tells unranked rows apart: baseline, reference, tabular. Click a column to sort. The glossary near the end explains every term.
Is 0.9.7.2 the CAFE 1.0 candidate?
0.9.7.2 resolves 62 of 105 pairs with the datasets resampled, against 61 for 0.9.7, 51 for 0.9.6 and 49 for 0.9.5 and its A signal-to-noise is 4.81 (0.9.7: 4.04). The test of Amendment 13 item 9 (applied unchanged by Amendment 15 item 4) needs at least 56 pairs and an A signal-to-noise of at least 6. 0.9.7.2 fails it (an A signal-to-noise of 4.81 is below 6), so 0.9.5 stays the CAFE 1.0 candidate. In either case CAFE 1.0 also needs two fresh audits in a row with no blocker, and Jonas Petersen's explicit go.
Read the candidacy with this: 0.9.5 contains 5 A datasets that the admission rules of Amendments 13 and 15 reject (CARE_A, CARE_C, RIGS, W3 and SKAB), and it counts ESA_M1/ESA_M2 and SMAP/MSL as separate datasets, which item 2 now pools. Whether 1.0 may be a version that fails its successor's admission rules is for Jonas Petersen to decide before any 1.0 go.
The goal for the A signal-to-noise was 9; it was not met (4.81).
The pair count was fixed before any 0.9.7 cell existed (Amendment 13 item 9); Amendment 15 item 4, written before any 0.9.7.2 cell, applies the same test to 0.9.7.2; the reading of the A signal-to-noise used here was fixed in the PREREG09 note of 2026-11-05 19:02Z, after the first 0.9.7 A cells existed and before any was read (the amendment's literal wording, spread SD over pair noise, is in the table below; the table gives both readings for every version): the 105 pairs of the 15 ranked rows of 0.9.5, on the CAFE score, with the datasets resampled within each task as well as the test material (10,000 draws, Holm), by the same code for every version. Holding the datasets fixed, as the main board does, would narrow the intervals of a bigger version even if its new datasets added nothing; with the datasets resampled, a dataset that orders the models differently from the others widens them. Repeating the resampling with 5 other seeds gives the same count on all 6 seeds (62). Audit 17 repeated it with its own code over 16 seeds and got 61 to 64 (mean 62.1, SD 0.7), so differences of one or two pairs (61 in 0.9.7 against 62 here, 64 without REASSEMBLE) are within Monte Carlo noise; larger differences in the sensitivity tables are not; the pass mark of 56 is not. The A signal-to-noise is the mean absolute gap between two ranked rows on the A score divided by the median bootstrap SD of that gap (separability096.py, as on the 0.9.6 card; PREREG09 note of 2026-11-05 19:02Z); spread SD over pair noise is shown beside it.
| pairs resolved, of 105, and A signal-to-noise | 0.9.5 | 0.9.6 | 0.9.7 | 0.9.7.2 |
|---|---|---|---|---|
| CAFE score, datasets resampled (the measure) | 49 | 51 | 61 | 62 |
| CAFE score, datasets fixed (main board) | 73 | 73 | 85 | 90 |
| of which within seed noise | 1 | 1 | 10 | 15 |
| C board, datasets fixed | 70 | 74 | 80 | 80 |
| A board, datasets fixed | 18 | 37 | 60 | 63 |
| FE board, datasets fixed | 87 | 87 | 87 | 87 |
| C board, datasets resampled | 15 | 21 | 25 | 25 |
| A board, datasets resampled | 4 | 6 | 9 | 18 |
| FE board, datasets resampled | 67 | 66 | 67 | 67 |
| A signal-to-noise (the test's measure) | 2.48 | 3.00 | 4.04 | 4.81 |
| A spread SD over pair noise | 2.23 | 2.65 | 3.54 | 4.50 |
Sensitivities of the test raised by the audits (reporting only; the board above is the result):
- With every A dataset resampled by recording (the blocks of one recording form one cluster): 63 pairs resolved and an A signal-to-noise of 4.75; the test fails (test097_cr.json). No rank changes. - With KUKA with its first 100 Eval series in hash order instead of 255 (the cap of 100 for several series per asset): 62 pairs resolved and an A signal-to-noise of 4.80; the test fails (test097_k100.json). No rank changes. - With ipshocks_fluxes on the FE board (check 3 lowered to 900 events; PREREG09 notes of 2026-11-06): 60 pairs resolved and an A signal-to-noise of 4.81; the test fails (test097_ips.json). No rank changes.
On the datasets-resampled boards of 0.9.5 and 0.9.7.2 no pair is resolved in opposite directions.
On the datasets-resampled boards of 0.9.6 and 0.9.7.2 no pair is resolved in opposite directions.
No pair of ranked rows is resolved in opposite directions on the main boards of 0.9.6 and 0.9.7.2, on the CAFE score or on any task board.
Read this beside the conflict-of-interest disclosure in What changed in 0.9.7.2: Forgis staff chose the drops and adds of 0.9.7 with the 0.9.6 board known and the A additions of 0.9.7.2 with the released 0.9.7 board and its per-dataset A separability known (Amendment 15), and Forgis develops the ◊ rows.
0.9.7.2 beside 0.9.7
0.9.7.2 is 0.9.7 with the A datasets admitted under Amendment 15 and the tabular reference rows that 0.9.7 marked pending (planned as card revision v0.9.7-r1 and folded into 0.9.7.2); C and FE are as in 0.9.7. The 0.9.7 numbers come from the released files (results/r0970/, the files under data/ at the Hub tag v0.9.7), the 0.9.7.2 numbers from this build. The test of Amendment 13 item 9 (applied unchanged by Amendment 15 item 4) is the same for both.
| 0.9.7 | 0.9.7.2 | |
|---|---|---|
| datasets C · A · FE | 24 · 10 · 15 | 24 · 13 · 15 |
| A Eval series | 737 | 992 |
| ranked models | 15 | 15 |
| tasks in the CAFE score | C, A, FE | C, A, FE |
| CAFE pairs resolved, main board (datasets fixed) | 85 (10 within seed noise) | 90 (15 within seed noise) |
| CAFE pairs resolved, datasets resampled (the 1.0 measure, of 105) | 61 | 62 |
| C pairs resolved, datasets resampled | 25 | 25 |
| A pairs resolved, datasets resampled | 9 | 18 |
| FE pairs resolved, datasets resampled | 67 | 67 |
| A signal-to-noise (the test's measure) | 4.04 | 4.81 |
| A spread SD over pair noise | 3.54 | 4.50 |
| test of Amendment 13 item 9 (applied unchanged by Amendment 15 item 4) | not passed | not passed |
| CAFE 1.0 candidate after the test | 0.9.5 | 0.9.5 |
| CAFE tier 1 | pj_better_10m ◊ | pj_better_10m ◊ and Mantis |
The test needs at least 56 pairs and an A signal-to-noise of at least 6 (goal 9).
A datasets added in 0.9.7.2 (Amendment 15; dated admission notes in PREREG09): UTAQ (85 Eval series); RCFPOWER (84 Eval series); REASSEMBLE (18 Eval series).
UKWIND changed in 0.9.7.2 (existing, pooled with the later years of the same publisher (Amendment 14 item 2): Kelmarsh and Penmanshiel 2016-2022): 17 → 85 Eval series (12 of the 0.9.7 Eval series kept, 5 fall outside the cap of 100 in hash order, 73 new; UKWIND__K06_b0004, a 0.9.7 Tuning series on which the 0.9.5 readouts were chosen, is now in Eval). Condition as recorded: the 2016 rebuild reproduces all 21 stored 0.8 series byte for byte; 0.8 label rule unchanged; Kelmarsh 2023-2024 left out (each turbine file is 81 overlapping exports, 2.17 M rows for 52,560 timestamps; decided from the file structure before any measurement). Its signal-to-noise was 1.02 in 0.9.7 (the lowest A dataset, known when Amendment 15 was written) and is 3.69 in 0.9.7.2. The mean ◊ lead on it went from +0.0084 to +0.0060. Every row's score on it changes with the material, so its per-dataset scores are not comparable across the two versions.
REASSEMBLE is built from a label-blind partial fetch (zip positions 0 to 78, one failed transfer; 74 recordings after the README known-issue drops, from which the builder's unchanged per-series rules give 18 Eval and 4 Tuning series); a full fetch would roughly double it. It has the lowest A signal-to-noise (1.35); without it 64 pairs are resolved with the datasets resampled (with it 62; a difference within Monte Carlo noise, see the test section). Its cap is 300 although all its series come from one Franka arm; with 18 Eval series neither cap binds.
Tabular reference rows (XGBoost, LightGBM, RealMLP, CatBoost, with their Selected variants; unranked): cells missing on each task board, 0.9.7 → 0.9.7.2: C 36 → 21 (incomplete rows 8 → 6; 24 datasets); A 56 → 26 (incomplete rows 8 → 6; 13 datasets); FE 30 → 25 (incomplete rows 5 → 3; 15 datasets). The missing tabular cells of this run are tasks that ran over the 1-hour per-dataset cap of Amendment 3 (23 tasks: catboost A ESA, catboost A HAI, catboost A HOT, catboost A KUKA, catboost A UAVSEAD, catboost A UKWIND, catboost A UR5E, catboost C nicola15/bdg2_meter6 (selected), catboost FE heatpump_defrost (selected), catboost FE ipshocks_fluxes, catboost FE ipshocks_fluxes (selected), lightgbm FE ipshocks_fluxes (selected), realmlp A KUKA, realmlp FE heatpump_defrost, realmlp FE heatpump_defrost (selected), realmlp FE ipshocks_fluxes, realmlp FE ipshocks_fluxes (selected), xgboost A ESA, xgboost A KUKA, xgboost A UAVSEAD, xgboost A UKWIND, xgboost A UR5E and xgboost FE ipshocks_fluxes (selected)); they were not retried, and the cells of earlier versions that are missing stay missing.
Ranks of the ranked rows, 0.9.7 and 0.9.7.2
| model | rank 0.9.7 | tier 0.9.7 | CAFE 0.9.7 | rank 0.9.7.2 | tier 0.9.7.2 | CAFE 0.9.7.2 | places up |
|---|---|---|---|---|---|---|---|
| pj_better_10m ◊ | 1 | 1 | 0.7384 | 1 | 1 | 0.7405 | = |
| Mantis | 4 | 2 | 0.7326 | 2 | 1 | 0.7385 | +2 |
| pj_better_3p7m ◊ | 2 | 2 | 0.7341 | 3 | 2 | 0.7367 | -1 |
| pjgood-warp-xview-combo-10M ◊ | 3 | 2 | 0.7340 | 4 | 2 | 0.7363 | -1 |
| Chronos-2 | 5 | 2 | 0.7301 | 5 | 2 | 0.7351 | = |
| LeSaturn-warppool-factorized-7.4M ◊ | 6 | 3 | 0.7275 | 6 | 3 | 0.7313 | = |
| pj_better_1m ◊ | 7 | 3 | 0.7241 | 7 | 4 | 0.7264 | = |
| MantisV2 | 8 | 4 | 0.7181 | 8 | 4 | 0.7230 | = |
| NuTime | 9 | 5 | 0.7050 | 9 | 5 | 0.7098 | = |
| Timestral-209M | 10 | 5 | 0.6989 | 10 | 6 | 0.7033 | = |
| Timestral-123M | 11 | 6 | 0.6969 | 11 | 6 | 0.7013 | = |
| Timestral-5M | 14 | 6 | 0.6943 | 12 | 7 | 0.6996 | +2 |
| Timestral-28M | 13 | 6 | 0.6943 | 13 | 7 | 0.6987 | = |
| Toto-Open-Base-1.0 | 12 | 6 | 0.6954 | 14 | 7 | 0.6948 | -2 |
| TimesFM-2.5-200M | 15 | 7 | 0.6662 | 15 | 8 | 0.6703 | = |
What changed in 0.9.7.2
Amendment 13 was written into PREREG09 before any 0.9.7 download, build or cell, with the whole 0.9.6 board known. Amendment 15 (0.9.7.2) was written before any 0.9.7.2 build, measurement or cell on a dataset not yet measured and before any model cell on a 0.9.7.2 candidate, with the released 0.9.7 board and its per-dataset A signal-to-noise known (from 1.0 on UKWIND to 6.1 on KUKA). Four candidates (UTAQ, RCFPOWER, PVLAZ, NOBOOM_M202210) had already been measured without a model for 0.9.7.1 on 2026-11-05 (22:37Z to 22:49Z), so it was known that UTAQ and RCFPOWER pass the admission rules. 0.9.7.1 was never released; its candidates were folded into 0.9.7.2 (Amendment 15 item 1). Amendment 15 keeps C and FE as in 0.9.7 and adds A datasets and the tabular reference rows.
Disclosure of Amendment 15 (as written): the released 0.9.7 board and its per-dataset A separability (signal-to-noise per dataset from 1.0 on UKWIND to 6.1 on KUKA; the task value 4.04 is limited mainly by the noise of the datasets with few Eval series) were known. So were the 0.9.7.1 measurements of 2026-11-05 22:37Z to 22:49Z (UTAQ, RCFPOWER, PVLAZ, NOBOOM_M202210; no model was run on them).
The dated notes after them each give their own time and what had been computed or read when they were written; the admission notes came before any 0.9.7 or 0.9.7.2 cell on the datasets they admit (the two C additions had screening scores before that, see New datasets), and some later notes came after 0.9.7 cells or the 0.9.7 board existed (see the provenance table under Rules). Each model keeps the readout chosen for it in 0.9.5; the C head is the one of Amendment 12; A is scored at w = 256, k = 5, centre assignment, as in 0.9.6.
15 datasets of 0.9.6 are not on the 0.9.7.2 board and 9 are new, plus 2 pooled from 0.9.6 datasets. C has 24 datasets, A 13 and FE 15 (0.9.6: 25, 14, 17).
| task | dataset | change | reason, as recorded |
|---|---|---|---|
| C | mv06/3w | removed or pooled | Amendment 13 item 6 |
| C | mv06/bosch | removed or pooled | Amendment 13 item 6 |
| C | nicola15/soredd_abc | removed or pooled | Amendment 13 item 6 |
| C | nicola15/bdg2_meter6 | added | rebuilt from the exp-nicola-15 builder; X sha256 equals LOG.md (item 6) |
| C | nicola15/robo6_rb6 | added | rebuilt from the exp-nicola-15 builder; X sha256 equals LOG.md (item 6) |
| A | ESA_M1 | removed or pooled | pooled into ESA (Amendment 13 item 2) |
| A | ESA_M2 | removed or pooled | pooled into ESA (Amendment 13 item 2) |
| A | CARE_A | removed or pooled | Amendment 13 item 3: labels cover most of each series, fewer than 15 Eval series (rule 2(a), (c)) |
| A | SMAP | removed or pooled | pooled into NASA (Amendment 13 item 2) |
| A | MSL | removed or pooled | pooled into NASA (Amendment 13 item 2) |
| A | CARE_C | removed or pooled | Amendment 13 item 3: labels cover most of each series, fewer than 15 Eval series (rule 2(a), (c)) |
| A | RIGS | removed or pooled | Amendment 13 item 3: 5 Eval series, 7 segments (rule 2(a), (b)) |
| A | W3 | removed or pooled | Amendment 13 item 3: median anomaly share 0.39 (rule 2(c)); a time-only score reaches 1.000 |
| A | SKAB | removed or pooled | Amendment 13 item 3: 8 Eval series, label to end of file (rule 2(a)) |
| A | ESA | pooled from 0.9.6 datasets | items 2(a)-(c) hold: 95 Eval, 97 segments, median share 0.032; elapsed-time best 0.611 (gate applies to new datasets only) |
| A | NASA | pooled from 0.9.6 datasets | items 2(a)-(c) hold: 37 Eval, 47 segments, median share 0.040; elapsed-time best 0.516 (gate applies to new datasets only) |
| A | UAVSEAD | added | items 2(a)-(c) hold: 101 Eval, 147 segments, median share 0.083; elapsed-time best 0.585 (gate 0.65 holds) |
| A | UR5E | added | items 2(a)-(c) hold: 63 Eval, 74 segments, median share 0.191; elapsed-time best 0.616 (gate 0.65 holds) |
| A | KUKA | added | items 2(a)-(c) hold: 255 Eval, 534 segments, median share 0.108; elapsed-time best 0.519 (gate 0.65 holds) |
| A | UTAQ | added | items 2(a)-(c) hold: 85 Eval, 404 segments, median share 0.027; elapsed-time best 0.560 (gate 0.65) |
| A | RCFPOWER | added | items 2(a)-(c) hold: 84 Eval, 103 segments, median share 0.010; elapsed-time best 0.513 (gate 0.65) |
| A | REASSEMBLE | added | items 2(a)-(c) hold: 18 Eval, 44 segments, median share 0.115; elapsed-time best 0.556 (gate 0.65) |
| FE | epa_aqs_pm25 | removed or pooled | Amendment 13 item 5 |
| FE | substorm_omni | removed or pooled | Amendment 13 item 5 |
| FE | ngafid_hastall | removed or pooled | Amendment 13 item 5 |
| FE | heatpump_defrost | added | item 5 gates hold: 53,978 events >= 300; 113 systems >= 30; time since last event 0.659 <= 0.796; time of day 0.566 <= 0.585; best free forecast 0.729 <= 0.85 |
Datasets of one release or paper are one dataset (Amendment 13 item 2); their series are pooled and the dataset score is the mean over all pooled Eval series: ESA = ESA_M1 + ESA_M2 (95 Eval series); NASA = SMAP + MSL (37 Eval series).
The cap on series per A dataset was raised from 35 (Amendment 13 item 2): 300 for sources whose series are independent physical runs, 100 for sources with several series per asset; Tuning is the first ceil(0.15 m) in hash order, as before.
| A dataset | cap | Eval series | Tuning series | kind |
|---|---|---|---|---|
| ESA | 100 | 95 | 18 | existing, pooled ESA_M1 + ESA_M2 (item 2) |
| NASA | 100 | 37 | 4 | existing, pooled SMAP + MSL (item 2) |
| UKWIND | 100 | 85 | 15 | existing, pooled with the later years of the same publisher (Amendment 14 item 2): Kelmarsh and Penmanshiel 2016-2022 |
| HOT | 100 | 50 | 9 | existing, re-selected under cap 100 |
| PREDIST | 100 | 41 | 8 | existing, re-selected under cap 100 |
| NOBOOM | 300 | 20 | 4 | existing, re-selected under cap 300 (lists unchanged) |
| HAI | 100 | 58 | 11 | existing, pooled with the other HAI releases (item 4) |
| UAVSEAD | 300 | 101 | 18 | new, firm |
| UR5E | 300 | 63 | 12 | new, firm |
| KUKA | 300 | 255 | 45 | new, second wave |
| UTAQ | 100 | 85 | 15 | new (Amendment 14 item 2, Amendment 15) |
| RCFPOWER | 100 | 84 | 15 | new (Amendment 14 item 2, Amendment 15) |
| REASSEMBLE | 300 | 18 | 4 | new (Amendment 14 item 2, Amendment 15) |
NOBOOM is recorded with cap 300, although one distillation plant would fall under the cap of 100 for several series per asset; with 20 Eval series neither cap binds, so its list is the same either way.
A candidates not admitted, with the reason recorded before any cell on them (full measurements under Admission):
| candidate | status | kind | reason |
|---|---|---|---|
| RFLYMAD | out | new, conditional | item 4 elapsed-time gate: 0.731 > 0.65 |
| PMU | out | new, conditional | the continuous 1 s TransnetBW record (Zenodo 15784548) is one channel (CE frequency) and ends 2024-04-25, covering 23 of 88 cases; P4 needs >= 2 channels and 23 cases give at most 19 Eval series and 19 segments (rule 2(b)); not built |
| ONBOARDEU | out | new, conditional | item 4 elapsed-time gate: 0.708 > 0.65 |
| TCABR | out | new, conditional | item 4 elapsed-time gate: 1.000 > 0.65 |
| BASIC | out | new, conditional | check 1 / item 4 condition: the flights are software-in-the-loop, not real (Ahmad and Akram, Data in Brief 2024, doi:10.1016/j.dib.2024.110069: 'The BASiC dataset is exclusively derived from simulations conducted in a SITL environment using the ArduPilot platform'); not built |
| EAWAG | out | new, second wave | only 4 ponds (2D, 3D, 5A, 5B), phase 1, carry the expert 'Anomaly' column, with 5 segments in total: rules 2(a) and 2(b) cannot hold; the licence field is empty (portal: public domain for data outside Swiss copyright) |
| CAFUC2 | out | new, second wave | check 2 (physical label; PREREG09 note of 2026-10-31 ~20:50Z: injected or staged faults pass when the onset is observed in the system): CAFUC2's faults are synthetic signals written into five copies of each recorded flight after the flight; no aircraft experienced them, so the label is not a state of or an event in the physical system. Decided before any cell; only Jonas Petersen can reverse this, in a dated note |
| GREEKWIND | out | new, second wave | 2(a): 7 Eval series < 15; 2(b): 8 anomaly segments < 20 |
| CRANFIELD | out | new, second wave | the official download (MATLAB File Exchange #50938) needs a MathWorks sign-in; the other copies (Kaggle, IEEE DataPort) need a login; item 4 / Amendment 13: sets that need a registration are not added |
| MAST | out | new, second wave | no precursor-only cut without an elapsed-time leak: a scored block that ends before the current quench carries the precursor label at its end (a rising elapsed-time score reaches 0.933 on synthetic series of that shape); TokaMark ships no disruption labels or quench times |
| PVLAZ | out | 0.9.7.1 candidate (Amendment 14), decided under Amendment 15 | rule 2(a): 5 Eval series < 15; item 4 elapsed-time gate 0.683 > 0.65 |
| NOBOOM_M202210 | out | 0.9.7.1 candidate (Amendment 14), decided under Amendment 15 | check 3/4: 85 of its 89 runs are NOBOOM runs with the same X and a second label column (21 kept series byte-identical to NOBOOM series; pooled, 2 Eval pairs and 3 Eval-Tuning pairs share X); NOBOOM stays as in 0.9.7 |
| TSB-AD | out | screened, not built (Amendment 15) | no source collection passes item 2 and checks 1-4 (simulated or injected events, IT/web/finance metrics, recordings of people, imputed or undocumented labels; work/r097/tsbad_screen0972.md); SMAP and MSL stay in NASA, SWaT needs an access form |
| LEAD1.0 | out | screened, not built (Amendment 15) | check 4: its meters are the BDG2 electricity meters of the ASHRAE GEPIII subset, the campaign of the C unit nicola15/bdg2_meter6; no licence stated (data behind a Kaggle login) |
| USGS NWIS | out | screened, not built (Amendment 15) | check 2: on ice-affected stretches the published discharge is an estimate written in place of the record, so the label marks an estimate or a gap, not a recorded event; no equipment-coded stretch found |
The C candidate nicola15/sns_hvcm_b_end had to show a pretraining effect on its own first cells (Amendment 13 item 6): pjgood-warp-xview-combo-10M minus the random-init LeSaturn row (3.7 M parameters, another architecture; not a matched twin of the 10.6 M combo) positive in at least 4 of 5 repeats and a mean of at least +0.02. It was positive in 3 and the mean was +0.0169, so it is out. The gate was not set blind: the exp-nicola-15 screening of the same morning had already scored combo against its random-init twin on this dataset (+0.026 ± 0.021, 4 of 5 repeats; LOG.md), a result that would have passed it. The rule is score-informed; it is computed for every C dataset under Admission.
nicola15/bdg2_meter6 and nicola15/robo6_rb6 were admitted on the sha256 check of item 6 (the rebuilt X equals the one recorded in the screening). That check reads no score, but the screening that accepted them earlier on 2026-11-05 did: it scored pjgood-warp-xview-combo-10M ◊ against its random-init twin on these builds: nicola15/bdg2_meter6 0.649 against 0.597, difference +0.053 ± 0.010, 5 of 5 repeats; nicola15/robo6_rb6 0.603 against 0.501, difference +0.101 ± 0.013, 5 of 5 repeats (exp-nicola-15 LOG.md), so these additions were score-informed too. The combo-minus-twin numbers of 0.9.7 are shown under Admission.
CAFUC2 (general-aviation sorties) is out (2026-11-05T18:56Z): check 2 (physical label; PREREG09 note of 2026-10-31 ~20:50Z: injected or staged faults pass when the onset is observed in the system): CAFUC2's faults are synthetic signals written into five copies of each recorded flight after the flight; no aircraft experienced them, so the label is not a state of or an event in the physical system. Decided before any cell; only Jonas Petersen can reverse this, in a dated note. It would otherwise pass items 2 and 4 (96 Eval series, 286 segments, median share 0.021, elapsed-time best 0.508). Only Jonas Petersen can reverse it, in a dated note.
FE admission is model-free (Amendment 13 item 5): at least 300 events and 30 independent units or days, a time-since-last-event row at most 0.7956 (the highest on the 14 kept FE datasets, nasa_battery_rw), a time-of-day row at most 0.5851 (towie_genbearing_hot), and the best free forecast at most 0.85. The cap on lab-friction sets is three.
Everything else is as in 0.9.6.
Conflict of interest (Amendment 13 item 1, as written before the run): Forgis owns the ◊ rows and Forgis staff chose these rules and drops with the board known. The drops of FEsubstorm_omni,epa_aqs_pm25andngafid_hastalland of Cboschandsoredd_abcwere informed by scores (separability and combo minus twin) and are score-informed selection in the sense of Amendment 3. The A and 3W drops follow the structural rules of item 2 and the 0.9.5 evidence (3W: Amendment 12 era decision of exp-nicola-15). The thresholds of item 2 (15 series, 20 segments, share 0.3) were placed in gaps seen in the 0.9.6 data (kept datasets reach a share of 0.21; the five removed ones start at 0.35), so they are post-hoc cut-offs, not independent ones. The card shows the 0.9.6 board beside 0.9.7, the effect of every drop and add on every row, and the ◊ lead under each.
Note added 2026-11-06: the 3W drop called structural here was made on combo minus twin (item 6 and the exp-nicola-15 screening), so six drops were score-informed, and the two C additions were accepted after a screening that scored a ◊ row on them.
The mean lead of the ◊ rows over the other ranked rows, on the CAFE score, under each board (reported, part of no rule):
| board | mean ◊ row minus mean other ranked row (CAFE) | best ◊ row minus best other row (CAFE) |
|---|---|---|
| 0.9.6 board | +0.0262 | +0.0034 |
0.9.6 with the drops of 0.9.7 and no additions (sensitivity drops_only) | +0.0308 | +0.0073 |
| 0.9.7 board (released) | +0.0284 | +0.0057 |
| 0.9.7.2 board | +0.0268 | +0.0020 |
| A task only, 0.9.7 (first on A: pj_better_10m ◊) | +0.0264 | +0.0107 |
| A task only, 0.9.7.2 (first on A: Mantis) | +0.0215 | -0.0004 |
Every ranked row on the 0.9.6 datasets (computed by the 0.9.7.2 code), on those datasets with the drops of 0.9.7 only (no addition, no pooling), and on 0.9.7.2: CAFE score, rank and tier. The 5 largest gains from the drops alone are exactly the ◊ rows.
| model | 0.9.6 datasets | rank | tier | drops only | change | rank | tier | 0.9.7.2 | rank | tier |
|---|---|---|---|---|---|---|---|---|---|---|
| pj_better_10m ◊ | 0.7363 | 1 | 1 | 0.7480 | +0.0117 | 1 | 1 | 0.7405 | 1 | 1 |
| Mantis | 0.7329 | 3 | 1 | 0.7407 | +0.0078 | 4 | 1 | 0.7385 | 2 | 1 |
| pj_better_3p7m ◊ | 0.7347 | 2 | 1 | 0.7450 | +0.0103 | 2 | 1 | 0.7367 | 3 | 2 |
| pjgood-warp-xview-combo-10M ◊ | 0.7326 | 4 | 1 | 0.7438 | +0.0112 | 3 | 1 | 0.7363 | 4 | 2 |
| Chronos-2 | 0.7301 | 5 | 1 | 0.7389 | +0.0087 | 5 | 1 | 0.7351 | 5 | 2 |
| LeSaturn-warppool-factorized-7.4M ◊ | 0.7270 | 6 | 2 | 0.7386 | +0.0116 | 6 | 1 | 0.7313 | 6 | 3 |
| pj_better_1m ◊ | 0.7224 | 7 | 2 | 0.7315 | +0.0091 | 7 | 2 | 0.7264 | 7 | 4 |
| MantisV2 | 0.7192 | 8 | 2 | 0.7275 | +0.0083 | 8 | 2 | 0.7230 | 8 | 4 |
| NuTime | 0.7067 | 9 | 3 | 0.7108 | +0.0041 | 9 | 3 | 0.7098 | 9 | 5 |
| Timestral-209M | 0.7004 | 10 | 3 | 0.7062 | +0.0057 | 10 | 3 | 0.7033 | 10 | 6 |
| Timestral-123M | 0.6990 | 11 | 3 | 0.7045 | +0.0055 | 11 | 3 | 0.7013 | 11 | 6 |
| Timestral-5M | 0.6965 | 14 | 3 | 0.7024 | +0.0059 | 13 | 3 | 0.6996 | 12 | 7 |
| Timestral-28M | 0.6965 | 13 | 3 | 0.7023 | +0.0057 | 14 | 3 | 0.6987 | 13 | 7 |
| Toto-Open-Base-1.0 | 0.6972 | 12 | 3 | 0.7031 | +0.0058 | 12 | 3 | 0.6948 | 14 | 7 |
| TimesFM-2.5-200M | 0.6657 | 15 | 4 | 0.6699 | +0.0042 | 15 | 4 | 0.6703 | 15 | 8 |
On the 1.0 measure (pairs resolved with the datasets resampled), the 0.9.6 datasets give 51, the drops alone 58 and 0.9.7.2 62: taking the drops first, of the +11 pairs +7 come from the drops, which were chosen with the 0.9.6 board and its separability table known, and +4 from the additions, the pooling and the regrown A lists (another order could split the gain differently).
The dated notes of 0.9.7 and 0.9.7.2 (PREREG09, after Amendment 13, with Amendment 15)
Note 2026-11-05 18:46Z (0.9.7 admission, wave 0: HOT; Amendment 13 item 8 step 2). Written before any 0.9.7 cell on HOT's new series exists. HOT (Hill of Towie, existing A dataset) re-selected under cap 100 (item 2; several series per turbine) with data097/src/select097.py (= select096 with the per-source cap): 59 candidates after construction, chance computed for all 59, none excluded, 59 accepted, 50 Eval and 9 Tuning (0.9.6: 29 and 6). 24 series are new; 3 old Eval series move to Tuning under the unchanged hash rule. Measured with work/r097/measure097.py (validated: reproduces nulls095 HOT to 1.1e-16): 107 anomaly segments in Eval, median scored anomaly share 0.0142, 50 Eval series with prefix >= 512, elapsed-time best 0.529 (centre). Items 2(a), (b), (c) hold: HOT is in. The board uses the stored 0.9.6 cells for the 26 + 3 old series and new cells for the 24 new ones; the old series are also recomputed by the 0.9.7 tree as a reproduction check. Record: data097/admit097.json (wave 0). No 0.9.7 score has been read.
Note 2026-11-05 18:57Z (0.9.7 admission, wave 1; Amendment 13 item 8 step 2). Written before any 0.9.7 cell on the units it admits. Record: data097/admit097.json, generated by work/r097/admit097.py from the measure097.py files (no model read). In (rules 2(a)-(c) hold; the elapsed-time gate holds for the new ones): ESA (ESA_M1 + ESA_M2 pooled, 95 Eval, 97 segments, median share 0.032, elapsed 0.611), NASA (SMAP + MSL pooled, 37, 47, 0.040, 0.516), UKWIND (17, 41, 0.057, 0.558; unchanged), HOT (50, 107, 0.014, 0.529; cap 100), PREDIST (cap 100: 41 Eval, 8 Tuning, was 29 / 6; 41 segments, 0.051, 0.512; 14 new series, PREDIST__m1_s17_e29 and __m2_s19_e29 move to Tuning), NOBOOM (cap 300; lists unchanged: 20, 37, 0.191, 0.561), UAV-SEAD (new, firm: 101 Eval, 147 segments, 0.083, elapsed 0.585 <= 0.65; real PX4 flights; 25 Hz grid chosen on a label-free count of flights reaching a 512-row prefix), UR5e (new, firm, CC BY-NC 4.0: 63 Eval, 74 segments, 0.191, elapsed 0.616; status, safety, program-node, program-loop, digital IO (bit 5 = the labelling button), speed-scaling and time registers dropped). Gates on the existing lists: measure097 equals nulls095/nulls096 per series (max |diff| 2.2e-16); PREDIST and NOBOOM rebuilt from raw reproduce every 0.9.6 series (X, y, tr, channels; PREDIST's unread ts array differs in unit only, pandas version). Out: Eawag (only 4 ponds carry the expert label, 5 segments: rules 2(a), (b) cannot hold), FAIR-MAST (a precursor-only cut puts the label at the end of every scored block, so elapsed time finds it; TokaMark ships no disruption labels), CAFUC2 (check 2: its faults are synthetic signals written into copies of recorded flights after the flight, so the label is not an event in the physical system; 96 Eval would otherwise pass items 2 and 4; Jonas may reverse this in a dated note). Pending: HAI pooling, RflyMAD, BASiC, TCABR, PMU, OnboardEU, KUKA, Cranfield, Greek wind. No 0.9.7 score has been read.
Note 2026-11-05 19:02Z (reading of Amendment 13 item 9, A signal-to-noise; written before any 0.9.7 score exists). Item 9 defines the A signal-to-noise as "spread SD of the ranked rows over their pair noise, as the 0.9.6 card computes it" and anchors it at "the 3.0 of 0.9.6". The 0.9.6 card's number is the snr field of results/separability096.json (separability096.py: mean absolute point difference over all ranked-row pairs of the task score divided by the median bootstrap SD of the paired difference), which is 2.997 for A; spread SD over pair noise is 0.02110 / 0.00795 = 2.65. The test uses the card's quantity, the one that gives 3.0 (threshold 6, goal 9), computed by separability096.py unchanged on board097; spread SD over pair noise is reported beside it for 0.9.5, 0.9.6 and 0.9.7. No rule is changed.
Note 2026-11-05 19:05Z (deviation from Amendment 13 item 6, order of the SNS HVCM gate cells; disclosed, no rule changed). Item 6 says the gate cells of nicola15/sns_hvcm_b_end (combo-10M and its random twin, 5 repeats) are "computed before any other 0.9.7 cell". They were not: A cells of the units admitted in waves 0 and 1 (HOT, PREDIST, UAV-SEAD, UR5e; Clariden jobs 3867625, 3867627, 3867656) were computed first, because the C unit had not been rebuilt yet (nicola-l4 unreachable). No 0.9.7 score of any kind has been read: the only checks run on those cells are equality checks against stored 0.9.6 cells. The SNS rule is mechanical (combo-10M minus twin positive in at least 4 of 5 repeats and mean at least +0.02) and reads only SNS cells, so the order cannot have informed it. Its gate cells are computed as soon as the unit is rebuilt and accepted by the sha256 check, and its decision is written in a dated note before any other 0.9.7 C cell is read. The card states this deviation.
Note 2026-11-05 19:10Z (0.9.7 C admission; Amendment 13 item 6). VM nicola-l4 was unreachable (SSH host key verification failed; not bypassed), so the three exp-nicola-15 C units were rebuilt from their builders (branch dev/c-candidate-checks, builders byte-identical to the logged commits 885ab0cd0, 99988a280, 28ae362c4). X sha256 (raw float32 bytes of prepared.npz X) equals LOG.md for all three: bdg2_meter6 82e03cf1..., robo6_rb6 935ae4ca..., sns_hvcm_b_end b8dcbe28.... In: nicola15/bdg2_meter6 (CC BY-SA 4.0; 75,409 windows, 1,615 groups, 6 classes), nicola15/robo6_rb6 (MIT; 6,869 windows, 5,352 groups, 6 classes). Pending: nicola15/sns_hvcm_b_end (CC BY 4.0; 3,323 windows, 15 groups, 2 classes) until its combo-minus-twin gate (cgate097.py) is computed; its first gate run lost the twin cell to a missing result directory and is being rerun. No 0.9.7 C cell has been read. Record: data097/admit097.json (C section).
Note 2026-11-05 19:12Z (0.9.7 admission, wave 2; Amendment 13 item 8 step 2). Out: BASiC (item 4 condition: its own paper, Ahmad and Akram, Data in Brief 2024, doi:10.1016/j.dib.2024.110069, states the flights are software-in-the-loop simulations; not built) and RflyMAD real flights (built from the real-flight subset only, non-commercial, 255 Eval series, 405 segments, median share 0.289; fails the elapsed-time gate: rising 0.731 > 0.65, the faults come late in the flights). No 0.9.7 score has been read. Record: data097/admit097.json.
Note 2026-11-05 19:13Z (Amendment 13 item 6: SNS HVCM gate). nicola15/sns_hvcm_b_end gate cells (head H1, 5 repeats; combo-10M from Clariden job 3867712, its random twin from 3867716 after the first twin task failed on a missing result directory): combo minus twin per repeat -0.0187, +0.0161, +0.0473, -0.0146, +0.0546; positive in 3 of 5 (needs 4), mean +0.0169 (needs +0.02). SNS HVCM is out of 0.9.7. C has 24 datasets (25 of 0.9.6 minus 3 plus bdg2_meter6 and robo6_rb6). No other 0.9.7 C cell has been read. Record: results/cgate097.json, data097/admit097.json.
Note 2026-11-05 19:15Z (Amendment 13 item 5, F3 thresholds; computed 18:53:31Z, before any new FE download or build). On the 14 kept FE datasets of 0.9.6, from the stored PrecursorBench v1.4 reference curves (no model involved): the time-since-last-event row (PB v1.4 "event timing") reaches at most 0.7956 (nasa_battery_rw); a pure time-of-day row (hour-of-day harmonics 1 and 2 of the last observed sample; defined on the 9 datasets with a calendar) reaches at most 0.5851 (towie_genbearing_hot). A new FE dataset is admitted only if both rows stay at or below these values, with at least 300 events, at least 30 independent units or days, and the best free-forecast row at most 0.85. File: data097/F3_thresholds097.json (copied from the FE builder's output, written 18:53:31Z; the first FE download started 18:54Z per results/timing097.json).
Note 2026-11-05 19:21Z (0.9.7 admission, wave 3; Amendment 13 item 8 step 2). HAI in (pooled, item 4): HAI 22.04 plus 20.07, 21.03 and 23.05 of the same testbed (CC BY-SA 4.0), built with the 22.04 rules; build_hai.py reproduces all 21 old 22.04 series byte for byte. Two run-level decisions, both made before any HAI cell: (i) "hash order unchanged" (item 2) is read as each source keeping its own hash tag, so pooled HAI is ordered with HAI's tag A08|, which puts the 21 old series exactly in their 0.9.5 Eval/Tuning places (with A083| five old series would have moved); select097.py reads an optional hash_tag per source (default A083|); (ii) HAIEnd 23.05 is left out: it carries the same two 23.05 test recordings and the same label file through a different set of tags, so its series repeat physical attacks already in HAI 23.05 ((only Jonas Petersen can reverse this, in a dated note); with it HAI would have 72 Eval series, 134 segments, elapsed 0.527, also passing). Result: 58 Eval, 11 Tuning, 103 segments, median scored share 0.030, elapsed best 0.533. OnboardEU out: clean single-defect subset chosen by the label text before any build (10 of 25 locations), 85 Eval series, but the elapsed-time gate fails (rising 0.708 > 0.65). No 0.9.7 score has been read.
Note 2026-11-05 19:23Z (0.9.7 admission, wave 4, the final A list, and the A gate threshold; Amendment 13 items 4 and 8; before any 0.9.7 A cell is read). In: KUKA LWR4+ collisions (second wave; Zenodo CC BY 4.0, description MIT): 255 Eval series from 148 recordings, 534 segments, median share 0.108, elapsed best 0.519. Its condition holds as written: the labels are the authors' hand-entered collision onsets (y = 1 on [m - 20, m + 492) as in their example.m), whose counts match the experimenter's independent log in 200 of 206 recordings; the external torque at the marked onset varies (coefficient of variation 0.90) and a threshold is crossed a median 5.5 samples after it, so the labels are not thresholds on the torque. Disclosed: a single threshold of about 1.75 Nm on the external-torque channels finds the collisions with F1 0.92, so this dataset is easy for a level detector (the max-|z| reference row will show it). Out: TCABR (the time-matched precursor build gives 3 series because disruptive and normal shots come from different days; the disruptive-only build has elapsed best 1.000 > 0.65), PMU (the continuous 1 s record is one channel and covers 23 of 88 cases: P4 and rule 2(b) fail; not built), Greek wind farm (7 Eval series, 8 segments: rules 2(a), (b)), Cranfield (the official download needs a MathWorks sign-in). Final 0.9.7 A list (10 datasets, 737 Eval series): ESA 95, NASA 37, UKWIND 17, HOT 50, PREDIST 41, NOBOOM 20, HAI 58, UAV-SEAD 101, UR5e 63, KUKA 255. One flight set (UAV-SEAD) of 10, within the cap of a third. A gate threshold (Amendment 5 rule 5(b), recomputed over the final list as item 4 requires): 0.5540 = mean over the 10 datasets of the highest data-free null (centre assignment; per dataset the largest of the Eval means of elapsed time rising, falling and the random window score, from measure097.py): ESA 0.6109, NASA 0.5162, UKWIND 0.5578, HOT 0.5293, PREDIST 0.5124, NOBOOM 0.5605, HAI 0.5328, UAV-SEAD 0.5851, UR5e 0.6156, KUKA 0.5194. A enters the CAFE score if at least half the ranked rows score above it. File: results/agate097.json. No 0.9.7 A cell has been read.
Note 2026-11-05 19:44Z (0.9.7 FE admission, wave 1; Amendment 13 item 5). In: heatpump_defrost (HeatpumpMonitor.org, CC BY 4.0; event = defrost cycle; inputs = measured temperatures and power; built by data097/src/fe_build_heatpump.py with the PrecursorBench v1.4 rule). Model-free gates (reference rows scored as the other FE reference rows, data097/fe_gates_heatpump_defrost.json): 53,978 events (>= 300), 113 independent installations (>= 30), time since last event 0.659 (<= 0.7956), time of day 0.566 (<= 0.5851), best free-forecast row 0.729, curvature (<= 0.85). IPShocks and PyrNet are still building; each is out if not built and gated by 21:30Z. The FE head for the new unit is the torch head of the dated note 011865766 (0.9.6); its reproduction of the 0.9.5 numpy cells holds through the 0.9.7 tree (ZERO on nasa_battery_rw, all draws equal, DECISIONS097.md), so the FT tasks run without a new gate file. No 0.9.7 FE cell has been read.
Note 2026-11-05 21:59Z (0.9.7 FE admission, wave 2, final FE list; Amendment 13 item 5). In: ipshocks_fluxes (IPShocks catalogue, CC BY 4.0, events = shock arrivals at L1; inputs = ACE and Wind field, plasma and particle fluxes from NASA CDAWeb, 1998-2021, 5-min bins). Gates (computed 19:47Z, data097/fe_gates_ipshocks_fluxes.json): 914 events, 629 distinct shock days (independence counted by day because both spacecraft sit at L1), time since last event 0.490, time of day 0.513, best free forecast 0.695 (current value). Builder choices made after a structural test but before any gate score: 1-hour events, lead times 5 min to 4 h, row thinning as build_ngafid. For heatpump_defrost one builder choice was made after a build and before any score: feed stretches shorter than 1,024 min are set missing. Out: PyrNet (not built and gated by the 21:30Z cutoff). Final FE list: the 14 kept datasets plus heatpump_defrost and ipshocks_fluxes = 16. Disclosed: on two kept FE datasets the best free-forecast row is already above the 0.85 gate that new FE datasets must meet (memristor_jerk 0.882, nasa_battery_rw 0.873; data097/F3_thresholds097.json); the gate applies to new datasets only, so they stay. No 0.9.7 FE cell has been read.
Note 2026-11-05 22:32Z (responses to audits 1 and 2; disclosures; no rule changed). Two fresh audits (work/r097/audits/audit1_rules.md, audit2_code.md) found no blocker. Context: at about 22:10Z a provisional board (the two new FE datasets and two HAI rows still without cells) was built to check the code end to end, so 0.9.7 scores have been visible since then; for that reason no admission rule or decision below is changed now, and every response is a disclosure or a reporting-only sensitivity. 1. KUKA cap (audit 1 R1, audit 2 F8). KUKA was admitted at 19:23Z (before any A cell was read) with cap 300, reading its 206 recordings as independent runs of a robot program, as UR5e's runs were read; item 2 gives 100 to "several series per asset", and KUKA is one robot arm with several blocks per recording (255 Eval series from 148 recordings). The cap stays as admitted. Reported beside the result: the board and the item-9 test with KUKA at its first 100 Eval series in hash order (results/test097_k100.json). 2. Within-dataset independence (audit 1 R2, audit 2 F9). The A bootstrap resamples series, as in 0.9.6 (item 7); blocks of one recording (HAI, KUKA, ESA, UAV-SEAD, HOT, UKWIND) are resampled as if independent except the near-duplicate clusters of 0.9.5. Reported beside the result: the board and the item-9 test with every A dataset resampled by recording (results/test097_cr.json). 3. PyrNet cutoff (audit 1 R3). The 21:30Z cutoff for the FE builds was set by the orchestrator at 19:45Z in a message to the builder (data097/fe_status097.md); it is not in Amendment 13 (whose item 8 has no deadline beyond the plan's budget) and is earlier than the plan's suggested 4-hour phase-1 cut-off (~22:42Z). PyrNet's 4.8 GB download finished at 21:58Z and its builder never ran. PyrNet is not in 0.9.7; it is a 0.9.7.1 candidate. 4. Wording of the 19:02Z note (audit 1 R4). That note says "before any 0.9.7 score exists"; A cells of waves 0 and 1 existed from 18:49Z but none had been read. Read it as "before any 0.9.7 score was read". 5. A_series gate tolerance (audit 1 R6). The gate comparing recomputed old series with their stored cells was exact until PREDIST and HAI were recomputed; it now allows 1e-15 (written 22:16Z, after the 1.1e-16 differences appeared) because select097 recomputed those datasets' chance values (difference about 1e-17). The board uses the stored cells for every old series, so no score depends on it; the bit-for-bit gate of one unchanged unit per task (A_repro, 49/49 exact) is unchanged. 6. FE caveats (audit 1 R8, R10). heatpump_defrost's event (heat output below 0 W while the compressor draws more than 50 W) is defined partly on electrical power, which is also an input; the F3 thresholds were computed from 10 head seeds on the kept datasets and the new datasets' gate rows from 3. Both are stated on the card. 7. Other disclosures. UAV-SEAD keeps battery voltage, which falls through a flight (its elapsed-time score is 0.585, inside the gate) (audit 1 R13). The SNS gate compared combo-10M with the board's random-init LeSaturn row (3.7M parameters), the twin used for "combo minus twin" since 0.9.6 (audit 1 R16). A at w = 512 (item 7) is not computed in this run unless time remains (audit 1 R11). The leave-one-out boards hold every non-admitted dataset out so that a campaign sibling cannot enter (fixed in sens097.py at 22:06Z, before the final board).
Note 2026-11-06 10:02Z (ipshocks_fluxes and standing check 3; written after the 0.9.7 board was built, before any ipshocks_fluxes score was read). The board leaves ipshocks_fluxes out under the standing admission check 3 (section "Admission", item 3: "FE: at least 1,000 events"), which Amendment 13 item 7 keeps ("everything else is 0.9.6"): it has 914 events. Amendment 13 item 5 sets the gates for new FE datasets (at least 300 events, at least 30 independent units or days, F3, best free forecast at most 0.85), and the note of 21:59Z admitted it under those gates as the 16th FE dataset; neither text says whether the 300-event gate replaces check 3 for new FE datasets. The conflict was not seen before: the provisional runs of 22:00Z to 22:30Z had no cells on the new FE units and left them out for that reason. The board code (board097.py, unchanged since before any 0.9.7 score) applies check 3, and the run's escalation rule takes the default "leave the unit out" when a decision needs Jonas Petersen. 0.9.7 therefore has 15 FE datasets; ipshocks_fluxes is listed as admitted by item 5 and left out by check 3. Its cells exist (Clariden job 3868625) and are kept. Only Jonas Petersen can reverse this, in a dated note; the board would then be rebuilt with 16 FE datasets and every result file regenerated. The 0.9.7 test of item 9, the tiers and every reported number are those of the 15-dataset board. No ipshocks_fluxes score has been read.
Note 2026-11-06 10:10Z (addendum to the note of 10:02Z, after audit 3 finding F-A1; no rule changed). The 10:02Z note says no ipshocks_fluxes score had been read. The writer had not looked at one, but that cannot be shown: the cells of every row on ipshocks_fluxes were in ~/.hepa09/r097/cells097/F.json from the build of about 09:25Z and in the card's data/F.json. Audit 3 then built the board with ipshocks_fluxes (check 3 lowered to 900 events) as a check. That board is now a reported sensitivity (results/board097_ips.json, test097_ips.json; release097.sh), shown on the card beside the test. Any reversal of the 10:02Z default would therefore be made with those scores known, and the card would say so. The published board stays the 15-FE-dataset board.
Note 2026-11-06 11:05Z (decision on ipshocks_fluxes by Jonas Petersen; closes the notes of 10:02Z and 10:10Z). Jonas Petersen decided: ipshocks_fluxes stays out of 0.9.7. Standing check 3 (FE at least 1,000 events) holds for every FE dataset, new ones included; Amendment 13 item 5's 300-event gate is an additional gate for new FE datasets and does not replace check 3. The decision was made with the board with ipshocks_fluxes known (sensitivity results/board097_ips.json: 58 pairs resolved against 61, pj_better_3p7m and pjgood-warp-xview-combo-10M swap ranks 2 and 3; the item-9 test fails either way), and is the default the run took at 10:02Z. 0.9.7 has 15 FE datasets.
Amendment 15 (CAFE 0.9.7.2, written 2026-11-06 ~23:50Z (first headed 2026-11-07 ~00:10Z, a clock error; commit 199d87582 at 23:51:45Z), before any 0.9.7.2 build, measurement or cell on a dataset not yet measured, and before any model cell on a 0.9.7.1 or 0.9.7.2 candidate; the released 0.9.7 board, card and tags are not changed by it). Requested by Jonas Petersen on 2026-11-06 at ~23:45Z: a 0.9.7.2 with more audits, more robustness checks and more separability on A, adding further A datasets that pass every rule (the TSB-AD collection named as a source), aiming at an A signal-to-noise above 9; published with the earlier versions kept on the leaderboard, and checked so that the 1.0 conversion can run on his go. Disclosure: the released 0.9.7 board and its per-dataset A separability (signal-to-noise per dataset from 1.0 on UKWIND to 6.1 on KUKA; the task value 4.04 is limited mainly by the noise of the datasets with few Eval series) were known. So were the 0.9.7.1 measurements of 2026-11-05 22:37Z to 22:49Z (UTAQ, RCFPOWER, PVLAZ, NOBOOM_M202210; no model was run on them). Conflict of interest: as in Amendment 13 item 1. 1. Versions. 0.9.7.1 was never built past the measurements or published. Amendment 14's candidates are carried into 0.9.7.2, and the name 0.9.7.1 is not used for a release. The tabular reference update planned as card revision v0.9.7-r1 is also folded into 0.9.7.2. 2. Rules. Amendment 13 items 2 and 4 and Amendment 14 items 1 and 2 are unchanged and apply to every candidate, measured with measure097.py before any cell. Checks 1 to 4 of Amendment 8 apply as written (physical system, physical label, test material, one dataset per campaign). No existing A dataset is dropped or changed, except by a pooling that Amendment 14 already names (NOBOOM_M202210 into NOBOOM; the later UKWIND years into UKWIND). 3. TSB-AD. Each source collection in TSB-AD-U and TSB-AD-M is judged on its own against item 2, from the publisher's original files where TSB-AD has cut, resampled or normalized them. Sources already decided keep their decision (SMAP and MSL are in NASA; SWaT needs an access form; SKAB was removed by Amendment 13). Sources whose anomalies were injected into recorded data by software, simulated plants, IT or web metrics, and recordings of people or animals fail check 1 or check 2 and are listed with that reason. 4. The 0.9.7.2 board is the 0.9.7 board plus the admitted A datasets and the tabular reference rows. C and FE do not change. Item 9 of Amendment 13 applies unchanged: at least 56 of the 105 pairs resolved with the datasets resampled, and an A signal-to-noise of at least 6 (goal 9). 0.9.7 is shown beside 0.9.7.2. If 0.9.7.2 passes, it is the 1.0 candidate; the conversion still runs only on Jonas's explicit go. 5. Order of work and cut-off. As Amendment 13 item 8: build and measure, then a dated admission note, then cells. A candidate whose units are not on Clariden by 2026-11-07 03:30Z is not in 0.9.7.2. Its builder and measurement are handed over in a ranked list. A candidate on which any ranked row has no cell after two attempts leaves 0.9.7.2 as a whole, with the reason on the card. No admission, pooling or cut-off decision reads a model score on a candidate. 6. Exit. At least three fresh audits, the last two in a row with no blocker, before the upload (Amendment 5 rule 13 for 1.0 is unchanged).
Note 2026-11-06 23:54Z (first headed 2026-11-07 00:35Z, a clock error; commit dcf9de80a at 23:54:39Z) (0.9.7.2 admission, wave 1; Amendment 15 item 5; before any model cell on the dataset). In: UTAQ, the Utah aquatic sensor networks (Logan River Observatory with the iUTAH GAMUT Red Butte and Provo networks; HydroShare, CC BY 4.0, open). Measured on 2026-11-05 at 22:49Z with measure097.py, no model run: 85 Eval and 15 Tuning series (site-year P2 blocks, cap 100), 404 anomaly segments in Eval, median scored anomaly share 0.027, all 85 Eval series with a prefix of at least 512, elapsed-time best 0.560 (centre; gate 0.65). Rules 2(a), 2(b), 2(c) and the elapsed-time gate hold. Amendment 14's condition holds as built: the label is the union of the technicians' qualifier codes for sensor malfunction, power failure, maintenance, sediment, low water and calibration, fixed in the builder before any series was built (~/stage097/logs/build_utaq_labelrule_frozen_2240Z.py, 22:40Z), and the inputs are the raw logger files, not the quality-controlled files. Checks 1 to 4 of Amendment 8: in-stream sondes are a physical system; the qualifier codes mark instrument and site events entered by technicians, not thresholds; Eval and Tuning are disjoint site-year blocks; the three networks are one dataset (same authors, item 2 pooling rule). Not a flight set. The A gate threshold is recomputed over the final 0.9.7.2 A list in the note that closes the list, before any 0.9.7.2 A cell is read.
Note 2026-11-07 00:02Z (first headed 00:15Z, a clock error; commit a1f71c5f6) (Amendment 15 item 3 result; two further candidates named before any download or build of them). TSB-AD: no source collection passes (work/r097/tsbad_screen0972.md). GHL, CATSv2 and Exathlon are simulated or carry injected events; SMD, PSM, WSD, IOPS, NEK, YAHOO, Stock and CreditCard are IT, web or finance metrics; MITDB, SVDB, LTDB, Daphnet and OPPORTUNITY record people; GECCO's events were imputed by the organisers; TAO has no documented label and no series with a 512-sample prefix; Power labels holidays; Genesis needs a login; NAB has two physical non-human series; the UCR families are synthetic or hand-edited anomalies with no 15 independent series from one campaign. SMAP and MSL stay in NASA; SWaT needs an access form. Nothing was built. Named as candidates under the unchanged rules of item 2 (each out unless it passes every rule and checks 1 to 4 when built): LEAD1.0 (building electricity meters with human-annotated anomalies; admitted only if its labels are human annotations of recorded events, the licence is usable, and it is not the same campaign as the C unit nicola15/bdg2_meter6, which is drawn from BDG2; if it is, it is out under check 4); USGS NWIS gauges with equipment or ice qualifier codes (admitted only if the qualified stretches keep the recorded signal in the published record). No score of any kind exists on either.
Note 2026-11-07 00:10Z (committed 00:07:31Z as 4683f1fec; the heading time was written ahead of the clock) (the two candidates of the 00:02Z note; no download of model data, no build, no score). Out: LEAD1.0, check 4: its meters are the BDG2 electricity meters of the ASHRAE GEPIII subset (LEAD paper, arXiv 2203.17256; BDG2 README), the campaign the C unit nicola15/bdg2_meter6 is built from; it would also fail the licence rule (no licence stated; the full data sit behind a Kaggle competition login). Its labels would have passed (people annotated every point with a web tool). USGS NWIS: on ice-affected stretches the published discharge is an estimate written in place of the record and the recorded gage height carries no qualifier, so the label marks an estimate or a gap, not a recorded event (check 2); no equipment-coded stretch was found in the probes.
Note 2026-11-07 01:45Z (committed 01:42:32Z as bced91633; the heading time was written ahead of the clock) (0.9.7.2 admission, wave 2, the final 0.9.7.2 A list and the A gate threshold; Amendment 15 item 5; before any model cell on the wave-2 datasets and before any 0.9.7.2 A cell is read). Measured with measure097.py, no model run (builders in data097/src/, record data097/admit0972.json from admit0972.py). In: RCFPOWER (Zenodo, CC BY 4.0): 84 Eval series, 103 segments, median share 0.010, elapsed best 0.513, all with a prefix of 512. Amendment 14's condition holds: only the physically induced categories are labelled (load, voltage, frequency, power quality, outage; sensor, context and compound categories excluded), 136 such events (109 without the gradual-drift and flicker types, whose induction protocol the datasheet does not state). UKWIND pooled with the later years of the same publisher (Amendment 14): Kelmarsh and Penmanshiel 2016 to 2022, 85 Eval series under the cap of 100 in hash order, 128 segments, median share 0.027, elapsed best 0.541; the 2016 rebuild reproduces all 21 stored series byte for byte. Kelmarsh 2023 and 2024 are left out because each turbine file holds 81 overlapping exports (2.17 million rows for 52,560 timestamps), which the unchanged 0.8 builder cannot read without a new de-duplication rule; this was decided from the file structure before any UKWIND measurement. Of the 17 Eval series of 0.9.7, 12 stay in Eval and 5 fall outside the cap. The inherited flag of 0.8 stays: availability and lost-production channels computed by the SCADA are inputs. REASSEMBLE (TU Wien, CC BY 4.0): 18 Eval series, 44 segments, median share 0.115, elapsed best 0.556. Its condition holds: the files hold only measured robot state (no command or haptic-master stream) and the failed actions are physical outcomes (196 of 1,957 action segments). Disclosed: the fetch was stopped at 00:57Z because the VM was overloaded, so REASSEMBLE is built from the recordings at zip positions 0 to 78 (one failed transfer), a label-blind subset; 74 recordings after the README known-issue drops give 18 Eval series. Fetching the rest (about 35 GB) would roughly double them; it is handed over. Out: PVLAZ (rule 2(a), 5 Eval series; elapsed-time gate 0.683). NOBOOM_M202210: 85 of its 89 runs are NOBOOM runs with the same inputs and a second label column (21 of its kept series are byte-identical to NOBOOM series, and the pooled list would put identical inputs in Eval twice and in Eval and Tuning), so it adds no new test material (checks 3 and 4); NOBOOM stays as in 0.9.7. Final 0.9.7.2 A list (13 datasets, 992 Eval series): ESA 95, NASA 37, UKWIND 85, HOT 50, PREDIST 41, NOBOOM 20, HAI 58, UAV-SEAD 101, UR5e 63, KUKA 255, UTAQ 85, RCFPOWER 84, REASSEMBLE 18. One flight set (UAV-SEAD) of 13. A gate threshold (Amendment 5 rule 5(b), recomputed over the final list): 0.5502 = mean over the 13 datasets of the highest data-free null (centre): ESA 0.6109, NASA 0.5162, UKWIND 0.5408, HOT 0.5293, PREDIST 0.5124, NOBOOM 0.5605, HAI 0.5328, UAV-SEAD 0.5851, UR5e 0.6156, KUKA 0.5194, UTAQ 0.5604, RCFPOWER 0.5130, REASSEMBLE 0.5560. No 0.9.7.2 A cell has been read (UTAQ's cells exist on Clariden and were only checked for completeness).
Comparison across versions since 0.9.4
The versions differ in datasets, heads and, for 0.9.4, in the ranked rows (TiRex-2 is ranked in 0.9.4 only), so scores of different versions are means over different material; ranks, tiers and resolved pairs are what can be compared. 0.9.4 is the released 0.9.4 board, unchanged in 0.9.4.1 (board094_frozen.json).
Datasets and pairs resolved. Main board: datasets fixed, test material resampled. Datasets resampled: the measure of the 1.0 test.
| version | C datasets | A datasets | FE datasets | ranked models | tasks in CAFE | CAFE pairs resolved, main | of | CAFE pairs resolved, datasets resampled | of |
|---|---|---|---|---|---|---|---|---|---|
| 0.9.4 (0.9.4.1) | 16 | 7 | 16 | 16 | C, A, FE | 39 (1 within seed noise) | 120 | 16 | 120 |
| 0.9.5 | 17 | 12 | 16 | 15 | C, A, FE | 73 (1 within seed noise) | 105 | 49 | 105 |
| 0.9.6 | 25 | 14 | 17 | 15 | C, A, FE | 73 (1 within seed noise) | 105 | 51 | 105 |
| 0.9.7 | 24 | 10 | 15 | 15 | C, A, FE | 85 (10 within seed noise) | 105 | 61 | 105 |
| 0.9.7.2 | 24 | 13 | 15 | 15 | C, A, FE | 90 (15 within seed noise) | 105 | 62 | 105 |
Per task. Pairs resolved on the task board, main / datasets resampled, and signal-to-noise (mean absolute gap between two ranked rows over the median bootstrap SD of that gap; separability096.py). A dash: no such file for that version.
| version | C pairs | A pairs | FE pairs | C signal-to-noise | A signal-to-noise | FE signal-to-noise | CAFE signal-to-noise |
|---|---|---|---|---|---|---|---|
| 0.9.4 (0.9.4.1) | 73 / – | 24 / – | 69 / – | – | – | – | – |
| 0.9.5 | 70 / 15 | 18 / 4 | 87 / 67 | 8.39 | 2.48 | 15.10 | 7.32 |
| 0.9.6 | 74 / 21 | 37 / 6 | 87 / 66 | 8.98 | 3.00 | 14.93 | 7.89 |
| 0.9.7 | 80 / 25 | 60 / 9 | 87 / 67 | 10.06 | 4.04 | 16.26 | 10.88 |
| 0.9.7.2 | 80 / 25 | 63 / 18 | 87 / 67 | 10.06 | 4.81 | 16.26 | 12.20 |
No separability file exists for 0.9.4.
First place. The first row of each board; inside tier 1 the order is no claim.
| version | CAFE | C | A | FE | models in CAFE tier 1 |
|---|---|---|---|---|---|
| 0.9.4 (0.9.4.1) | MantisV2 | Timestral-209M | Timestral-123M | pj_better_1m ◊ | 13 |
| 0.9.5 | pj_better_10m ◊ | Chronos-2 | pj_better_3p7m ◊ | Mantis | 6 |
| 0.9.6 | pj_better_10m ◊ | Chronos-2 | pj_better_3p7m ◊ | Mantis | 5 |
| 0.9.7 | pj_better_10m ◊ | Chronos-2 | pj_better_10m ◊ | Mantis | 1 |
| 0.9.7.2 | pj_better_10m ◊ | Chronos-2 | Mantis | Mantis | 2 |
Rank and tier of each ranked model on the CAFE score, rank (tier):
| model | 0.9.4 (0.9.4.1) | 0.9.5 | 0.9.6 | 0.9.7 | 0.9.7.2 |
|---|---|---|---|---|---|
| pj_better_10m ◊ | 6 (1) | 1 (1) | 1 (1) | 1 (1) | 1 (1) |
| Mantis | 4 (1) | 3 (1) | 3 (1) | 4 (2) | 2 (1) |
| pj_better_3p7m ◊ | 7 (1) | 2 (1) | 2 (1) | 2 (2) | 3 (2) |
| pjgood-warp-xview-combo-10M ◊ | 5 (1) | 4 (1) | 4 (1) | 3 (2) | 4 (2) |
| Chronos-2 | 12 (1) | 5 (1) | 5 (1) | 5 (2) | 5 (2) |
| LeSaturn-warppool-factorized-7.4M ◊ | 10 (1) | 6 (1) | 6 (2) | 6 (3) | 6 (3) |
| pj_better_1m ◊ | 9 (1) | 7 (2) | 7 (2) | 7 (3) | 7 (4) |
| MantisV2 | 1 (1) | 8 (2) | 8 (2) | 8 (4) | 8 (4) |
| NuTime | 14 (2) | 9 (3) | 9 (3) | 9 (5) | 9 (5) |
| Timestral-209M | 3 (1) | 10 (3) | 10 (3) | 10 (5) | 10 (6) |
| Timestral-123M | 2 (1) | 11 (3) | 11 (3) | 11 (6) | 11 (6) |
| Timestral-5M | 13 (1) | 12 (3) | 14 (3) | 14 (6) | 12 (7) |
| Timestral-28M | 11 (1) | 13 (3) | 13 (3) | 13 (6) | 13 (7) |
| Toto-Open-Base-1.0 | 15 (3) | 14 (3) | 12 (3) | 12 (6) | 14 (7) |
| TimesFM-2.5-200M | 16 (3) | 15 (4) | 15 (4) | 15 (7) | 15 (8) |
| TiRex-2 | 8 (1) | – | – | – | – |
What changed, by the amendments of each version and the datasets added (+) or removed (-) against the version before:
| version | rules | datasets |
|---|---|---|
| 0.9.4 (0.9.4.1) | Amendment 5 | first version compared |
| 0.9.5 | Amendments 6, 7, 8, 9 and 10 | C: +2 (aursad095, voraus095) -1 (voraus); A: +5 (ESA_M1, CARE_A, MSL, W3, SKAB) |
| 0.9.6 | Amendments 11 and 12 | C: +8 (chillan5, haptic_texture8, openrainer_m, poseit_ft, px4_airframe3, soredd_abc, swiss_load10, ved_powertrain3); A: +2 (PREDIST, NOBOOM); FE: +1 (ngafid_hastall) |
| 0.9.7 | Amendment 13 | C: +2 (bdg2_meter6, robo6_rb6) -3 (3w, bosch, soredd_abc); A: +5 (ESA, NASA, UAVSEAD, UR5E, KUKA) -9 (ESA_M1, ESA_M2, CARE_A, SMAP, MSL, CARE_C, RIGS, W3, SKAB); FE: +1 (heatpump_defrost) -3 (epa_aqs_pm25, substorm_omni, ngafid_hastall) |
| 0.9.7.2 | Amendment 15 | A: +3 (UTAQ, RCFPOWER, REASSEMBLE) |
Each version's own changes are in the change log.
0.9.6 and 0.9.7.2 side by side
Scores of the two versions are means over different datasets, so a change in score is not a change in the model; ranks and tiers are what can be compared.
Ranked rows of both versions, in the 0.9.7.2 order.
| model | rank 0.9.6 | rank 0.9.7.2 | move | tier 0.9.6 | tier 0.9.7.2 | score 0.9.6 | score 0.9.7.2 | change |
|---|---|---|---|---|---|---|---|---|
| pj_better_10m ◊ | 1 | 1 | = | 1 | 1 | 0.7363 | 0.7405 | +0.0042 |
| Mantis | 3 | 2 | ↑1 | 1 | 1 | 0.7329 | 0.7385 | +0.0056 |
| pj_better_3p7m ◊ | 2 | 3 | ↓1 | 1 | 2 | 0.7347 | 0.7367 | +0.0020 |
| pjgood-warp-xview-combo-10M ◊ | 4 | 4 | = | 1 | 2 | 0.7326 | 0.7363 | +0.0036 |
| Chronos-2 | 5 | 5 | = | 1 | 2 | 0.7301 | 0.7351 | +0.0050 |
| LeSaturn-warppool-factorized-7.4M ◊ | 6 | 6 | = | 2 | 3 | 0.7270 | 0.7313 | +0.0043 |
| pj_better_1m ◊ | 7 | 7 | = | 2 | 4 | 0.7224 | 0.7264 | +0.0040 |
| MantisV2 | 8 | 8 | = | 2 | 4 | 0.7192 | 0.7230 | +0.0038 |
| NuTime | 9 | 9 | = | 3 | 5 | 0.7067 | 0.7098 | +0.0030 |
| Timestral-209M | 10 | 10 | = | 3 | 6 | 0.7004 | 0.7033 | +0.0029 |
| Timestral-123M | 11 | 11 | = | 3 | 6 | 0.6990 | 0.7013 | +0.0023 |
| Timestral-5M | 14 | 12 | ↑2 | 3 | 7 | 0.6965 | 0.6996 | +0.0032 |
| Timestral-28M | 13 | 13 | = | 3 | 7 | 0.6965 | 0.6987 | +0.0022 |
| Toto-Open-Base-1.0 | 12 | 14 | ↓2 | 3 | 7 | 0.6972 | 0.6948 | −0.0024 |
| TimesFM-2.5-200M | 15 | 15 | = | 4 | 8 | 0.6657 | 0.6703 | +0.0046 |
Ranked rows of both versions, in the 0.9.7.2 order. 25 datasets in 0.9.6, 24 in 0.9.7.2.
| model | rank 0.9.6 | rank 0.9.7.2 | move | tier 0.9.6 | tier 0.9.7.2 | score 0.9.6 | score 0.9.7.2 | change |
|---|---|---|---|---|---|---|---|---|
| Chronos-2 | 1 | 1 | = | 1 | 1 | 0.8365 | 0.8442 | +0.0077 |
| pjgood-warp-xview-combo-10M ◊ | 3 | 2 | ↑1 | 1 | 1 | 0.8337 | 0.8429 | +0.0092 |
| Timestral-209M | 2 | 3 | ↓1 | 1 | 1 | 0.8347 | 0.8411 | +0.0064 |
| Timestral-123M | 4 | 4 | = | 1 | 2 | 0.8327 | 0.8389 | +0.0062 |
| pj_better_10m ◊ | 5 | 5 | = | 2 | 2 | 0.8297 | 0.8380 | +0.0083 |
| pj_better_3p7m ◊ | 7 | 6 | ↑1 | 2 | 2 | 0.8275 | 0.8348 | +0.0072 |
| Timestral-28M | 6 | 7 | ↓1 | 2 | 3 | 0.8290 | 0.8347 | +0.0057 |
| Mantis | 9 | 8 | ↑1 | 3 | 4 | 0.8225 | 0.8294 | +0.0069 |
| LeSaturn-warppool-factorized-7.4M ◊ | 8 | 9 | ↓1 | 3 | 4 | 0.8232 | 0.8291 | +0.0059 |
| NuTime | 10 | 10 | = | 3 | 4 | 0.8215 | 0.8266 | +0.0052 |
| Timestral-5M | 11 | 11 | = | 3 | 4 | 0.8213 | 0.8258 | +0.0044 |
| MantisV2 | 12 | 12 | = | 3 | 4 | 0.8186 | 0.8257 | +0.0071 |
| pj_better_1m ◊ | 13 | 13 | = | 4 | 5 | 0.8150 | 0.8206 | +0.0057 |
| TimesFM-2.5-200M | 14 | 14 | = | 5 | 6 | 0.7952 | 0.8021 | +0.0068 |
| Toto-Open-Base-1.0 | 15 | 15 | = | 6 | 7 | 0.7678 | 0.7726 | +0.0048 |
Ranked rows of both versions, in the 0.9.7.2 order. 14 datasets in 0.9.6, 13 in 0.9.7.2.
| model | rank 0.9.6 | rank 0.9.7.2 | move | tier 0.9.6 | tier 0.9.7.2 | score 0.9.6 | score 0.9.7.2 | change |
|---|---|---|---|---|---|---|---|---|
| Mantis | 5 | 1 | ↑4 | 1 | 1 | 0.6634 | 0.6552 | −0.0082 |
| pj_better_10m ◊ | 3 | 2 | ↑1 | 1 | 1 | 0.6718 | 0.6548 | −0.0170 |
| pj_better_3p7m ◊ | 1 | 3 | ↓2 | 1 | 1 | 0.6762 | 0.6544 | −0.0218 |
| pjgood-warp-xview-combo-10M ◊ | 2 | 4 | ↓2 | 1 | 1 | 0.6727 | 0.6531 | −0.0196 |
| pj_better_1m ◊ | 6 | 5 | ↑1 | 1 | 1 | 0.6628 | 0.6485 | −0.0143 |
| MantisV2 | 4 | 6 | ↓2 | 1 | 1 | 0.6649 | 0.6482 | −0.0167 |
| NuTime | 7 | 7 | = | 1 | 1 | 0.6603 | 0.6475 | −0.0128 |
| LeSaturn-warppool-factorized-7.4M ◊ | 8 | 8 | = | 2 | 1 | 0.6518 | 0.6409 | −0.0109 |
| Chronos-2 | 9 | 9 | = | 2 | 1 | 0.6508 | 0.6404 | −0.0103 |
| Timestral-5M | 13 | 10 | ↑3 | 2 | 2 | 0.6381 | 0.6294 | −0.0087 |
| Timestral-209M | 10 | 11 | ↓1 | 2 | 2 | 0.6420 | 0.6293 | −0.0127 |
| Timestral-28M | 12 | 12 | = | 2 | 2 | 0.6402 | 0.6275 | −0.0127 |
| Timestral-123M | 11 | 13 | ↓2 | 2 | 2 | 0.6405 | 0.6266 | −0.0139 |
| TimesFM-2.5-200M | 15 | 14 | ↑1 | 3 | 3 | 0.6031 | 0.6008 | −0.0023 |
| Toto-Open-Base-1.0 | 14 | 15 | ↓1 | 2 | 4 | 0.6141 | 0.5836 | −0.0305 |
Ranked rows of both versions, in the 0.9.7.2 order. 17 datasets in 0.9.6, 15 in 0.9.7.2.
| model | rank 0.9.6 | rank 0.9.7.2 | move | tier 0.9.6 | tier 0.9.7.2 | score 0.9.6 | score 0.9.7.2 | change |
|---|---|---|---|---|---|---|---|---|
| Mantis | 1 | 1 | = | 1 | 1 | 0.7129 | 0.7310 | +0.0181 |
| pj_better_10m ◊ | 3 | 2 | ↑1 | 1 | 1 | 0.7073 | 0.7288 | +0.0215 |
| Toto-Open-Base-1.0 | 2 | 3 | ↓1 | 1 | 1 | 0.7098 | 0.7282 | +0.0184 |
| LeSaturn-warppool-factorized-7.4M ◊ | 4 | 4 | = | 1 | 1 | 0.7061 | 0.7240 | +0.0179 |
| pj_better_3p7m ◊ | 6 | 5 | ↑1 | 2 | 2 | 0.7003 | 0.7210 | +0.0207 |
| Chronos-2 | 5 | 6 | ↓1 | 2 | 2 | 0.7031 | 0.7208 | +0.0177 |
| pjgood-warp-xview-combo-10M ◊ | 7 | 7 | = | 3 | 3 | 0.6915 | 0.7127 | +0.0212 |
| pj_better_1m ◊ | 8 | 8 | = | 3 | 3 | 0.6896 | 0.7102 | +0.0206 |
| MantisV2 | 9 | 9 | = | 4 | 4 | 0.6741 | 0.6951 | +0.0209 |
| NuTime | 10 | 10 | = | 5 | 5 | 0.6385 | 0.6553 | +0.0168 |
| Timestral-5M | 11 | 11 | = | 5 | 6 | 0.6300 | 0.6437 | +0.0137 |
| Timestral-209M | 12 | 12 | = | 6 | 6 | 0.6246 | 0.6396 | +0.0150 |
| Timestral-123M | 13 | 13 | = | 6 | 6 | 0.6240 | 0.6384 | +0.0145 |
| Timestral-28M | 14 | 14 | = | 6 | 7 | 0.6204 | 0.6340 | +0.0136 |
| TimesFM-2.5-200M | 15 | 15 | = | 7 | 8 | 0.5987 | 0.6081 | +0.0094 |
Separability by task, dataset and model
Computed by separability096.py on the 0.9.7.2 board, over the 15 ranked rows only. Spread SD: SD of the rows' scores. Pair noise: median bootstrap SD of the paired difference of two rows. Signal-to-noise: mean absolute gap between two rows over the pair noise. Resolved alone: pairs resolved on a board of that dataset alone. Tau with the task: Kendall tau between a dataset's order and the mean of the task's other datasets. Board effect: CAFE pairs resolved without the dataset minus with it (negative: the dataset helps).
By task.
| task | datasets | spread SD | range | pair noise | signal-to-noise | in 0.9.6 | pairs resolved | datasets resampled | tau with the other tasks | share of CAFE variance | CAFE pairs without it | same, resampled |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| C | 24 | 0.0184 | 0.0716 | 0.0018 | 10.06 | 8.98 | 80 | 25 | 0.181 | 0.156 | -2 | -1 |
| A | 13 | 0.0208 | 0.0716 | 0.0046 | 4.81 | 3.00 | 63 | 18 | 0.619 | 0.274 | +1 | -2 |
| FE | 15 | 0.0438 | 0.1229 | 0.0030 | 16.26 | 14.93 | 87 | 67 | 0.390 | 0.569 | -27 | -34 |
| CAFE | 52 | 0.0211 | 0.0702 | 0.0020 | 12.20 | 7.89 | 90 | 62 | – | – | – | – |
By dataset (● new in 0.9.7 or 0.9.7.2; ◐ regrown in 0.9.7.2: UKWIND; ○ pooled from 0.9.6 datasets whose scores were published), highest signal-to-noise first within each task.
All 52 datasets
| task | dataset | spread SD | range | pair noise | signal-to-noise | pairs resolved alone | tau with the task | task pairs without it | CAFE pairs without it, resampled |
|---|---|---|---|---|---|---|---|---|---|
| C | phys/lendb | 0.1152 | 0.3918 | 0.0046 | 24.45 | 97 | 0.429 | -7 | +1 |
| C | nicola15/bdg2_meter6 ● | 0.0279 | 0.0952 | 0.0037 | 8.53 | 89 | 0.219 | +0 | +1 |
| C | nicola15/robo6_rb6 ● | 0.0239 | 0.0741 | 0.0038 | 7.40 | 81 | 0.295 | +1 | +0 |
| C | mv06/stead | 0.0169 | 0.0642 | 0.0027 | 7.03 | 80 | 0.371 | -4 | +0 |
| C | mv06/hydraulic | 0.0959 | 0.3650 | 0.0125 | 6.43 | 62 | 0.314 | -5 | +2 |
| C | nicola15/ved_powertrain3 | 0.0191 | 0.0625 | 0.0033 | 6.16 | 73 | 0.524 | -3 | +1 |
| C | nicola15/haptic_texture8 | 0.0161 | 0.0677 | 0.0031 | 5.96 | 75 | 0.162 | +0 | +1 |
| C | ucr/ElectricDevices | 0.0126 | 0.0406 | 0.0031 | 4.74 | 63 | 0.486 | -1 | +0 |
| C | ucr/SonyAIBORobotSurface2 | 0.0592 | 0.2405 | 0.0148 | 4.20 | 47 | 0.019 | -3 | +0 |
| C | nicola15/openrainer_m | 0.0148 | 0.0472 | 0.0042 | 4.12 | 61 | 0.105 | +1 | +1 |
| C | ucr/FreezerRegularTrain | 0.0117 | 0.0456 | 0.0030 | 4.07 | 46 | 0.452 | +0 | -1 |
| C | mv06/voraus095 | 0.0344 | 0.1055 | 0.0095 | 3.97 | 54 | 0.200 | -2 | +0 |
| C | nicola15/chillan5 | 0.0080 | 0.0318 | 0.0025 | 3.60 | 54 | 0.600 | +0 | +0 |
| C | mv06/aursad095 | 0.0201 | 0.0624 | 0.0066 | 3.59 | 57 | 0.200 | -1 | +0 |
| C | nicola15/px4_airframe3 | 0.0211 | 0.0633 | 0.0068 | 3.50 | 60 | 0.295 | -5 | +0 |
| C | ucr/MoteStrain | 0.0281 | 0.1079 | 0.0088 | 3.41 | 38 | 0.410 | -2 | +1 |
| C | ucr/Wafer | 0.0108 | 0.0383 | 0.0033 | 3.33 | 33 | 0.421 | -1 | -1 |
| C | uea/AsphaltPavementTypeCoordinates | 0.0233 | 0.0897 | 0.0084 | 3.16 | 47 | 0.143 | +0 | -1 |
| C | ucr/PLAID | 0.0383 | 0.1572 | 0.0141 | 2.94 | 35 | 0.238 | -1 | -3 |
| C | nicola15/swiss_load10 | 0.0134 | 0.0473 | 0.0052 | 2.91 | 51 | 0.077 | -1 | +1 |
| C | ucr/FordA | 0.0207 | 0.0747 | 0.0082 | 2.89 | 31 | 0.524 | -5 | -2 |
| C | nicola15/poseit_ft | 0.0160 | 0.0573 | 0.0065 | 2.84 | 50 | 0.562 | -3 | +1 |
| C | mv06/gas251 | 0.0155 | 0.0548 | 0.0061 | 2.73 | 39 | 0.257 | +1 | -1 |
| C | ucr/ACSF1 | 0.0394 | 0.1222 | 0.0237 | 1.94 | 15 | 0.010 | +1 | -1 |
| A | KUKA ● | 0.0199 | 0.0640 | 0.0038 | 6.08 | 81 | 0.410 | -4 | +0 |
| A | UKWIND ◐ | 0.0440 | 0.1968 | 0.0098 | 3.69 | 34 | 0.067 | +2 | +1 |
| A | HAI | 0.0368 | 0.1207 | 0.0125 | 3.46 | 58 | 0.600 | -9 | -1 |
| A | UR5E ● | 0.0293 | 0.1196 | 0.0087 | 3.44 | 39 | 0.048 | +3 | +0 |
| A | ESA ○ | 0.0287 | 0.0744 | 0.0101 | 3.22 | 42 | 0.486 | -4 | +0 |
| A | RCFPOWER ● | 0.0295 | 0.1034 | 0.0119 | 2.87 | 39 | 0.486 | -3 | -1 |
| A | HOT | 0.0344 | 0.1507 | 0.0127 | 2.85 | 38 | 0.524 | -3 | +2 |
| A | UTAQ ● | 0.0250 | 0.0889 | 0.0097 | 2.40 | 26 | 0.676 | +0 | +1 |
| A | UAVSEAD ● | 0.0170 | 0.0589 | 0.0091 | 2.09 | 15 | 0.086 | -3 | +0 |
| A | PREDIST | 0.0323 | 0.1198 | 0.0176 | 2.04 | 19 | 0.524 | -3 | +1 |
| A | NOBOOM | 0.0401 | 0.1293 | 0.0263 | 1.76 | 25 | 0.562 | -5 | +0 |
| A | NASA ○ | 0.0328 | 0.1255 | 0.0245 | 1.48 | 11 | 0.162 | +5 | +1 |
| A | REASSEMBLE ● | 0.0289 | 0.1068 | 0.0236 | 1.35 | 10 | 0.124 | +8 | +2 |
| FE | megathrust_sync_v2 | 0.0646 | 0.1925 | 0.0059 | 12.37 | 79 | 0.486 | +1 | -2 |
| FE | rotary_utrecht | 0.0371 | 0.1058 | 0.0041 | 10.18 | 75 | 0.733 | -1 | -1 |
| FE | minati_circuits | 0.0577 | 0.1722 | 0.0079 | 8.37 | 79 | 0.657 | +0 | +0 |
| FE | memristor_jerk | 0.0646 | 0.2532 | 0.0078 | 8.30 | 72 | 0.733 | +0 | -1 |
| FE | asos_lows_b | 0.0611 | 0.1531 | 0.0089 | 7.77 | 66 | 0.733 | +1 | -3 |
| FE | stickslip_poincloux | 0.0415 | 0.1443 | 0.0071 | 6.88 | 81 | 0.638 | +0 | +1 |
| FE | ndbc_buoy_v2_b | 0.0480 | 0.1285 | 0.0098 | 5.72 | 71 | 0.810 | -1 | -2 |
| FE | geyser_strokkur | 0.0372 | 0.1079 | 0.0078 | 5.66 | 73 | 0.676 | +0 | -1 |
| FE | cdip_waves_c | 0.0600 | 0.1592 | 0.0132 | 5.35 | 74 | 0.848 | -2 | -1 |
| FE | noaa_coops_surge_b | 0.0648 | 0.1664 | 0.0155 | 4.83 | 56 | 0.829 | +0 | -3 |
| FE | heatpump_defrost ● | 0.0361 | 0.1018 | 0.0118 | 3.60 | 54 | 0.638 | +1 | +0 |
| FE | nasa_battery_rw | 0.0254 | 0.0866 | 0.0083 | 3.41 | 44 | 0.410 | +1 | -1 |
| FE | usgs_reach_v2_b | 0.0419 | 0.1052 | 0.0154 | 3.10 | 40 | 0.600 | +1 | -1 |
| FE | wind_genbearing_hot | 0.0276 | 0.0769 | 0.0105 | 3.08 | 35 | 0.676 | -1 | +0 |
| FE | towie_genbearing_hot | 0.0472 | 0.1269 | 0.0195 | 2.82 | 39 | 0.600 | +3 | -2 |
By model. Pairs resolved: pairs on the CAFE main board in which the model is resolved above or below the other. Datasets first: datasets where it has the highest score among the ranked rows.
| model | rank | tier | pairs resolved | tier, datasets resampled | datasets first | median rank over datasets |
|---|---|---|---|---|---|---|
| pj_better_10m ◊ | 1 | 1 | 13 of 14 | 1 | 4 | 4 |
| Mantis | 2 | 1 | 10 of 14 | 1 | 6 | 6 |
| pj_better_3p7m ◊ | 3 | 2 | 11 of 14 | 1 | 3 | 5 |
| pjgood-warp-xview-combo-10M ◊ | 4 | 2 | 10 of 14 | 1 | 5 | 5 |
| Chronos-2 | 5 | 2 | 11 of 14 | 1 | 5 | 7 |
| LeSaturn-warppool-factorized-7.4M ◊ | 6 | 3 | 13 of 14 | 1 | 1 | 8 |
| pj_better_1m ◊ | 7 | 4 | 13 of 14 | 2 | 2 | 8 |
| MantisV2 | 8 | 4 | 13 of 14 | 2 | 4 | 8 |
| NuTime | 9 | 5 | 14 of 14 | 2 | 5 | 9 |
| Timestral-209M | 10 | 6 | 13 of 14 | 3 | 2 | 9 |
| Timestral-123M | 11 | 6 | 11 of 14 | 3 | 3 | 10 |
| Timestral-5M | 12 | 7 | 11 of 14 | 3 | 0 | 11 |
| Timestral-28M | 13 | 7 | 11 of 14 | 3 | 3 | 10 |
| Toto-Open-Base-1.0 | 14 | 7 | 12 of 14 | 3 | 9 | 14 |
| TimesFM-2.5-200M | 15 | 8 | 14 of 14 | 4 | 0 | 14 |

Every dataset's effect on the board
Each row is the 0.9.7.2 board rebuilt without one dataset, every other rule unchanged (52 of 52 datasets). Tau: Kendall tau of its order with the main order. Main board: pj_better_10m ◊ first, 2 models in tier 1, 90 pairs resolved (15 within seed noise), 62 with the datasets resampled.
| task | dataset | first | its CAFE | tier 1 | tier 1 change | pairs resolved | datasets resampled | tau |
|---|---|---|---|---|---|---|---|---|
| C | ucr/MoteStrain | pj_better_10m ◊ | 0.7391 | 2 | same | 87 | 63 | 1.000 |
| C | ucr/SonyAIBORobotSurface2 | pj_better_10m ◊ | 0.7402 | 2 | same | 90 | 62 | 0.981 |
| C | ucr/Wafer | pj_better_10m ◊ | 0.7383 | 2 | same | 90 | 61 | 1.000 |
| C | ucr/ACSF1 | pj_better_10m ◊ | 0.7411 | 2 | same | 90 | 61 | 1.000 |
| C | ucr/PLAID | pj_better_10m ◊ | 0.7398 | 2 | same | 89 | 59 | 1.000 |
| C | ucr/FreezerRegularTrain | pj_better_10m ◊ | 0.7384 | 2 | same | 88 | 61 | 1.000 |
| C | ucr/FordA | pj_better_10m ◊ | 0.7394 | 2 | same | 90 | 60 | 1.000 |
| C | ucr/ElectricDevices | pj_better_10m ◊ | 0.7412 | 2 | same | 89 | 62 | 1.000 |
| C | phys/lendb | pj_better_10m ◊ | 0.7397 | 2 | same | 88 | 63 | 0.981 |
| C | mv06/hydraulic | pj_better_10m ◊ | 0.7388 | 2 | same | 85 | 64 | 0.981 |
| C | mv06/gas251 | pj_better_10m ◊ | 0.7399 | 2 | same | 89 | 61 | 1.000 |
| C | mv06/stead | pj_better_10m ◊ | 0.7389 | 2 | same | 91 | 62 | 1.000 |
| C | uea/AsphaltPavementTypeCoordinates | pj_better_10m ◊ | 0.7390 | 2 | same | 89 | 61 | 1.000 |
| C | mv06/aursad095 | pj_better_10m ◊ | 0.7426 | 2 | same | 90 | 62 | 1.000 |
| C | mv06/voraus095 | pj_better_10m ◊ | 0.7419 | 2 | same | 86 | 62 | 1.000 |
| C | nicola15/chillan5 | pj_better_10m ◊ | 0.7398 | 2 | same | 90 | 62 | 1.000 |
| C | nicola15/haptic_texture8 | pj_better_10m ◊ | 0.7443 | 2 | same | 88 | 63 | 1.000 |
| C | nicola15/openrainer_m | pj_better_10m ◊ | 0.7399 | 2 | same | 92 | 63 | 1.000 |
| C | nicola15/poseit_ft | pj_better_10m ◊ | 0.7437 | 2 | same | 90 | 63 | 1.000 |
| C | nicola15/px4_airframe3 | pj_better_10m ◊ | 0.7414 | 2 | same | 90 | 62 | 1.000 |
| C | nicola15/swiss_load10 | pj_better_10m ◊ | 0.7435 | 2 | same | 91 | 63 | 1.000 |
| C | nicola15/ved_powertrain3 | pj_better_10m ◊ | 0.7394 | 2 | same | 89 | 63 | 1.000 |
| C | nicola15/bdg2_meter6 ● | pj_better_10m ◊ | 0.7413 | 2 | same | 85 | 63 | 1.000 |
| C | nicola15/robo6_rb6 ● | pj_better_10m ◊ | 0.7414 | 2 | same | 86 | 62 | 1.000 |
| A | HAI | pj_better_10m ◊ | 0.7416 | 2 | same | 84 | 61 | 1.000 |
| A | UKWIND ◐ | pj_better_10m ◊ | 0.7369 | 2 | same | 82 | 63 | 1.000 |
| A | HOT | pj_better_10m ◊ | 0.7416 | 2 | same | 84 | 64 | 1.000 |
| A | PREDIST | pj_better_10m ◊ | 0.7396 | 2 | same | 84 | 63 | 1.000 |
| A | NOBOOM | pj_better_10m ◊ | 0.7366 | 2 | same | 89 | 62 | 1.000 |
| A | ESA ○ | pj_better_10m ◊ | 0.7398 | 2 | same | 89 | 62 | 0.981 |
| A | NASA ○ | Mantis | 0.7402 | 5 | +Chronos-2, +pj_better_3p7m ◊ and +pjgood-warp-xview-combo-10M ◊ | 89 | 63 | 0.981 |
| A | UAVSEAD ● | pj_better_10m ◊ | 0.7420 | 2 | same | 89 | 62 | 1.000 |
| A | UR5E ● | pj_better_10m ◊ | 0.7423 | 2 | same | 86 | 62 | 1.000 |
| A | KUKA ● | pj_better_10m ◊ | 0.7429 | 2 | same | 90 | 62 | 1.000 |
| A | UTAQ ● | pj_better_10m ◊ | 0.7410 | 2 | same | 87 | 63 | 1.000 |
| A | RCFPOWER ● | pj_better_10m ◊ | 0.7399 | 2 | same | 85 | 61 | 0.962 |
| A | REASSEMBLE ● | pj_better_10m ◊ | 0.7426 | 2 | same | 89 | 64 | 1.000 |
| FE | stickslip_poincloux | pj_better_10m ◊ | 0.7412 | 2 | same | 88 | 63 | 1.000 |
| FE | minati_circuits | pj_better_10m ◊ | 0.7389 | 2 | same | 89 | 62 | 1.000 |
| FE | geyser_strokkur | pj_better_10m ◊ | 0.7411 | 2 | same | 86 | 61 | 1.000 |
| FE | ndbc_buoy_v2_b | pj_better_10m ◊ | 0.7422 | 2 | same | 90 | 60 | 1.000 |
| FE | nasa_battery_rw | pj_better_10m ◊ | 0.7372 | 2 | same | 84 | 61 | 1.000 |
| FE | wind_genbearing_hot | pj_better_10m ◊ | 0.7426 | 2 | same | 86 | 62 | 1.000 |
| FE | towie_genbearing_hot | pj_better_10m ◊ | 0.7408 | 2 | same | 87 | 60 | 1.000 |
| FE | memristor_jerk | pj_better_10m ◊ | 0.7362 | 2 | same | 88 | 61 | 1.000 |
| FE | noaa_coops_surge_b | pj_better_10m ◊ | 0.7406 | 2 | same | 90 | 59 | 1.000 |
| FE | asos_lows_b | pj_better_10m ◊ | 0.7414 | 2 | same | 88 | 59 | 1.000 |
| FE | usgs_reach_v2_b | pj_better_10m ◊ | 0.7411 | 2 | same | 86 | 61 | 1.000 |
| FE | rotary_utrecht | pj_better_10m ◊ | 0.7422 | 2 | same | 87 | 61 | 1.000 |
| FE | megathrust_sync_v2 | pj_better_10m ◊ | 0.7403 | 2 | same | 87 | 60 | 1.000 |
| FE | cdip_waves_c | pj_better_10m ◊ | 0.7413 | 2 | same | 89 | 61 | 1.000 |
| FE | heatpump_defrost ● | pj_better_10m ◊ | 0.7410 | 2 | same | 84 | 62 | 0.981 |
Rank of every ranked model on the board without each dataset (main rank in the header)
| without | pj_better_10m ◊ (1) | Mantis (2) | pj_better_3p7m ◊ (3) | pjgood-warp-xview-combo-10M ◊ (4) | Chronos-2 (5) | LeSaturn-warppool-factorized-7.4M ◊ (6) | pj_better_1m ◊ (7) | MantisV2 (8) | NuTime (9) | Timestral-209M (10) | Timestral-123M (11) | Timestral-5M (12) | Timestral-28M (13) | Toto-Open-Base-1.0 (14) | TimesFM-2.5-200M (15) |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| C:MoteStrain | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:SonyAIBORobotSurface2 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 13 | 12 | 14 | 15 |
| C:Wafer | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:ACSF1 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:PLAID | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:FreezerRegularTrain | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:FordA | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:ElectricDevices | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:lendb | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 14 | 13 | 15 |
| C:hydraulic | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 14 | 13 | 15 |
| C:gas251 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:stead | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:AsphaltPavementTypeCoordinates | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:aursad095 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:voraus095 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:chillan5 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:haptic_texture8 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:openrainer_m | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:poseit_ft | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:px4_airframe3 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:swiss_load10 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:ved_powertrain3 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:bdg2_meter6 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| C:robo6_rb6 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:HAI | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:UKWIND | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:HOT | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:PREDIST | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:NOBOOM | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:ESA | 1 | 2 | 3 | 5 | 4 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:NASA | 2 | 1 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:UAVSEAD | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:UR5E | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:KUKA | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:UTAQ | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| A:RCFPOWER | 1 | 2 | 4 | 3 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 13 | 12 | 14 | 15 |
| A:REASSEMBLE | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:stickslip_poincloux | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:minati_circuits | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:geyser_strokkur | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:ndbc_buoy_v2_b | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:nasa_battery_rw | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:wind_genbearing_hot | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:towie_genbearing_hot | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:memristor_jerk | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:noaa_coops_surge_b | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:asos_lows_b | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:usgs_reach_v2_b | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:rotary_utrecht | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:megathrust_sync_v2 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:cdip_waves_c | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
| FE:heatpump_defrost | 1 | 2 | 3 | 5 | 4 | 6 | 7 | 8 | 9 | 10 | 11 | 12 | 13 | 14 | 15 |
Admission of 0.9.7.2
A. Every candidate was measured without a model before any cell on it (Amendment 13 item 8): Eval series, anomaly segments in them, median share of the scored part that is labelled, and the better of the rising and falling elapsed-time scores. Rules: (a) at least 15 Eval series, (b) at least 20 segments, (c) median share at most 0.3; new datasets also need an elapsed-time best of at most 0.65.
| candidate | status | cap | Eval series | segments | median share | elapsed-time best | rules | decided (UTC) | reason | |
|---|---|---|---|---|---|---|---|---|---|---|
| ESA | in | existing | 100 | 95 | 97 | 0.032 | 0.611 | a:yes b:yes c:yes gate:yes | – | items 2(a)-(c) hold: 95 Eval, 97 segments, median share 0.032; elapsed-time best 0.611 (gate applies to new datasets only) |
| HAI | in | existing | 100 | 58 | 103 | 0.030 | 0.533 | a:yes b:yes c:yes gate:yes | 2026-11-05T19:21Z | items 2(a)-(c) hold: 58 Eval, 103 segments, median share 0.030; elapsed-time best 0.533 (gate applies to new datasets only) |
| HOT | in | existing | 100 | 50 | 107 | 0.014 | 0.529 | a:yes b:yes c:yes gate:yes | – | items 2(a)-(c) hold: 50 Eval, 107 segments, median share 0.014; elapsed-time best 0.529 (gate applies to new datasets only) |
| KUKA | in | new | 300 | 255 | 534 | 0.108 | 0.519 | a:yes b:yes c:yes gate:yes | 2026-11-05T19:23Z | items 2(a)-(c) hold: 255 Eval, 534 segments, median share 0.108; elapsed-time best 0.519 (gate 0.65 holds) |
| NASA | in | existing | 100 | 37 | 47 | 0.040 | 0.516 | a:yes b:yes c:yes gate:yes | – | items 2(a)-(c) hold: 37 Eval, 47 segments, median share 0.040; elapsed-time best 0.516 (gate applies to new datasets only) |
| NOBOOM | in | existing | 300 | 20 | 37 | 0.191 | 0.561 | a:yes b:yes c:yes gate:yes | – | items 2(a)-(c) hold: 20 Eval, 37 segments, median share 0.191; elapsed-time best 0.561 (gate applies to new datasets only) |
| PREDIST | in | existing | 100 | 41 | 41 | 0.051 | 0.512 | a:yes b:yes c:yes gate:yes | – | items 2(a)-(c) hold: 41 Eval, 41 segments, median share 0.051; elapsed-time best 0.512 (gate applies to new datasets only) |
| RCFPOWER | in | new | 100 | 84 | 103 | 0.010 | 0.513 | a:yes b:yes c:yes gate:yes | PREREG09 note 2026-11-07 01:45Z (wave 2) | items 2(a)-(c) hold: 84 Eval, 103 segments, median share 0.010; elapsed-time best 0.513 (gate 0.65) |
| REASSEMBLE | in | new | 300 | 18 | 44 | 0.115 | 0.556 | a:yes b:yes c:yes gate:yes | PREREG09 note 2026-11-07 01:45Z (wave 2) | items 2(a)-(c) hold: 18 Eval, 44 segments, median share 0.115; elapsed-time best 0.556 (gate 0.65) |
| UAVSEAD | in | new | 300 | 101 | 147 | 0.083 | 0.585 | a:yes b:yes c:yes gate:yes | 2026-11-05T18:56Z | items 2(a)-(c) hold: 101 Eval, 147 segments, median share 0.083; elapsed-time best 0.585 (gate 0.65 holds) |
| UKWIND | in | existing | 100 | 85 | 128 | 0.027 | 0.541 | a:yes b:yes c:yes gate:yes | PREREG09 note 2026-11-07 01:45Z (wave 2) | items 2(a)-(c) hold: 85 Eval, 128 segments, median share 0.027; elapsed-time best 0.541 (gate applies to new datasets only) |
| UR5E | in | new | 300 | 63 | 74 | 0.191 | 0.616 | a:yes b:yes c:yes gate:yes | 2026-11-05T18:54Z | items 2(a)-(c) hold: 63 Eval, 74 segments, median share 0.191; elapsed-time best 0.616 (gate 0.65 holds) |
| UTAQ | in | new | 100 | 85 | 404 | 0.027 | 0.560 | a:yes b:yes c:yes gate:yes | PREREG09 note 2026-11-06 23:54Z (wave 1) | items 2(a)-(c) hold: 85 Eval, 404 segments, median share 0.027; elapsed-time best 0.560 (gate 0.65) |
| BASIC | out | new | 300 | – | – | – | – | a:– b:– c:– gate:– | 2026-11-05T19:12Z | check 1 / item 4 condition: the flights are software-in-the-loop, not real (Ahmad and Akram, Data in Brief 2024, doi:10.1016/j.dib.2024.110069: 'The BASiC dataset is exclusively derived from simulations conducted in a SITL environment using the ArduPilot platform'); not built |
| CAFUC2 | out | new | 300 | 96 | 286 | 0.021 | 0.508 | a:yes b:yes c:yes gate:yes | 2026-11-05T18:56Z | check 2 (physical label; PREREG09 note of 2026-10-31 ~20:50Z: injected or staged faults pass when the onset is observed in the system): CAFUC2's faults are synthetic signals written into five copies of each recorded flight after the flight; no aircraft experienced them, so the label is not a state of or an event in the physical system. Decided before any cell; only Jonas Petersen can reverse this, in a dated note |
| CRANFIELD | out | new | – | – | – | – | – | a:– b:– c:– gate:– | 2026-11-05T19:23Z | the official download (MATLAB File Exchange #50938) needs a MathWorks sign-in; the other copies (Kaggle, IEEE DataPort) need a login; item 4 / Amendment 13: sets that need a registration are not added |
| EAWAG | out | new | – | – | – | – | – | a:– b:– c:– gate:– | 2026-11-05T18:55Z | only 4 ponds (2D, 3D, 5A, 5B), phase 1, carry the expert 'Anomaly' column, with 5 segments in total: rules 2(a) and 2(b) cannot hold; the licence field is empty (portal: public domain for data outside Swiss copyright) |
| GREEKWIND | out | new | 100 | 7 | 8 | 0.012 | 0.501 | a:no b:no c:yes gate:yes | 2026-11-05T19:23Z | 2(a): 7 Eval series < 15; 2(b): 8 anomaly segments < 20 |
| LEAD1.0 | out | new | – | – | – | – | – | a:– b:– c:– gate:– | PREREG09 note 2026-11-07 00:10Z | check 4: its meters are the BDG2 electricity meters of the ASHRAE GEPIII subset, the campaign of the C unit nicola15/bdg2_meter6; no licence stated (data behind a Kaggle login) |
| MAST | out | new | – | – | – | – | – | a:– b:– c:– gate:– | 2026-11-05T18:55Z | no precursor-only cut without an elapsed-time leak: a scored block that ends before the current quench carries the precursor label at its end (a rising elapsed-time score reaches 0.933 on synthetic series of that shape); TokaMark ships no disruption labels or quench times |
| NOBOOM_M202210 | out | new | – | – | – | – | – | a:– b:– c:– gate:– | PREREG09 note 2026-11-07 01:45Z (wave 2) | check 3/4: 85 of its 89 runs are NOBOOM runs with the same X and a second label column (21 kept series byte-identical to NOBOOM series; pooled, 2 Eval pairs and 3 Eval-Tuning pairs share X); NOBOOM stays as in 0.9.7 |
| ONBOARDEU | out | new | 100 | 85 | 94 | 0.173 | 0.708 | a:yes b:yes c:yes gate:no | 2026-11-05T19:19Z | item 4 elapsed-time gate: 0.708 > 0.65 |
| PMU | out | new | 300 | – | – | – | – | a:– b:– c:– gate:– | 2026-11-05T19:22Z | the continuous 1 s TransnetBW record (Zenodo 15784548) is one channel (CE frequency) and ends 2024-04-25, covering 23 of 88 cases; P4 needs >= 2 channels and 23 cases give at most 19 Eval series and 19 segments (rule 2(b)); not built |
| PVLAZ | out | new | – | – | – | – | – | a:– b:– c:– gate:– | PREREG09 note 2026-11-07 01:45Z (wave 2) | rule 2(a): 5 Eval series < 15; item 4 elapsed-time gate 0.683 > 0.65 |
| RFLYMAD | out | new | 300 | 255 | 405 | 0.289 | 0.731 | a:yes b:yes c:yes gate:no | 2026-11-05T19:12Z | item 4 elapsed-time gate: 0.731 > 0.65 |
| TCABR | out | new | 300 | 138 | 138 | 0.199 | 1.000 | a:yes b:yes c:yes gate:no | 2026-11-05T19:22Z | item 4 elapsed-time gate: 1.000 > 0.65 |
| TSB-AD | out | new | – | – | – | – | – | a:– b:– c:– gate:– | PREREG09 note 2026-11-07 00:02Z | no source collection passes item 2 and checks 1-4 (simulated or injected events, IT/web/finance metrics, recordings of people, imputed or undocumented labels; work/r097/tsbad_screen0972.md); SMAP and MSL stay in NASA, SWaT needs an access form |
| USGS NWIS | out | new | – | – | – | – | – | a:– b:– c:– gate:– | PREREG09 note 2026-11-07 00:10Z | check 2: on ice-affected stretches the published discharge is an estimate written in place of the record, so the label marks an estimate or a gap, not a recorded event; no equipment-coded stretch found |
Admission waves, as written before any 0.9.7 or 0.9.7.2 cell on their units
| wave | written (UTC) | in | out | pending |
|---|---|---|---|---|
| 0 | 2026-11-05T18:46Z | HOT | none | none |
| 1 | 2026-11-05T18:56Z | ESA, NASA, UKWIND, HOT, PREDIST, NOBOOM, UAVSEAD and UR5E | EAWAG, CAFUC2 and MAST | HAI, RFLYMAD, PMU, ONBOARDEU, TCABR, BASIC, KUKA, GREEKWIND and CRANFIELD |
| C1 | 2026-11-05T19:10Z | nicola15/bdg2_meter6 and nicola15/robo6_rb6 | none | nicola15/sns_hvcm_b_end |
| 2 | 2026-11-05T19:12Z | none | RFLYMAD and BASIC | none |
| C2 | 2026-11-05T19:13Z | none | nicola15/sns_hvcm_b_end | none |
| 3 | 2026-11-05T19:21Z | HAI | ONBOARDEU | none |
| 4 | 2026-11-05T19:23Z | KUKA | TCABR, PMU, GREEKWIND and CRANFIELD | none |
| FE1 | 2026-11-05T19:44Z | heatpump_defrost | none | none |
| FE2 | 2026-11-05T21:59Z | ipshocks_fluxes | pyrnet | none |
| 0.9.7.2 wave 1 | 2026-11-06 23:54Z (commit dcf9de80a) | UTAQ | none | RCFPOWER, UKWIND, REASSEMBLE, PVLAZ and NOBOOM_M202210 |
| 0.9.7.2 screen | 2026-11-07 00:02Z and 00:10Z (commits a1f71c5f6, 4683f1fec) | none | TSB-AD (every source collection), LEAD1.0 and USGS NWIS | none |
| 0.9.7.2 wave 2 | 2026-11-07 01:45Z (commit bced91633) | RCFPOWER, UKWIND (regrown) and REASSEMBLE | PVLAZ and NOBOOM_M202210 | none |
FE. Model-free gates (Amendment 13 item 5; thresholds computed 2026-11-05T18:53:31Z on the 14 kept FE datasets, before any new FE download): at least 300 events, at least 30 independent units or days, time-since-last-event row at most 0.7956, time-of-day row at most 0.5851, best free forecast at most 0.85.
The reference rows on the kept FE datasets (the source of the thresholds)
| dataset | time since last event | time of day | position only | event rate | best free forecast |
|---|---|---|---|---|---|
| stickslip_poincloux | 0.685 | no calendar | 0.498 | 0.595 | early-warning statistics 0.701 |
| minati_circuits | 0.569 | no calendar | 0.507 | 0.501 | curvature 0.757 |
| geyser_strokkur | 0.734 | 0.504 | 0.490 | 0.611 | early-warning statistics 0.730 |
| ndbc_buoy_v2_b | 0.549 | 0.476 | 0.506 | 0.463 | current value 0.688 |
| nasa_battery_rw | 0.796 | 0.512 | 0.517 | 0.676 | current value 0.873 |
| wind_genbearing_hot | 0.651 | 0.529 | 0.534 | 0.594 | current value 0.704 |
| towie_genbearing_hot | 0.538 | 0.585 | 0.566 | 0.504 | level statistics 0.752 |
| memristor_jerk | 0.635 | no calendar | 0.510 | 0.505 | curvature 0.882 |
| noaa_coops_surge_b | 0.654 | 0.503 | 0.495 | 0.533 | current value 0.797 |
| asos_lows_b | 0.508 | 0.492 | 0.491 | 0.436 | trend 0.743 |
| usgs_reach_v2_b | 0.505 | 0.496 | 0.481 | 0.486 | early-warning statistics 0.652 |
| rotary_utrecht | 0.582 | no calendar | 0.503 | 0.520 | level statistics 0.647 |
| megathrust_sync_v2 | 0.759 | no calendar | 0.496 | 0.562 | level statistics 0.674 |
| cdip_waves_c | 0.566 | 0.520 | 0.515 | 0.494 | current value 0.738 |
| candidate | status | events | units or days | time since last event | time of day | best free forecast | reason |
|---|---|---|---|---|---|---|---|
| heatpump_defrost | in | 53,978 | 113 | 0.659 | 0.566 | 0.729 | item 5 gates hold: 53,978 events >= 300; 113 systems >= 30; time since last event 0.659 <= 0.796; time of day 0.566 <= 0.585; best free forecast 0.729 <= 0.85 |
| ngafid_hastall | out | – | – | – | – | – | Amendment 13 item 5 |
| substorm_omni | out | – | – | – | – | – | Amendment 13 item 5 |
| epa_aqs_pm25 | out | – | – | – | – | – | Amendment 13 item 5 |
| ipshocks_fluxes | admitted by item 5; off the board by check 3 (FE at least 1,000 events) | 914 | 629 | 0.490 | 0.513 | 0.695 | item 5 gates hold: 914 events; 629 distinct shock days (both spacecraft at L1, counted by day); time since last event 0.490; time of day 0.513; best free forecast 0.695 |
| pyrnet | out | – | – | – | – | – | not built and gated by the 21:30Z cutoff (the 4.8 GB download finished 21:58Z); builder written, never run |
ipshocks_fluxes passed the item 5 gates (at least 300 events) but has fewer than the 1,000 events of the standing admission check 3, which Amendment 13 item 7 keeps; the board leaves it out, so 0.9.7 has 15 FE datasets. Neither text said whether the 300-event gate replaces check 3 for new FE datasets; Jonas Petersen decided that ipshocks_fluxes stays out of 0.9.7, with the board that includes it known (PREREG09 note of 2026-11-06 11:05Z; see the sensitivities of the test above). Its cells exist and are kept.
C. New C datasets were rebuilt from their builders and accepted only if the sha256 of X equals the logged one (Amendment 13 item 6), after the exp-nicola-15 screening that scored a ◊ row on them (see What changed).
| dataset | status | kind | X sha256 equal | classes | windows | groups | licence | reason |
|---|---|---|---|---|---|---|---|---|
| nicola15/bdg2_meter6 | in | new (item 6) | yes | 6 | 75,409 | 1,615 | CC BY-SA 4.0 (github.com/buds-lab/building-data-genome-project-2 LICENSE) | rebuilt from the exp-nicola-15 builder; X sha256 equals LOG.md (item 6) |
| nicola15/robo6_rb6 | in | new (item 6) | yes | 6 | 6,869 | 5,352 | MIT (Hugging Face dataset card kyselica/RoBo6) | rebuilt from the exp-nicola-15 builder; X sha256 equals LOG.md (item 6) |
| nicola15/sns_hvcm_b_end | out | new (item 6) | yes | 2 | 3,323 | 15 | CC BY 4.0 (Mendeley Data kbbrw99vh8 v5) | item 6 gate: combo-10M minus random twin positive in 3 of 5 repeats (needs 4) and mean +0.0169 (needs +0.02); results/cgate097.json |
| mv06/3w | out | dropped (item 6) | – | – | – | – | – | Amendment 13 item 6 |
| mv06/bosch | out | dropped (item 6) | – | – | – | – | – | Amendment 13 item 6 |
| nicola15/soredd_abc | out | dropped (item 6) | – | – | – | – | – | Amendment 13 item 6 |
Combo minus twin on every C dataset (Amendment 13 item 6): pjgood-warp-xview-combo-10M minus the random-init LeSaturn row (3.7 M parameters, another architecture; not a matched twin of the 10.6 M combo), per repeat, under the C head; the criterion is positive in at least 4 of 5 repeats and a mean of at least +0.02. It decided only the new SNS HVCM unit; a kept dataset that fails it is reported here and not dropped.
| C dataset | positive repeats | of | mean difference | per repeat | criterion |
|---|---|---|---|---|---|
| nicola15/sns_hvcm_b_end (candidate) | 3 | 5 | +0.0169 | -0.019 +0.016 +0.047 -0.015 +0.055 | fails |
| ucr/MoteStrain | 1 | 1 | +0.0279 | +0.028 | n/a: one fixed split |
| ucr/SonyAIBORobotSurface2 | 1 | 1 | +0.2475 | +0.247 | n/a: one fixed split |
| ucr/Wafer | 1 | 1 | +0.0209 | +0.021 | n/a: one fixed split |
| ucr/ACSF1 | 0 | 1 | -0.0000 | -0.000 | n/a: one fixed split |
| ucr/PLAID | 1 | 1 | +0.1064 | +0.106 | n/a: one fixed split |
| ucr/FreezerRegularTrain | 1 | 1 | +0.1232 | +0.123 | n/a: one fixed split |
| ucr/FordA | 1 | 1 | +0.0229 | +0.023 | n/a: one fixed split |
| ucr/ElectricDevices | 1 | 1 | +0.0263 | +0.026 | n/a: one fixed split |
| phys/lendb | 5 | 5 | +0.1144 | +0.103 +0.131 +0.122 +0.102 +0.114 | passes |
| mv06/hydraulic | 5 | 5 | +0.0706 | +0.077 +0.074 +0.096 +0.039 +0.066 | passes |
| mv06/gas251 | 5 | 5 | +0.0979 | +0.107 +0.152 +0.099 +0.069 +0.062 | passes |
| mv06/stead | 5 | 5 | +0.0614 | +0.077 +0.072 +0.056 +0.053 +0.049 | passes |
| uea/AsphaltPavementTypeCoordinates | 1 | 1 | +0.0797 | +0.080 | n/a: one fixed split |
| mv06/aursad095 | 5 | 5 | +0.0850 | +0.078 +0.098 +0.093 +0.070 +0.086 | passes |
| mv06/voraus095 | 5 | 5 | +0.0839 | +0.069 +0.080 +0.110 +0.072 +0.089 | passes |
| nicola15/chillan5 | 5 | 5 | +0.0605 | +0.056 +0.051 +0.076 +0.051 +0.069 | passes |
| nicola15/haptic_texture8 | 5 | 5 | +0.0545 | +0.054 +0.044 +0.069 +0.048 +0.057 | passes |
| nicola15/openrainer_m | 5 | 5 | +0.0424 | +0.058 +0.031 +0.025 +0.039 +0.059 | passes |
| nicola15/poseit_ft | 5 | 5 | +0.0869 | +0.164 +0.081 +0.044 +0.051 +0.094 | passes |
| nicola15/px4_airframe3 | 5 | 5 | +0.0761 | +0.087 +0.067 +0.087 +0.050 +0.090 | passes |
| nicola15/swiss_load10 | 5 | 5 | +0.0476 | +0.069 +0.047 +0.045 +0.043 +0.034 | passes |
| nicola15/ved_powertrain3 | 5 | 5 | +0.0736 | +0.077 +0.072 +0.074 +0.055 +0.089 | passes |
| nicola15/bdg2_meter6 | 5 | 5 | +0.0329 | +0.050 +0.018 +0.040 +0.029 +0.027 | passes |
| nicola15/robo6_rb6 | 5 | 5 | +0.0850 | +0.079 +0.084 +0.085 +0.083 +0.094 | passes |
What took how long
From the run's event log (timing097.json, UTC): the first event is at 2026-11-05T18:33:41Z and the last at 2026-11-07T01:40:36Z, 31.12 hours apart. Builds and measurements ran in parallel, so the spans below overlap and do not add up to the run.
Phases: 4, 835.3 minutes in total, the longest phase2 (615.0 min).
| what | start | end | minutes | note |
|---|---|---|---|---|
| phase0 | 11-05 18:33:41 | 11-05 18:42 | 8.3 | setup, probes, dashboard, runner; ended when builders were launched (~18:42Z); logged late |
| phase1 | 11-05 18:42 | 11-05 21:59 | 197.0 | final FE list (PREREG09 note 21:59Z); logged after the outage |
| phase2 | 11-05 18:49 | 11-06 05:04 | 615.0 | last cell job 3868626 ended (unattended, VM offline); tabular references queued separately 2026-11-06 |
| phase3 | 11-06 09:17 | 11-06 09:32 | 15.0 |
Downloads: 28, 1979.7 minutes in total, the longest REASSEMBLE (1571.7 min).
| what | start | end | minutes | note |
|---|---|---|---|---|
| UAVSEAD | 11-05 18:38:58 | 11-05 18:40:31 | 1.6 | |
| UR5E | 11-05 18:39:00 | 11-05 18:46:24 | 7.4 | |
| BASIC | 11-05 18:39:08 | 11-05 18:40:03 | 0.9 | |
| TCABR | 11-05 18:39:33 | 11-05 18:55:30 | 15.9 | |
| HAI | 11-05 18:40:13 | 11-05 18:42:48 | 2.6 | |
| KUKA | 11-05 18:40:13 | 11-05 18:59:19 | 19.1 | |
| RFLYMAD | 11-05 18:40:25 | 11-05 18:57:42 | 17.3 | |
| EAWAG | 11-05 18:40:26 | 11-05 18:49:38 | 9.2 | |
| ONBOARDEU | 11-05 18:41:04 | 11-05 18:54:25 | 13.3 | |
| PMU | 11-05 18:41:14 | 11-05 18:45:05 | 3.9 | |
| CAFUC2 | 11-05 18:41:29 | 11-05 18:42:12 | 0.7 | |
| CRANFIELD | 11-05 18:41:48 | 11-05 18:46:10 | 4.4 | |
| GREEKWIND | 11-05 18:41:48 | 11-05 18:46:10 | 4.4 | |
| PREDIST | 11-05 18:42:31 | 11-05 18:44:26 | 1.9 | |
| C_robo6 | 11-05 18:42:32 | 11-05 19:04:32 | 22.0 | fetch_inside_build_robo6.py_end_is_card_mtime |
| C_bdg2 | 11-05 18:43:14 | 11-05 18:43:45 | 0.5 | |
| C_sns-hvcm | 11-05 18:43:14 | 11-05 18:44:56 | 1.7 | |
| NOBOOM | 11-05 18:44:47 | 11-05 18:46:28 | 1.7 | |
| MAST | 11-05 18:51:56 | 11-05 18:54:51 | 2.9 | out_no_build |
| fe_ipshocks | 11-05 18:54:51 | 11-05 19:45:34 | 50.7 | |
| fe_heatpump | 11-05 18:55:01 | 11-05 19:10:46 | 15.8 | |
| fe_pyrnet | 11-05 18:55:42 | 11-05 21:58:12 | 182.5 | |
| UTAQ (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:36:20 | 11-05 22:40:44 | 4.4 | |
| PVLAZ (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:36:42 | 11-05 22:37:37 | 0.9 | |
| UKWIND (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:36:55 | 11-05 22:54:36 | 17.7 | |
| RCFPOWER (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:38:11 | 11-05 22:40:39 | 2.5 | |
| NOBOOM_M202210 (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:42:18 | 11-05 22:44:27 | 2.1 | |
| REASSEMBLE (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:46:07 | 11-07 00:57:50 | 1571.7 | stopped_early_VM_overload |
Builds: 25, 1713.9 minutes in total, the longest UKWIND (1611.2 min).
| what | start | end | minutes | note |
|---|---|---|---|---|
| HOT_reselect | 11-05 18:40:18 | 11-05 18:40:42 | 0.4 | |
| C_robo6 | 11-05 18:42:32 | 11-05 19:04:32 | 22.0 | end_is_card_mtime |
| C_bdg2 | 11-05 18:43:45 | 11-05 18:45:09 | 1.4 | end_logged_late_actual_end_is_card_mtime |
| UAVSEAD | 11-05 18:43:47 | 11-05 18:53:11 | 9.4 | |
| HAI | 11-05 18:43:54 | 11-05 18:56:25 | 12.5 | |
| PREDIST | 11-05 18:44:31 | 11-05 18:48:37 | 4.1 | |
| C_sns-hvcm | 11-05 18:44:56 | 11-05 18:45:14 | 0.3 | end_logged_late_actual_end_is_card_mtime |
| CAFUC2 | 11-05 18:45:31 | 11-05 18:46:38 | 1.1 | |
| NOBOOM | 11-05 18:46:32 | 11-05 18:46:37 | 0.1 | |
| UR5E | 11-05 18:50:24 | 11-05 18:52:11 | 1.8 | |
| select_UR5E | 11-05 18:52:23 | 11-05 18:53:08 | 0.8 | |
| ONBOARDEU | 11-05 18:54:30 | 11-05 19:02:46 | 8.3 | |
| GREEKWIND | 11-05 18:59:23 | 11-05 18:59:40 | 0.3 | |
| KUKA | 11-05 18:59:40 | 11-05 19:09:07 | 9.4 | |
| RFLYMAD | 11-05 19:00:47 | 11-05 19:08:21 | 7.6 | |
| fe_heatpump | 11-05 19:10:46 | 11-05 19:12:32 | 1.8 | |
| TCABR | 11-05 19:11:50 | 11-05 19:20:09 | 8.3 | |
| fe_ipshocks | 11-05 19:45:34 | 11-05 19:47:15 | 1.7 | |
| PVLAZ (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:37:37 | 11-05 22:37:45 | 0.1 | |
| UKWIND (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:38:07 | 11-07 01:29:21 | 1611.2 | |
| RCFPOWER (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:40:39 | 11-05 22:40:47 | 0.1 | |
| UTAQ (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:40:53 | 11-05 22:46:48 | 5.9 | |
| NOBOOM_M202210 (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:44:27 | 11-05 22:44:35 | 0.1 | |
| NOBOOM_pooled | 11-06 23:54:39 | 11-06 23:54:44 | 0.1 | |
| REASSEMBLE (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-07 00:58:09 | 11-07 01:03:14 | 5.1 |
Model-free measurements: 24, 53.5 minutes in total, the longest ESA (10.8 min).
| what | start | end | minutes | note |
|---|---|---|---|---|
| ESA | 11-05 18:41:10 | 11-05 18:51:55 | 10.8 | ESA_NASA_UKWIND |
| fe_F3 | 11-05 18:45:57 | 11-05 18:54:32 | 8.6 | |
| CAFUC2 | 11-05 18:46:45 | 11-05 18:49:26 | 2.7 | |
| PREDIST | 11-05 18:50:34 | 11-05 18:51:01 | 0.5 | |
| NOBOOM | 11-05 18:51:01 | 11-05 18:51:19 | 0.3 | |
| UR5E | 11-05 18:53:20 | 11-05 18:53:51 | 0.5 | |
| UAVSEAD | 11-05 18:54:57 | 11-05 18:55:43 | 0.8 | |
| HAI | 11-05 18:57:41 | 11-05 18:58:19 | 0.6 | |
| GREEKWIND | 11-05 18:59:49 | 11-05 19:00:08 | 0.3 | |
| KUKA | 11-05 19:09:57 | 11-05 19:19:45 | 9.8 | |
| RFLYMAD | 11-05 19:10:03 | 11-05 19:10:59 | 0.9 | |
| fe_heatpump | 11-05 19:12:32 | 11-05 19:13:02 | 0.5 | |
| fe_heatpump_r2 | 11-05 19:13:15 | 11-05 19:20:05 | 6.8 | |
| ONBOARDEU | 11-05 19:16:24 | 11-05 19:17:07 | 0.7 | |
| HAI | 11-05 19:20:05 | 11-05 19:20:32 | 0.5 | |
| TCABR | 11-05 19:20:22 | 11-05 19:21:31 | 1.1 | |
| HAI_withEnd | 11-05 19:20:32 | 11-05 19:21:14 | 0.7 | |
| PVLAZ (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:37:50 | 11-05 22:37:56 | 0.1 | |
| RCFPOWER (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:40:54 | 11-05 22:41:28 | 0.6 | |
| NOBOOM_M202210 (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:45:09 | 11-05 22:45:51 | 0.7 | |
| UTAQ (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-05 22:46:52 | 11-05 22:49:37 | 2.8 | |
| NOBOOM_pooled | 11-06 23:55:39 | 11-06 23:56:12 | 0.6 | |
| REASSEMBLE (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-07 01:05:51 | 11-07 01:06:33 | 0.7 | |
| UKWIND (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) | 11-07 01:38:34 | 11-07 01:40:36 | 2.0 |
Started and not logged as ended when this card was built: crefs_C_new (since 11-05 19:11:13), build_UKWIND (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) (since 11-06 23:53:00), download_REASSEMBLE (0.9.7.1 work under Amendment 14, carried into 0.9.7.2 by Amendment 15) (since 11-06 23:57:25) and phase4 (since 11-06 10:13:14).
Cluster jobs of the run (37, from sacct; node-hours = elapsed x nodes):
| job | name | partition | state | start (UTC) | end (UTC) | task list | node-hours |
|---|---|---|---|---|---|---|---|
| 3867625 | s097 | debug | COMPLETED | 11-05 18:49Z | 11-05 18:53Z | jobs097_smoke.txt | 0.07 |
| 3867627 | p097 | preemptable | COMPLETED | 11-05 18:50Z | 11-05 18:55Z | jobs097_w0.txt | 0.08 |
| 3867656 | p097 | preemptable | PREEMPTED | 11-05 18:58Z | 11-05 19:17Z | jobs097_w1.txt | 0.31 |
| 3867709 | g097 | preemptable | COMPLETED | 11-05 19:08Z | 11-05 19:08Z | – | 0.01 |
| 3867710 | c097 | preemptable | CANCELLED | – | 11-05 19:08Z | – | 0.00 |
| 3867712 | c097 | preemptable | COMPLETED | 11-05 19:09Z | 11-05 19:10Z | – | 0.02 |
| 3867715 | g097 | preemptable | COMPLETED | 11-05 19:09Z | 11-05 19:10Z | – | 0.01 |
| 3867716 | c097 | preemptable | COMPLETED | 11-05 19:10Z | 11-05 19:11Z | – | 0.01 |
| 3867721 | e097 | preemptable | COMPLETED | 11-05 19:10Z | 11-05 19:11Z | – | 0.02 |
| 3867722 | c097 | preemptable | COMPLETED | 11-05 19:15Z | 11-05 19:16Z | – | 0.01 |
| 3867750 | gate097 | preemptable | COMPLETED | 11-05 19:15Z | 11-05 19:16Z | – | 0.02 |
| 3867751 | c097 | preemptable | COMPLETED | 11-05 19:17Z | 11-05 19:17Z | – | 0.01 |
| 3867791 | p097 | preemptable | COMPLETED | 11-05 19:21Z | 11-05 19:29Z | – | 0.12 |
| 3867812 | p097 | preemptable | PREEMPTED | 11-05 19:26Z | 11-05 19:34Z | – | 0.15 |
| 3867837 | p097 | preemptable | COMPLETED | 11-05 19:26Z | 11-05 19:41Z | – | 0.26 |
| 3867848 | c097 | preemptable | COMPLETED | 11-05 19:26Z | 11-05 19:26Z | – | 0.01 |
| 3867960 | p097 | preemptable | COMPLETED | 11-06 04:04Z | 11-06 04:04Z | – | 0.01 |
| 3867977 | f097 | preemptable | CANCELLED | – | 11-05 22:35Z | – | 0.00 |
| 3867978 | fe097 | preemptable | CANCELLED | – | 11-05 22:35Z | – | 0.00 |
| 3868446 | r097 | preemptable | CANCELLED | – | 11-05 22:35Z | – | 0.00 |
| 3868447 | fe097 | preemptable | CANCELLED | – | 11-05 22:35Z | – | 0.00 |
| 3868625 | a097 | preemptable | COMPLETED | 11-06 04:06Z | 11-06 05:01Z | – | 0.90 |
| 3868626 | a097 | preemptable | COMPLETED | 11-06 04:06Z | 11-06 05:04Z | – | 0.97 |
| 3868685 | a097 | preemptable | COMPLETED | 11-06 00:38Z | 11-06 01:16Z | – | 0.63 |
| 3871836 | t097tab | debug | COMPLETED | 11-06 09:36Z | 11-06 09:48Z | jobs097_tabsmoke.txt | 0.21 |
| 3872079 | t097tab | preemptable | CANCELLED | – | 11-06 10:00Z | – | 0.00 |
| 3872371 | t097tab | preemptable | PREEMPTED | 11-06 18:00Z | 11-06 18:01Z | jobs097_tab.txt | 0.02 |
| 3872372 | t097tab | preemptable | PREEMPTED | 11-06 18:00Z | 11-06 18:01Z | jobs097_tab.txt | 0.02 |
| 3880281 | t097tab | normal | CANCELLED | – | 11-07 03:01Z | – | 0.00 |
| 3880282 | t097tab | normal | CANCELLED | – | 11-07 03:01Z | – | 0.00 |
| 3880285 | t097tab | preemptable | COMPLETED | 11-06 23:49Z | 11-07 02:08Z | – | 2.32 |
| 3880314 | q097 | normal | CANCELLED | – | 11-06 23:58Z | – | 0.00 |
| 3880315 | q097 | preemptable | COMPLETED | 11-06 23:55Z | 11-06 23:58Z | – | 0.04 |
| 3880783 | q097 | preemptable | COMPLETED | 11-07 02:00Z | 11-07 02:47Z | – | 0.79 |
| 3880784 | q097 | normal | CANCELLED | – | 11-07 03:01Z | – | 0.00 |
| 3880786 | t097tab | preemptable | COMPLETED | 11-07 02:00Z | 11-07 03:01Z | – | 1.01 |
| 3880787 | t097tab | normal | CANCELLED | – | 11-07 03:01Z | – | 0.00 |
Other logged events
| time | event | note |
|---|---|---|
| 11-05 18:33:41 | run_start | session launched ~18:33Z |
| 11-05 18:38:13 | measure097_validated | measure097 reproduces nulls095 HOT 29/29 max diff 1.1e-16 |
| 11-05 18:45:00 | download_C_sns-hvcm | bytes_correction_previous_end_entry |
| 11-05 18:47:09 | build_UAVSEAD_restart | added_asset_field |
| 11-05 18:50:41 | gate_A_repro | A6g through CAFE-097 tree on Clariden: ZERO NOBOOM 20/20, pj_better_3p7m PREDIST 29/29 equal to 0.9.6 cells, max diff 0; smoke job 3867625 |
| 11-05 19:29:20 | phase1_A_C_done | final A list and C admission written by 19:23Z; FE pending |
| 11-06 10:13:14 | outage | VM froze 2026-11-05 ~22:56Z (memory), network lost 23:11Z, reset 2026-11-06 09:01Z; agents stopped 00:16Z-02:55Z (DECISIONS097.md) |
| 11-07 01:11:09 | build_UKWIND | restart_years_2016-2022_K2023_24_excluded_dup_exports |
Inference and benchmarking time
FE feature-extraction time on the new FE datasets is not measured for 28 model-dataset tasks: their tasks saved the features and then ended with an error in a scoring step the board does not use (DECISIONS097.md, 2026-11-06 09:35Z), so they have no clean timing record. Their FE head time is measured (the FT tasks).
Per model, from the task-queue records of the cell jobs (timing097_infer.json, timing097.py). task wall = end - start of one queue task (one row on one dataset: embedding + head + scoring, with up to NW tasks sharing one GH200, so it is an upper bound of the GPU time of that task); A throughput = Eval series per second and scored windows per second of task wall; GPU-hours = sum of task walls / 3600 (an upper bound: tasks share GPUs); node-hours = sacct elapsed x nodes. Seconds are the sum over the model's tasks of each kind. Time is reported, never scored.
| model | parameters | A cells, s | A gate, s | A reference, s | A7, s | B7, s | C embedding (Toto m1), s | C embedding (menu row), s | C embedding (stored row), s | FE cells, s | FE cells (head on stored features), s | FE embedding, s | FE gate, s | FE reference, s | A windows / s | A series / s | GPU-hours, upper bound |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Chronos-2 | 119.5 M | 2,600 | 81 | – | 2,726 | – | – | 63 | – | – | 34 | – | – | – | 85 | 0.218 | 1.529 |
| TimesFM-2.5-200M | 231.3 M | 1,793 | – | – | 3,076 | – | – | – | 20 | – | 39 | – | – | – | 123 | 0.317 | 1.369 |
| Timestral-209M | 209.3 M | 1,876 | – | – | 2,760 | – | – | 32 | – | – | 31 | – | – | – | 117 | 0.303 | 1.305 |
| Timestral-123M | 122.6 M | 1,436 | – | – | 1,646 | – | – | 32 | – | – | 28 | – | – | – | 153 | 0.396 | 0.873 |
| Toto-Open-Base-1.0 | 151.3 M | 1,545 | – | – | 1,425 | – | 28 | – | – | – | 35 | – | – | – | 142 | 0.368 | 0.842 |
| MantisV2 | – | 1,123 | – | – | 1,319 | – | – | 26 | – | – | 37 | – | – | – | 196 | 0.506 | 0.696 |
| rawknn | – | – | – | 1,188 | – | 1,091 | – | – | – | – | – | – | – | – | – | – | 0.633 |
| Mantis | 8.0 M | 889 | – | – | 806 | – | – | 23 | – | – | 38 | – | – | – | 247 | 0.639 | 0.488 |
| Timestral-28M | 27.8 M | 795 | – | – | 832 | – | – | 26 | – | – | 26 | – | – | – | 277 | 0.715 | 0.466 |
| pj_better_10m ◊ | 10.6 M | 571 | – | – | 1,006 | – | – | 19 | – | – | 26 | 3 | – | – | 385 | 0.995 | 0.451 |
| pjgood-warp-xview-combo-10M ◊ | 10.6 M | 595 | – | – | 837 | – | – | 33 | – | – | 26 | 3 | – | – | 370 | 0.954 | 0.415 |
| pj_better_3p7m ◊ | 3.8 M | 322 | 13 | – | 674 | – | – | 25 | – | – | 27 | 3 | 27 | – | 683 | 1.763 | 0.303 |
| LeSaturn-warppool-factorized-7.4M ◊ | 7.4 M | 376 | – | – | 536 | – | – | 22 | – | – | 30 | 3 | – | – | 585 | 1.510 | 0.268 |
| pj_better_1m ◊ | 1.0 M | 177 | – | – | 697 | – | – | 13 | – | – | 23 | 3 | – | – | 1,244 | 3.212 | 0.254 |
| Random-init LeSaturn (control) | 3.7 M | 274 | – | – | 568 | – | – | – | 19 | 6 | 28 | – | – | – | 803 | 2.073 | 0.249 |
| NuTime | 2.4 M | 341 | – | – | 348 | – | – | – | 17 | – | 29 | – | – | – | 645 | 1.667 | 0.204 |
| Timestral-5M | 5.2 M | 340 | – | – | 321 | – | – | 24 | – | – | 33 | – | – | – | 646 | 1.669 | 0.200 |
| ZERO | 0 | 181 | 12 | – | 126 | – | – | – | 9 | – | 32 | – | 35 | – | 1,215 | 3.138 | 0.110 |
| FEREF | – | – | – | – | – | – | – | – | – | – | – | – | – | 87 | – | – | 0.024 |
| levelonly | – | – | – | 46 | – | 38 | – | – | – | – | – | – | – | – | – | – | 0.023 |
| maxz | – | – | – | 21 | – | 12 | – | – | – | – | – | – | – | – | – | – | 0.009 |
| maxdz | – | – | – | 17 | – | 12 | – | – | – | – | – | – | – | – | – | – | 0.008 |
The cluster jobs of the run used 8.02 node-hours (32.09 GPU-hours at 4 GH200 per node), from sacct.
A material per dataset (the denominators of the A throughput)
| A dataset | Eval series | scored windows | rows |
|---|---|---|---|
| ESA | 95 | 37,929 | 1,187,429 |
| NASA | 37 | 14,049 | 234,147 |
| UKWIND | 85 | 33,650 | 905,922 |
| HOT | 50 | 19,818 | 524,844 |
| PREDIST | 41 | 15,980 | 220,652 |
| NOBOOM | 20 | 7,750 | 130,077 |
| HAI | 58 | 22,887 | 688,644 |
| UAVSEAD | 101 | 37,668 | 404,044 |
| UR5E | 63 | 23,617 | 327,889 |
| KUKA | 255 | 99,952 | 2,933,620 |
| UTAQ | 85 | 33,530 | 873,265 |
| RCFPOWER | 84 | 33,264 | 1,041,058 |
| REASSEMBLE | 18 | 6,529 | 66,477 |
Earlier cost table, for comparison (costs09.json, CAFE 0.9.1 datasets and settings, One A100 40 GB, 6 cores. 0.9.1: A measured on a shared GPU; part of the board estimated (see the text). The hardware and the datasets differ from 0.9.7, so compare orders of magnitude only):
| model | C, min | A, min | FE, min | total, min | FE measured |
|---|---|---|---|---|---|
| TimesFM-2.5-200M | 18.7 | 112.4 | 74.8 | 206 | yes |
| TiRex-2 | 4.5 | 116.2 | 63.5 | 184 | scaled |
| Chronos-2 | 6.1 | 99.4 | 66.1 | 172 | scaled |
| Timestral-209M | 9.7 | 42.6 | 69.2 | 121 | scaled |
| Timestral-123M | 7.1 | 43.1 | 59.8 | 110 | scaled |
| Toto-Open-Base-1.0 | 12.4 | 16.4 | 37.8 | 67 | yes |
| Timestral-28M | 2.7 | 12.6 | 45.9 | 61 | scaled |
| Mantis | 2.2 | 35.7 | 18.4 | 56 | scaled |
| LeSaturn-scm-10M-s43 | 6.4 | 12.0 | 25.2 | 44 | scaled |
| pjgood-warp-xview-combo-10M ◊ | 3.5 | 23.5 | 14.4 | 41 | scaled |
| LeSaturn-scm-3.8M-s43 | 3.1 | 9.6 | 28.0 | 41 | scaled |
| LeSaturn-scm-10M-s42 | 5.0 | 11.3 | 23.4 | 40 | scaled |
| LeSaturn-scm-3.8M-s44 | 2.8 | 9.5 | 26.7 | 39 | scaled |
| pj_better_10m ◊ | 3.2 | 20.6 | 13.3 | 37 | yes |
| LeSaturn-scm-10M-s44 | 5.3 | 8.7 | 22.9 | 37 | scaled |
| Timestral-5M | 4.9 | 4.9 | 20.8 | 31 | scaled |
| LeSaturn-scm-3.8M | 6.8 | 10.4 | 11.6 | 29 | scaled |
| LeSaturn-warppool-factorized-7.4M ◊ | 3.5 | 11.9 | 12.6 | 28 | scaled |
| pj_better_3p7m ◊ | 2.6 | 13.0 | 10.5 | 26 | scaled |
| NuTime | 0.0 | 12.9 | 11.1 | 24 | yes |
| Twin-LeSaturn-scm-3.8M | 3.4 | 4.6 | 14.9 | 23 | scaled |
| LeSaturn-warppool-factorized-3.8M | 3.3 | 5.4 | 12.1 | 21 | scaled |
| LeSaturn-warppool-factorized-3.8M-s43 | 3.2 | 5.2 | 11.7 | 20 | scaled |
| ZERO | 4.9 | 2.7 | 9.1 | 17 | yes |
Whole-board hours, runs one after another (C / A / FE): 0.8.6: 1.5 / 15.9 / 38.4 = 55.8; 0.8.6 protocol, same 24 runs: 2.63 / 25.91 / 54.25 = 82.79; 0.9: 2.09 / 3.52 / 4.15 = 9.76.
The 0.9.1 speed note (speed09.json)
Scoring one model on CAFE 0.9.1 (15 C, 10 A and 16 FE datasets) takes about 37 min for pj_better_10m and 17 min for ZERO on one A100, against 2.4 h and 2.0 h in 0.8.6. The slowest model, TimesFM-2.5-200M, takes about 3.4 h. The whole board, 24 runs (17 models, 5 extra pretraining seeds, 2 baselines) one after another, costs about 25 hours, against 83 h for the same runs under the 0.8.6 protocol (NuTime, not on the 0.8.6 board, is missing from that total, and its C time from the 0.9.1 total).
Where the time goes now. A and FE now cost about the same (10.7 h and 11.7 h for the board). On A the kNN head is cheap, but every window of every A series is embedded, and large encoders are slow at that (Chronos-2 1.7 h, TimesFM 1.9 h on A). The 9 FE datasets that 0.9.1 restores cost 520 s for pj_better_10m and 391 s for ZERO: on the fast path they are cheap, because their 0.8.6 cost was the head (10 seeds on the CPU), not the encoder.
The fast path changes no number. With one exception, every fresh cell equals the stored cell bit for bit: five models rerun from scratch on the 0.9.0 datasets, and pj_better_10m and ZERO on the 9 restored FE datasets (18 of 18 cells equal seeds 0–2 of their 0.8.6 cells). The new models' cells were each repeated on one dataset with identical results. The exception is one Mantis FE value, 8.9e-7 away from its 0.7-era cell, because of that run's forward pass.
How it was measured: one A100 40 GB with 6 physical cores. C and the 7 FE datasets of 0.9.0: 5 models timed one at a time on an otherwise idle machine, 19 estimated from their 0.8.6 times; the C times are for the 13 C datasets of that study, which lack hydraulic, 3w and FreezerRegularTrain of the 15 in 0.9.1 (and include FreezerSmallTrain). Restored FE: measured for pj_better_10m, ZERO, NuTime, Toto and TimesFM; the other rows scaled by the measured ratio. A: measured for every model except TiRex-2 (its cells were copied), on 12 A sources (the board uses 10) and on a GPU shared with other jobs, so the A times lean high. Basis per run in cafe09/results/costs09.json.
| model | 0.8.6 total | 0.9.1 C | 0.9.1 A | 0.9.1 FE (16 datasets) | 0.9.1 total |
|---|---|---|---|---|---|
| pj_better_3p7m | 1.1 h | 3 min | 13 min | 11 min | 26 min |
| ZERO | 2.0 h | 5 min | 3 min | 9 min | 17 min |
| pj_better_10m | 2.4 h | 3 min | 21 min | 13 min | 37 min |
| Mantis | 2.9 h | 2 min | 36 min | 18 min | 56 min |
| Chronos-2 | 4.6 h | 6 min | 99 min | 66 min | 172 min |
C and the 7 FE datasets of 0.9.0 measured for all five; the 9 restored FE datasets measured for pj_better_10m and ZERO, scaled for the other three; A measured on a shared GPU. 0.8.6 totals of Mantis and Chronos-2 are modelled (0.8.6 study).
Cost per model
Minutes of GPU time per model (sum of its task wall times, an upper bound because up to several tasks share one GH200), on this version's cells only; reused cells of earlier versions cost nothing here. So the basis differs by row: rows differ in which of their tasks ran and left a clean record in this run (pj_better_3p7m and Chronos-2 also ran gate tasks; FE feature tasks on the new FE datasets count only where they ended cleanly, see above), and the front below compares this run's cost, not the cost of scoring a model on the whole of CAFE (see the cost table of the earlier versions for that). Cost is reported, never scored. The whole board of ranked rows took 9.66 GPU-hours by this measure; the cluster jobs used 8.02 node-hours.
| model | seeds | CAFE | GPU minutes | on the front |
|---|---|---|---|---|
| Timestral-5M | 1 | 0.6996 | 12.0 | yes |
| NuTime | 1 | 0.7098 | 12.2 | yes |
| pj_better_1m ◊ | 1 | 0.7264 | 15.2 | yes |
| LeSaturn-warppool-factorized-7.4M ◊ | 1 | 0.7313 | 16.1 | yes |
| pj_better_3p7m ◊ | 1 | 0.7367 | 18.2 | yes |
| pjgood-warp-xview-combo-10M ◊ | 1 | 0.7363 | 24.9 | |
| pj_better_10m ◊ | 1 | 0.7405 | 27.1 | yes |
| Timestral-28M | 1 | 0.6987 | 28.0 | |
| Mantis | 1 | 0.7385 | 29.3 | |
| MantisV2 | 1 | 0.7230 | 41.8 | |
| Toto-Open-Base-1.0 | 1 | 0.6948 | 50.5 | |
| Timestral-123M | 1 | 0.7013 | 52.4 | |
| Timestral-209M | 1 | 0.7033 | 78.3 | |
| TimesFM-2.5-200M | 1 | 0.6703 | 82.1 | |
| Chronos-2 | 1 | 0.7351 | 91.7 |
On the front: no other ranked row has a higher CAFE score with the same or less GPU time.
Jobs and cells that did not finish
Logged as started and not as ended in the event log: 2 items (crefs_C_new and phase4). Rows with a missing cell on a task board (unranked on that task): 17. The list is in data/unfinished097.json.
Change log
One section per version since 0.9.4, generated from the boards' dataset lists and the amendments; earlier releases follow in CHANGELOG.md.
v0.9.7.2 (2026-11-07)
24 C, 13 A and 15 FE datasets; 15 ranked models; CAFE = mean of C, A, FE; tier 1: pj_better_10m ◊ and Mantis.
- A: 3 added (UTAQ, RCFPOWER, REASSEMBLE).
- Pairs resolved on the CAFE score: 90 on the main board (15 within seed noise), 62 of 105 with the datasets resampled.
- Amendment 15 (CAFE 0.9.7.2, written 2026-11-06 ~23:50Z (first headed 2026-11-07 ~00:10Z, a clock error; commit 199d87582 at 23:51:45Z), before any 0.9.7.2 build, measurement or cell on a dataset not yet measured, and before any model cell on a 0.9.7.1 or 0.9.7.2 candidate; the released 0.9.7 board, card and tags are not changed by it).
- Eval series of the added A datasets: UTAQ 85, RCFPOWER 84, REASSEMBLE 18.
- Tabular reference rows (unranked), cells missing on the C, A and FE boards: 36, 56, 30 in 0.9.7; 21, 26, 25 in 0.9.7.2.
- A: UKWIND regrown: 17 → 85 Eval series (see 0.9.7.2 beside 0.9.7).
- REASSEMBLE is built from a label-blind partial fetch (zip positions 0 to 78); a full fetch would roughly double its series.
- 23 tabular tasks ran over the 1-hour cap of Amendment 3 and stay missing.
- 0.9.7.2 is shown beside 0.9.7 (Amendment 15 item 4). The released 0.9.7 card is archived under versions/0.9.7/ and its Space page under v0.9.7/; tag v0.9.7 is unchanged.
- The test of Amendment 13 item 9 (applied unchanged by Amendment 15 item 4): not passed; the CAFE 1.0 candidate is 0.9.5.
v0.9.7 (2026-11-06)
24 C, 10 A and 15 FE datasets; 15 ranked models; CAFE = mean of C, A, FE; tier 1: pj_better_10m ◊.
- C: 2 added (nicola15/bdg2_meter6, nicola15/robo6_rb6).
- C: 3 removed or pooled (mv06/3w, mv06/bosch, nicola15/soredd_abc).
- A: 5 added (ESA, NASA, UAVSEAD, UR5E, KUKA).
- A: 9 removed or pooled (ESA_M1, ESA_M2, CARE_A, SMAP, MSL, CARE_C, RIGS, W3, SKAB).
- FE: 1 added (heatpump_defrost).
- FE: 3 removed or pooled (epa_aqs_pm25, substorm_omni, ngafid_hastall).
- Pairs resolved on the CAFE score: 85 on the main board (10 within seed noise), 61 of 105 with the datasets resampled.
- Amendment 13 (CAFE 0.9.7, written 2026-11-05 ~18:32Z (first headed ~18:40Z, a typo; commit adbffba1d at 18:32Z), before any 0.9.7 download, build, cell, or model read on a new unit; no 0.9.7 score exists). The heading's "before any 0.9.7 ... model read on a new unit" does not hold for the two C additions bdg2_meter6 and robo6_rb6: the exp-nicola-15 screening scored pjgood-warp-xview-combo-10M ◊ and its random-init twin on these exact builds at 09:01Z to 09:22Z on 2026-11-05, before the amendment was written (see New datasets and the conflict of interest on the card). Item 1 calls the 3W drop structural; it was made on combo minus twin (item 6 and the same screening), so six drops were score-informed.
- The test of Amendment 13 item 9: not passed; the CAFE 1.0 candidate was 0.9.5.
v0.9.6
25 C, 14 A and 17 FE datasets; 15 ranked models; CAFE = mean of C, A, FE; tier 1: pj_better_10m ◊, pj_better_3p7m ◊, Mantis, pjgood-warp-xview-combo-10M ◊ and Chronos-2.
- C: 8 added (nicola15/chillan5, nicola15/haptic_texture8, nicola15/openrainer_m, nicola15/poseit_ft, nicola15/px4_airframe3, nicola15/soredd_abc, nicola15/swiss_load10, nicola15/ved_powertrain3).
- A: 2 added (PREDIST, NOBOOM).
- FE: 1 added (ngafid_hastall).
- Pairs resolved on the CAFE score: 73 on the main board (1 within seed noise), 51 of 105 with the datasets resampled.
- Amendment 11 (CAFE 0.9.6, written 2026-11-04 ~21:45Z, before any 0.9.6 build of the A and FE datasets below, before any 0.9.6 cell, and before any model is run on the new A and FE data).
- Amendment 12 (CAFE 0.9.6, written 2026-11-04 ~22:00Z, before any 0.9.6 cell and before any new C head is fitted; replaces the C list of Amendment 11 item 2 and adds a C head rule).
v0.9.5
17 C, 12 A and 16 FE datasets; 15 ranked models; CAFE = mean of C, A, FE; tier 1: pj_better_10m ◊, pj_better_3p7m ◊, Mantis, pjgood-warp-xview-combo-10M ◊, Chronos-2 and LeSaturn-warppool-factorized-7.4M ◊.
- C: 2 added (mv06/aursad095, mv06/voraus095).
- C: 1 removed or pooled (mv06/voraus).
- A: 5 added (ESA_M1, CARE_A, MSL, W3, SKAB).
- Ranked rows no longer ranked: TiRex-2.
- Pairs resolved on the CAFE score: 73 on the main board (1 within seed noise), 49 of 105 with the datasets resampled.
- Amendment 6 (CAFE 0.9.5, written 2026-11-03 ~11:15Z, before any 0.9.5 cell, any 0.9.5 dataset build, or any model read on the new builds).
- Amendment 7 (CAFE 0.9.5, written 2026-11-03 ~13:54Z, before any 0.9.5 A cell; replaces item 2 of Amendment 6).
- Amendment 8 (CAFE 0.9.5, written 2026-11-03 ~14:32Z, before any 0.9.5 A cell; replaces item 2 of Amendment 7 and rule 4 of Amendment 5 as an admission rule).
- Amendment 9 (CAFE 0.9.5, written 2026-11-03 ~16:40Z, before any 0.9.5 readout cell; replaces the readout rules of Amendment 5 rule 7 and the C long-sample rule of Amendment 5 rule 2).
- Amendment 10 (CAFE 0.9.5, written 2026-11-03 ~17:09Z, before any 0.9.5 cell on voraus).
v0.9.4
16 C, 7 A and 16 FE datasets; 16 ranked models; CAFE = mean of C, A, FE; tier 1: MantisV2, Timestral-123M, Timestral-209M, Mantis, pjgood-warp-xview-combo-10M ◊, pj_better_10m ◊, pj_better_3p7m ◊, TiRex-2, pj_better_1m ◊, LeSaturn-warppool-factorized-7.4M ◊, Timestral-28M, Chronos-2 and Timestral-5M.
- Pairs resolved on the CAFE score: 39 on the main board (1 within seed noise), 16 of 120 with the datasets resampled.
- Amendment 5 (CAFE 0.9.4, written 2026-11-02, first committed 21:35Z as 3be8b9d4; its heading first said ~22:20Z, a typo; before any cell under these rules exists).
Provenance of the rules
Every amendment since 0.9.4 and every dated note since Amendment 13 (0.9.7 and 0.9.7.2), with the commit that first added it to PREREG09 (git log), the version it belongs to, the last released board known when it was written, what of 0.9.7 existed at that commit (first 0.9.7 cell: 2026-11-05 18:49Z; 0.9.7 board first committed: 2026-11-06 09:38Z; a provisional board, without the new FE datasets, was run from about 22:10Z on 2026-11-05 as a code check), and who requested it where the text says so. The headings in PREREG09 give the stated writing times.
| rule | version | board known | 0.9.7 at commit | first committed (UTC) | commit | requested by |
|---|---|---|---|---|---|---|
| Amendment 5 | 0.9.4 | 0.9.3.1 | – | 2026-11-02 21:35Z | 3be8b9d49 | Jonas Petersen |
| Amendment 6 | 0.9.5 | 0.9.4.1 | – | 2026-11-03 11:14Z | 799bbc68b | Jonas Petersen |
| Amendment 7 | 0.9.5 | 0.9.4.1 | – | 2026-11-03 13:54Z | ee6e213a0 | – |
| Amendment 8 | 0.9.5 | 0.9.4.1 | – | 2026-11-03 14:32Z | 4e04a33d8 | – |
| Amendment 9 | 0.9.5 | 0.9.4.1 | – | 2026-11-03 16:40Z | 06a56d1c1 | – |
| Amendment 10 | 0.9.5 | 0.9.4.1 | – | 2026-11-03 17:09Z | 4449cea4c | – |
| Amendment 11 | 0.9.6 | 0.9.5 | – | 2026-11-04 21:47Z | 6024a5a7d | Jonas Petersen |
| Amendment 12 | 0.9.6 | 0.9.5 | – | 2026-11-04 22:01Z | 20333d8f5 | Jonas Petersen |
| Amendment 13 | 0.9.7 | 0.9.6 | no 0.9.7 cell | 2026-11-05 18:32Z | adbffba1d | Jonas Petersen |
| Note 2026-11-05 18:46Z | 0.9.7 | 0.9.6 | no 0.9.7 cell | 2026-11-05 18:46Z | 2baf2b359 | – |
| Note 2026-11-05 18:57Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 18:57Z | 9c5d1019b | – |
| Note 2026-11-05 19:02Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:02Z | 24d87c8ff | – |
| Note 2026-11-05 19:05Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:05Z | 007d876a8 | – |
| Note 2026-11-05 19:10Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:10Z | 597b2c8e1 | – |
| Note 2026-11-05 19:12Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:12Z | 110f9d1aa | – |
| Note 2026-11-05 19:13Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:13Z | 5fc6706a9 | – |
| Note 2026-11-05 19:15Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:15Z | aba266e99 | – |
| Note 2026-11-05 19:21Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:21Z | 0fe475fab | – |
| Note 2026-11-05 19:23Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:23Z | b5a9676b8 | – |
| Note 2026-11-05 19:44Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 19:44Z | c9d83054c | – |
| Note 2026-11-05 21:59Z | 0.9.7 | 0.9.6 | 0.9.7 cells existed | 2026-11-05 21:59Z | cf7f5facb | – |
| Note 2026-11-05 22:32Z | 0.9.7 | 0.9.6 | 0.9.7 provisional board run (code check) | 2026-11-05 22:32Z | 4755a995b | – |
| Note 2026-11-06 10:02Z | 0.9.7 | 0.9.6 | 0.9.7 board built | 2026-11-06 10:03Z | 84f5cc9ab | – |
| Note 2026-11-06 10:10Z | 0.9.7 | 0.9.6 | 0.9.7 board built | 2026-11-06 10:22Z | ba8370e94 | – |
| Note 2026-11-06 11:05Z | 0.9.7 | 0.9.6 | 0.9.7 board built | 2026-11-06 11:05Z | eb73278bb | Jonas Petersen |
| Amendment 14 | 0.9.7.1 | 0.9.7 | 0.9.7 provisional board run (code check) | 2026-11-05 22:35Z | b70ca1a90 | Jonas Petersen |
| Amendment 15 | 0.9.7.2 | 0.9.7 | 0.9.7 board built | 2026-11-06 23:51Z | 199d87582 | Jonas Petersen |
| Note 2026-11-06 23:54Z | 0.9.7.2 | 0.9.7 | 0.9.7 board built | 2026-11-06 23:54Z | dcf9de80a | – |
| Note 2026-11-07 00:02Z | 0.9.7.2 | 0.9.7 | 0.9.7 board built | 2026-11-07 00:01Z | a1f71c5f6 | – |
| Note 2026-11-07 00:10Z | 0.9.7.2 | 0.9.7 | 0.9.7 board built | 2026-11-07 00:07Z | 4683f1fec | – |
| Note 2026-11-07 01:45Z | 0.9.7.2 | 0.9.7 | 0.9.7 board built | 2026-11-07 01:42Z | bced91633 | – |
The headings of 2026-11-07 00:02Z (first commit 00:01Z), 2026-11-07 00:10Z (first commit 00:07Z) and 2026-11-07 01:45Z (first commit 01:42Z) give a time a few minutes after their first commit (the clock error corrected in the other two 0.9.7.2 headings); the commit time is the one to rely on.
Baselines
Per dataset, the best baseline (rows with no learned encoder: ZERO, and current value on FE) against the best and the median ranked model. A free forecast beating the best model was part of the reason to drop epa_aqs_pm25 and substorm_omni, while kept FE datasets where a free forecast also wins stay in (see the FE table below); the 0.9.7 admission is not free of model scores: the SNS HVCM gate read model cells and six of the drops were informed by scores: C 3W, bosch and soredd_abc, FE ngafid_hastall, substorm_omni and epa_aqs_pm25 (Amendment 13 items 1 and 6; item 1 calls the 3W drop structural, but item 6 and the screening log drop it on combo minus twin; see the conflict-of-interest section).
All 52 datasets
| task | dataset | best baseline | its score | best model | its score | median model | models below the baseline | flag |
|---|---|---|---|---|---|---|---|---|
| C | ucr/MoteStrain | ZERO | 0.859 | NuTime | 0.949 | 0.927 | 1 of 15 | |
| C | ucr/SonyAIBORobotSurface2 | ZERO | 0.798 | LeSaturn-warppool-factorized-7.4M ◊ | 0.911 | 0.836 | 3 of 15 | |
| C | ucr/Wafer | ZERO | 0.761 | Timestral-28M | 0.998 | 0.990 | 0 of 15 | |
| C | ucr/ACSF1 | ZERO | 0.622 | Chronos-2 | 0.906 | 0.850 | 0 of 15 | |
| C | ucr/PLAID | ZERO | 0.598 | Mantis | 0.942 | 0.886 | 0 of 15 | |
| C | ucr/FreezerRegularTrain | ZERO | 0.960 | pj_better_3p7m ◊ | 0.994 | 0.980 | 1 of 15 | |
| C | ucr/FordA | ZERO | 0.489 | Timestral-209M | 0.948 | 0.919 | 0 of 15 | |
| C | ucr/ElectricDevices | ZERO | 0.628 | Timestral-123M | 0.805 | 0.788 | 0 of 15 | |
| C | phys/lendb | ZERO | 0.574 | Timestral-209M | 0.939 | 0.898 | 1 of 15 | |
| C | mv06/hydraulic | ZERO | 0.987 | Timestral-123M | 0.983 | 0.958 | 15 of 15 | baseline above every model |
| C | mv06/gas251 | ZERO | 0.866 | MantisV2 | 0.902 | 0.882 | 2 of 15 | |
| C | mv06/stead | ZERO | 0.599 | Timestral-123M | 0.977 | 0.957 | 0 of 15 | |
| C | uea/AsphaltPavementTypeCoordinates | ZERO | 0.586 | pjgood-warp-xview-combo-10M ◊ | 0.954 | 0.919 | 0 of 15 | |
| C | mv06/aursad095 | ZERO | 0.653 | Timestral-28M | 0.726 | 0.692 | 0 of 15 | |
| C | mv06/voraus095 | ZERO | 0.639 | Chronos-2 | 0.757 | 0.731 | 0 of 15 | |
| C | nicola15/chillan5 | ZERO | 0.565 | Chronos-2 | 0.894 | 0.885 | 0 of 15 | |
| C | nicola15/haptic_texture8 | ZERO | 0.524 | MantisV2 | 0.606 | 0.571 | 0 of 15 | |
| C | nicola15/openrainer_m | ZERO | 0.805 | Chronos-2 | 0.890 | 0.874 | 0 of 15 | |
| C | nicola15/poseit_ft | ZERO | 0.595 | pjgood-warp-xview-combo-10M ◊ | 0.634 | 0.614 | 3 of 15 | |
| C | nicola15/px4_airframe3 | ZERO | 0.607 | Timestral-28M | 0.827 | 0.776 | 0 of 15 | |
| C | nicola15/swiss_load10 | ZERO | 0.614 | pj_better_1m ◊ | 0.647 | 0.631 | 3 of 15 | |
| C | nicola15/ved_powertrain3 | ZERO | 0.823 | pjgood-warp-xview-combo-10M ◊ | 0.921 | 0.905 | 0 of 15 | |
| C | nicola15/bdg2_meter6 | ZERO | 0.580 | NuTime | 0.792 | 0.764 | 0 of 15 | |
| C | nicola15/robo6_rb6 | ZERO | 0.594 | pjgood-warp-xview-combo-10M ◊ | 0.776 | 0.741 | 0 of 15 | |
| A | HAI | ZERO | 0.660 | Mantis | 0.664 | 0.599 | 14 of 15 | baseline at or above the median model |
| A | UKWIND | ZERO | 0.792 | NuTime | 0.829 | 0.787 | 10 of 15 | baseline at or above the median model |
| A | HOT | ZERO | 0.645 | NuTime | 0.690 | 0.617 | 13 of 15 | baseline at or above the median model |
| A | PREDIST | ZERO | 0.701 | NuTime | 0.693 | 0.650 | 15 of 15 | baseline above every model |
| A | NOBOOM | ZERO | 0.789 | pj_better_1m ◊ | 0.813 | 0.771 | 10 of 15 | baseline at or above the median model |
| A | ESA | ZERO | 0.654 | pjgood-warp-xview-combo-10M ◊ | 0.685 | 0.624 | 10 of 15 | baseline at or above the median model |
| A | NASA | ZERO | 0.585 | MantisV2 | 0.671 | 0.638 | 1 of 15 | |
| A | UAVSEAD | ZERO | 0.616 | Toto-Open-Base-1.0 | 0.629 | 0.592 | 14 of 15 | baseline at or above the median model |
| A | UR5E | ZERO | 0.491 | Chronos-2 | 0.612 | 0.587 | 0 of 15 | |
| A | KUKA | ZERO | 0.571 | pj_better_10m ◊ | 0.571 | 0.536 | 14 of 15 | baseline at or above the median model |
| A | UTAQ | ZERO | 0.618 | Mantis | 0.644 | 0.628 | 2 of 15 | |
| A | RCFPOWER | ZERO | 0.682 | MantisV2 | 0.698 | 0.657 | 12 of 15 | baseline at or above the median model |
| A | REASSEMBLE | ZERO | 0.536 | Mantis | 0.635 | 0.610 | 1 of 15 | |
| FE | stickslip_poincloux | ZERO | 0.617 | Toto-Open-Base-1.0 | 0.765 | 0.682 | 0 of 15 | |
| FE | minati_circuits | current value | 0.647 | Toto-Open-Base-1.0 | 0.821 | 0.775 | 0 of 15 | |
| FE | geyser_strokkur | current value | 0.623 | Mantis | 0.740 | 0.687 | 0 of 15 | |
| FE | ndbc_buoy_v2_b | current value | 0.689 | Toto-Open-Base-1.0 | 0.683 | 0.632 | 15 of 15 | baseline above every model |
| FE | nasa_battery_rw | current value | 0.872 | Mantis | 0.879 | 0.860 | 14 of 15 | baseline at or above the median model |
| FE | wind_genbearing_hot | current value | 0.703 | Toto-Open-Base-1.0 | 0.652 | 0.623 | 15 of 15 | baseline above every model |
| FE | towie_genbearing_hot | current value | 0.739 | pj_better_3p7m ◊ | 0.716 | 0.674 | 15 of 15 | baseline above every model |
| FE | memristor_jerk | ZERO | 0.844 | Toto-Open-Base-1.0 | 0.933 | 0.900 | 3 of 15 | |
| FE | noaa_coops_surge_b | current value | 0.795 | Toto-Open-Base-1.0 | 0.737 | 0.690 | 15 of 15 | baseline above every model |
| FE | asos_lows_b | current value | 0.730 | Toto-Open-Base-1.0 | 0.727 | 0.686 | 15 of 15 | baseline above every model |
| FE | usgs_reach_v2_b | ZERO | 0.580 | pj_better_3p7m ◊ | 0.708 | 0.686 | 0 of 15 | |
| FE | rotary_utrecht | ZERO | 0.612 | pj_better_10m ◊ | 0.660 | 0.637 | 6 of 15 | |
| FE | megathrust_sync_v2 | ZERO | 0.542 | pj_better_10m ◊ | 0.740 | 0.712 | 0 of 15 | |
| FE | cdip_waves_c | current value | 0.738 | Toto-Open-Base-1.0 | 0.701 | 0.635 | 15 of 15 | baseline above every model |
| FE | heatpump_defrost | current value | 0.701 | pj_better_10m ◊ | 0.708 | 0.664 | 13 of 15 | baseline at or above the median model |
On FE, the best forecast with no encoder (current value, trend, curvature, early-warning statistics, spectral shift, level statistics) per dataset against the best ranked model. On 7 of 15 FE datasets a no-encoder forecast scores above every ranked model (ndbc_buoy_v2_b, wind_genbearing_hot, towie_genbearing_hot, noaa_coops_surge_b, asos_lows_b, cdip_waves_c and heatpump_defrost). For the new FE datasets the last column is pjgood-warp-xview-combo-10M ◊ minus the random-init LeSaturn row (3.7 M; not a matched twin), the second number Amendment 13 item 5 asks the card to show.
All 15 FE datasets
| FE dataset | best no-encoder forecast | its score | best ranked model | its score | ranked rows below it | flag | combo-10M minus random-init LeSaturn (new datasets) |
|---|---|---|---|---|---|---|---|
| stickslip_poincloux | early-warning statistics | 0.702 | Toto-Open-Base-1.0 | 0.765 | 10 of 15 | ||
| minati_circuits | curvature | 0.761 | Toto-Open-Base-1.0 | 0.821 | 6 of 15 | ||
| geyser_strokkur | early-warning statistics | 0.731 | Mantis | 0.740 | 12 of 15 | ||
| ndbc_buoy_v2_b | current value | 0.689 | Toto-Open-Base-1.0 | 0.683 | 15 of 15 | free forecast above every ranked model | |
| nasa_battery_rw | current value | 0.872 | Mantis | 0.879 | 14 of 15 | ||
| wind_genbearing_hot | current value | 0.703 | Toto-Open-Base-1.0 | 0.652 | 15 of 15 | free forecast above every ranked model | |
| towie_genbearing_hot | level statistics | 0.754 | pj_better_3p7m ◊ | 0.716 | 15 of 15 | free forecast above every ranked model | |
| memristor_jerk | curvature | 0.883 | Toto-Open-Base-1.0 | 0.933 | 6 of 15 | ||
| noaa_coops_surge_b | current value | 0.795 | Toto-Open-Base-1.0 | 0.737 | 15 of 15 | free forecast above every ranked model | |
| asos_lows_b | trend | 0.744 | Toto-Open-Base-1.0 | 0.727 | 15 of 15 | free forecast above every ranked model | |
| usgs_reach_v2_b | early-warning statistics | 0.653 | pj_better_3p7m ◊ | 0.708 | 6 of 15 | ||
| rotary_utrecht | level statistics | 0.647 | pj_better_10m ◊ | 0.660 | 9 of 15 | ||
| megathrust_sync_v2 | level statistics | 0.674 | pj_better_10m ◊ | 0.740 | 6 of 15 | ||
| cdip_waves_c | current value | 0.738 | Toto-Open-Base-1.0 | 0.701 | 15 of 15 | free forecast above every ranked model | |
| heatpump_defrost ● | curvature | 0.729 | pj_better_10m ◊ | 0.708 | 15 of 15 | free forecast above every ranked model | +0.027 |
Per task, the three strongest unranked rows (controls, no-encoder references and the specialist row) and how many ranked rows score below them on the task score; a row with no ranked row below it is not listed. The per-dataset baseline above is ZERO or current value only; on FE several no-encoder forecasts score higher than current value.
| task | row | kind | task score | ranked rows below it |
|---|---|---|---|---|
| C | MultiROCKET-Hydra | specialist | 0.864 | 15 of 15 |
| A | ZERO | control | 0.642 | 8 of 15 |
| A | Random-init LeSaturn (control) | control | 0.611 | 2 of 15 |
| A | max-|z| | anchor | 0.592 | 1 of 15 |
| FE | level statistics | admission | 0.719 | 9 of 15 |
| FE | curvature | admission | 0.707 | 7 of 15 |
| FE | Random-init LeSaturn (control) | control | 0.703 | 7 of 15 |
On A, the best of the three data-free rows (no data read: a score that rises or falls with elapsed time, and a random score per window) against the ranked models. The elapsed-time gate of Amendment 13 item 4 (at most 0.65) admits a dataset; it does not promise that every model beats these rows.
| A dataset | best data-free row | its score | best model | its score | median model | models below it | flag |
|---|---|---|---|---|---|---|---|
| HAI | null: elapsed time rising | 0.533 | Mantis | 0.664 | 0.599 | 0 of 15 | |
| UKWIND | null: elapsed time rising | 0.541 | NuTime | 0.829 | 0.787 | 0 of 15 | |
| HOT | null: elapsed time rising | 0.529 | NuTime | 0.690 | 0.617 | 0 of 15 | |
| PREDIST | null: elapsed time rising | 0.512 | NuTime | 0.693 | 0.650 | 0 of 15 | |
| NOBOOM | null: elapsed time rising | 0.561 | pj_better_1m ◊ | 0.813 | 0.771 | 0 of 15 | |
| ESA | null: elapsed time rising | 0.611 | pjgood-warp-xview-combo-10M ◊ | 0.685 | 0.624 | 1 of 15 | |
| NASA | null: elapsed time rising | 0.516 | MantisV2 | 0.671 | 0.638 | 0 of 15 | |
| UAVSEAD | null: elapsed time rising | 0.585 | Toto-Open-Base-1.0 | 0.629 | 0.592 | 6 of 15 | |
| UR5E | null: elapsed time rising | 0.616 | Chronos-2 | 0.612 | 0.587 | 15 of 15 | data-free row above every ranked model |
| KUKA | null: elapsed time falling | 0.519 | pj_better_10m ◊ | 0.571 | 0.536 | 2 of 15 | |
| UTAQ | null: elapsed time rising | 0.560 | Mantis | 0.644 | 0.628 | 1 of 15 | |
| RCFPOWER | null: elapsed time falling | 0.513 | MantisV2 | 0.698 | 0.657 | 0 of 15 | |
| REASSEMBLE | null: elapsed time rising | 0.556 | Mantis | 0.635 | 0.610 | 1 of 15 |
Flagged: UR5E (null: elapsed time rising 0.616 against the best model Chronos-2 0.612). On such a dataset the ranking orders models that do no better than knowing the position in the series.
Per model, the datasets where it scores more than 0.01 (the practical-equality margin) below the best baseline:
| model | datasets | which |
|---|---|---|
| pj_better_10m ◊ | 11 | C:hydraulic, A:HAI, A:HOT, A:PREDIST, A:UAVSEAD, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:cdip_waves_c |
| Mantis | 10 | C:hydraulic, A:PREDIST, A:ESA, A:UAVSEAD, A:KUKA, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:cdip_waves_c |
| pj_better_3p7m ◊ | 11 | C:hydraulic, A:HAI, A:HOT, A:PREDIST, A:UAVSEAD, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:cdip_waves_c |
| pjgood-warp-xview-combo-10M ◊ | 12 | C:hydraulic, A:HAI, A:HOT, A:PREDIST, A:UAVSEAD, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:cdip_waves_c |
| Chronos-2 | 16 | C:hydraulic, A:HAI, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:cdip_waves_c, FE:heatpump_defrost |
| LeSaturn-warppool-factorized-7.4M ◊ | 16 | C:hydraulic, A:HAI, A:UKWIND, A:HOT, A:PREDIST, A:UAVSEAD, A:KUKA, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:cdip_waves_c, FE:heatpump_defrost |
| pj_better_1m ◊ | 14 | C:SonyAIBORobotSurface2, C:hydraulic, A:HAI, A:UKWIND, A:HOT, A:PREDIST, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:cdip_waves_c, FE:heatpump_defrost |
| MantisV2 | 15 | C:hydraulic, A:HAI, A:UKWIND, A:PREDIST, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:cdip_waves_c, FE:heatpump_defrost |
| NuTime | 15 | C:hydraulic, A:HAI, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:rotary_utrecht, FE:cdip_waves_c, FE:heatpump_defrost |
| Timestral-209M | 18 | C:hydraulic, A:HAI, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:rotary_utrecht, FE:cdip_waves_c, FE:heatpump_defrost |
| Timestral-123M | 17 | A:HAI, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:rotary_utrecht, FE:cdip_waves_c, FE:heatpump_defrost |
| Timestral-5M | 17 | A:HAI, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:memristor_jerk, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:rotary_utrecht, FE:cdip_waves_c, FE:heatpump_defrost |
| Timestral-28M | 19 | C:hydraulic, A:HAI, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:UAVSEAD, A:KUKA, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:memristor_jerk, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:rotary_utrecht, FE:cdip_waves_c, FE:heatpump_defrost |
| Toto-Open-Base-1.0 | 21 | C:SonyAIBORobotSurface2, C:FreezerRegularTrain, C:lendb, C:hydraulic, C:gas251, C:poseit_ft, A:HAI, A:UKWIND, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:KUKA, A:UTAQ, A:RCFPOWER, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:noaa_coops_surge_b, FE:cdip_waves_c, FE:heatpump_defrost |
| TimesFM-2.5-200M | 25 | C:MoteStrain, C:hydraulic, C:gas251, C:swiss_load10, A:HAI, A:UKWIND, A:HOT, A:PREDIST, A:NOBOOM, A:ESA, A:NASA, A:UAVSEAD, A:KUKA, A:UTAQ, A:RCFPOWER, FE:ndbc_buoy_v2_b, FE:nasa_battery_rw, FE:wind_genbearing_hot, FE:towie_genbearing_hot, FE:memristor_jerk, FE:noaa_coops_surge_b, FE:asos_lows_b, FE:rotary_utrecht, FE:cdip_waves_c, FE:heatpump_defrost |

Noise budget
Signal against test-material noise, over the ranked rows: the SD of their scores (signal) and the bootstrap SD of the paired difference of two rows (test material, median over pairs). A single-seed pair closer than 0.009 is marked within seed noise; that margin comes from the 0.9.2 noise budget, which also counted pretraining seed, head training set and readout choice and was not rerun.
| board | signal SD | test material, SD of a pair | spread over pair noise (not the test's signal-to-noise) |
|---|---|---|---|
| C | 0.0184 | 0.0018 | 10.15 |
| A | 0.0208 | 0.0046 | 4.50 |
| FE | 0.0438 | 0.0030 | 14.39 |
| CAFE | 0.0211 | 0.0020 | 10.68 |
The datasets themselves are a further source: with them resampled, 62 of 105 pairs stay resolved, against 90 on the main board (15 of them within seed noise).
Elo
Elo from paired per-dataset wins of the ranked rows (ZERO = 1000; 2,000 draws; elo095.py's method). It is a figure (inner intervals that do not overlap are not a resolved pair) and gives no verdict: the CAFE score, its Holm verdicts and tiers are the board. Inner interval: test material resampled; outer: datasets resampled too. Guests are rated against the frozen ratings of the ranked rows; a guest without a cell on a dataset takes ZERO's value there, and the share is in the last column. Third-party pool: the Elo of a fit without the ◊ rows in the pool.
‡: some of the row's dataset cells are missing and were filled with ZERO's value for the Elo matches (column imputed). The tabular rows are among them where their cells are missing (see 0.9.7.2 beside 0.9.7).
| row | kind | Elo | test material | and datasets | Elo C | Elo A | Elo FE | third-party pool | imputed |
|---|---|---|---|---|---|---|---|---|---|
| pj_better_10m ◊ | ranked, one readout | 1280 | 1263 to 1297 | 1238 to 1329 | 1506 | 1071 | 1483 | 1269 | |
| pjgood-warp-xview-combo-10M ◊ | ranked, one readout | 1250 | 1234 to 1268 | 1209 to 1293 | 1544 | 1073 | 1315 | 1254 | |
| pj_better_3p7m ◊ | ranked, one readout | 1249 | 1233 to 1266 | 1202 to 1298 | 1478 | 1067 | 1408 | 1245 | |
| Mantis | ranked, one readout | 1249 | 1231 to 1267 | 1201 to 1301 | 1416 | 1069 | 1498 | 1246 | |
| Chronos-2 | ranked, one readout | 1218 | 1201 to 1236 | 1177 to 1262 | 1540 | 942 | 1374 | 1223 | |
| LeSaturn-warppool-factorized-7.4M ◊ | ranked, one readout | 1177 | 1161 to 1193 | 1133 to 1222 | 1395 | 940 | 1418 | 1181 | |
| MantisV2 | ranked, one readout | 1168 | 1149 to 1187 | 1111 to 1227 | 1455 | 1004 | 1207 | 1172 | |
| pj_better_1m ◊ | ranked, one readout | 1167 | 1153 to 1183 | 1124 to 1218 | 1377 | 1010 | 1304 | 1179 | |
| NuTime | ranked, one readout | 1094 | 1076 to 1112 | 1036 to 1153 | 1396 | 987 | 989 | 1107 | |
| Timestral-209M | ranked, one readout | 1065 | 1050 to 1080 | 1024 to 1103 | 1513 | 862 | 856 | 1066 | |
| LightGBM | tabular, defaults | 1056 | 1036 to 1079 | 994 to 1125 | – | – | – | – | |
| Timestral-123M | ranked, one readout | 1051 | 1036 to 1066 | 1011 to 1092 | 1493 | 848 | 847 | 1055 | |
| Timestral-28M | ranked, one readout | 1030 | 1014 to 1046 | 986 to 1072 | 1457 | 850 | 796 | 1027 | |
| Toto-Open-Base-1.0 | ranked, one readout | 1030 | 1015 to 1044 | 972 to 1085 | 1143 | 671 | 1453 | 1013 | |
| Timestral-5M | ranked, one readout | 1012 | 996 to 1028 | 961 to 1059 | 1367 | 850 | 879 | 1017 | |
| ZERO | no encoder | 1000 | 977 to 1023 | 924 to 1067 | – | – | – | – | |
| Random-init LeSaturn (control) | control | 978 | 956 to 999 | 911 to 1043 | – | – | – | – | |
| Raw reference | no encoder | 933 | 914 to 950 | 820 to 1022 | – | – | – | – | |
| TimesFM-2.5-200M | ranked, one readout | 838 | 814 to 861 | 776 to 897 | 1242 | 651 | 631 | 831 | |
| CatBoost ‡ | tabular, defaults | 1153 | 1132 to 1175 | 1075 to 1230 | – | – | – | – | 23% |
| XGBoost ‡ | tabular, defaults | 1101 | 1080 to 1122 | 1031 to 1170 | – | – | – | – | 10% |
| RealMLP ‡ | tabular, defaults | 992 | 968 to 1019 | 912 to 1069 | – | – | – | – | 33% |
Open dataset questions
Questions about datasets that this version leaves open; none changes a score.
- asos_lows_b: its event onsets are not independent of those of asos_lows_c (a review on CAFE #16 found most within a day); whether to pool them is a review question carried over from earlier releases (carryover097.md); no decision is recorded.
- Hill of Towie (HOT): its label rule (stopping alarms of at least 6 hours, weather codes removed) is a review question carried over from earlier releases (carryover097.md); no decision is recorded.
- cdip_waves_c: a review question carried over from earlier releases (carryover097.md); no decision is recorded.
- SMAP and MSL (pooled into NASA): their near-duplicate clusters are a review question carried over from earlier releases (carryover097.md); no decision is recorded.
- KUKA: threshold-easy. Its admission record says: Disclosed: a single threshold of ~1.75 Nm on the external-torque channels finds the collisions with F1 0.92.
- HAI: HAIEnd 23.05 left out (same two 23.05 recordings and labels through other tags); whether to add it is open.
- CAFUC2: out by check 2 (synthetic faults written into recorded flights); only Jonas Petersen can reverse it.
Heat maps
One row per model, one column per dataset. Lighter is lower and darker is higher, so the scale also reads in grey and for colour-blind readers. A thick edge marks the best ranked model on a dataset. The rows follow the switches above the board.
Breakdowns
Per dataset
Best and median are over ranked models. A flag says a baseline beats every model on that dataset, or reaches at least the median model. Those datasets stay in on purpose.
Dataset groups
Domain groups are for browsing and carry no weight in any score. Numbers are the main board's. To see the board without a group, use the switches at the top.
Pair verdicts
Row against column. Hover or tap a cell for the difference, its interval and the Holm p. Unresolved does not mean equal.
Tiers
CAFE score
Tier 1 pj_better_10m ◊, Mantis
Tier 2 pj_better_3p7m ◊, pjgood-warp-xview-combo-10M ◊, Chronos-2
Tier 3 LeSaturn-warppool-factorized-7.4M ◊
Tier 4 pj_better_1m ◊, MantisV2
Tier 5 NuTime
Tier 6 Timestral-209M, Timestral-123M
Tier 7 Timestral-5M, Timestral-28M, Toto-Open-Base-1.0
Tier 8 TimesFM-2.5-200M
C, classification
Tier 1 Chronos-2, pjgood-warp-xview-combo-10M ◊, Timestral-209M
Tier 2 Timestral-123M, pj_better_10m ◊, pj_better_3p7m ◊
Tier 3 Timestral-28M
Tier 4 Mantis, LeSaturn-warppool-factorized-7.4M ◊, NuTime, Timestral-5M, MantisV2
Tier 5 pj_better_1m ◊
Tier 6 TimesFM-2.5-200M
Tier 7 Toto-Open-Base-1.0
A, anomaly detection
Tier 1 Mantis, pj_better_10m ◊, pj_better_3p7m ◊, pjgood-warp-xview-combo-10M ◊, pj_better_1m ◊, MantisV2, NuTime, LeSaturn-warppool-factorized-7.4M ◊, Chronos-2
Tier 2 Timestral-5M, Timestral-209M, Timestral-28M, Timestral-123M
Tier 3 TimesFM-2.5-200M
Tier 4 Toto-Open-Base-1.0
FE, forecasting events
Tier 1 Mantis, pj_better_10m ◊, Toto-Open-Base-1.0, LeSaturn-warppool-factorized-7.4M ◊
Tier 2 pj_better_3p7m ◊, Chronos-2
Tier 3 pjgood-warp-xview-combo-10M ◊, pj_better_1m ◊
Tier 4 MantisV2
Tier 5 NuTime
Tier 6 Timestral-5M, Timestral-209M, Timestral-123M
Tier 7 Timestral-28M
Tier 8 TimesFM-2.5-200M
Sensitivities
With and without A
Computed from the per-dataset values on this page. Ranks count the ranked rows only.
Other rule sets and dataset choices
Each row is a whole board under one changed rule, from sens097.json.
Datasets resampled
The datasets are drawn again with replacement within each task. Computed by sens097.json (sens095.py), 10,000 draws, each also resampling the test material. This asks how much the order depends on which datasets are in the benchmark, which the board's own interval does not cover.
Noise
Spread over pair noise, this version (the 1.0 test's A signal-to-noise is in the 1.0 test section)
Recomputed from this version's draws: the spread of the ranked rows' scores divided by the test-material noise of a pair. The other sources below are not in it.
A null floors per dataset
Each null is normalised as the dataset's score is, so 0.5 is chance. They are shown as unranked rows; the elapsed-time nulls also gate new A datasets (Amendment 13 item 4). In 0.9.7.2 an A dataset is admitted only with at least 15 Eval series, at least 20 anomaly segments and a median anomaly share of at most 0.3, and a new one also needs the better elapsed-time null at most 0.65 (Amendment 13 items 2 and 4; the card's Admission section lists every candidate). These scores read no model.
13 A datasets are admitted; the rule asks for at least 5. The mean of their best data-free scores is 0.550, and 15 of 15 ranked rows score above it on those datasets; the rule asks for at least half. So A counts in the CAFE score.
Source: the data-free rows of board097.json (centre assignment, Eval series).
Rules in plain words
Inputs
Every encoder gets real samples with no padding and no mask. What an encoder does inside, such as padding to its own context or normalising its input, counts as part of the model under test. The models table lists the input rules each row used.
On C, a recording of 512 samples or fewer is stretched to 512 by linear interpolation for every model, which changes the time scale in the same way for every encoder. A longer recording goes to the model whole: a model that accepts variable length gets it up to its maximum context, most recent samples kept, and a model with a fixed input length of 512 gets it block-averaged to 512. On A, the window is 256 real samples ending at the scored moment, never stretched; its score goes to the window's centre step, and a series needs a prefix of at least 512 samples or it leaves the list. On FE, every model gets the last 512 samples before the forecast time. Rows that embed no window, the tabular rows and hand-made references, keep their registered inputs.
Heads
The head is the only thing fitted, and it is the same for every model. C uses L2 logistic regression on one block per channel: a model's native width when it is at most 256 per channel, and wider embeddings projected to 256 per channel by a fixed random projection (at most 8,192 in total), with its penalty chosen by cross-validation inside the training split. A uses no labels: it scores a window by the mean of its 5 smallest Mahalanobis distances to the windows of the series' own prefix. FE fits one ridge regression per lead time on the embedding at the end of the context, with 3 head seeds.
Scores
Each dataset gives one number on the same scale, 0.5 for chance and 1 for perfect. C uses balanced accuracy rescaled for the number of classes, A uses VUS-PR after the prefix rescaled against random scores, and FE uses stratified AUROC averaged over lead times and head seeds. A task score is the plain mean over its datasets. The CAFE score is the mean of C, A and FE.
Readouts
Each model has one readout, the same on C, A and FE. The candidates are m0 (the released embedding), m1, m2, m3 and m6, as far as the model's code exposes them; the pick has the highest validation CAFE score, the mean over the tasks of cross-validation on the training split for C, the Tuning series for A and the inner cross-validation of the ridge head for FE. A candidate within 0.005 of the best loses to an earlier one. No test value is read. The picks were made in 0.9.5 and not rerun; the A part of the validation score used the Tuning series of the 0.9.5 A datasets, which were the Forgis rows' development set (Amendment 9 item 2).
Intervals
An interval is a paired 95% percentile bootstrap of the test material inside each dataset: test samples or splits on C, Eval series on A with near-duplicates resampled together, time blocks on FE. There are 10,000 draws, the same for every model. The datasets are held fixed, so an interval says nothing about how a model would do on other datasets; the resampled table under Sensitivities speaks to that.
Verdicts and tiers
Every pair of ranked models gets one of three verdicts. It is better if the Holm-corrected two-sided bootstrap p is below 0.05. It is practically equal if not resolved and the 95% interval of the difference lies inside plus or minus 0.01. Otherwise it is unresolved, which means the data do not say. A pair of single-seed models less than 0.009 apart is also marked within seed noise. Tier 1 holds the models above the first one resolved below the top model, and the next tier starts there, so a model in a lower tier can still be unresolved against the top one. Rank inside a tier is not a claim.
Admission checks
A dataset must come from an inanimate physical system, its label must be a state, type or identity of that system or an event observed in the record, it needs at least 100 test samples on C or 1,000 events on FE, and only the largest dataset of a recording campaign stays. In 0.9.7.2 an A dataset needs at least 15 Eval series, at least 20 anomaly segments and a median anomaly share of at most 0.3, with at most 300 series per source of independent runs and 100 per source with several series per asset; a new A dataset also needs the better of the rising and falling elapsed-time nulls at most 0.65, a data-free check that removed RflyMAD, OnboardEU and TCABR; a new FE dataset needs at least 300 events, 30 independent units or days and data-free reference rows below fixed limits (Amendment 13 items 2, 4 and 5). A series needs the prefix above. Not every check is free of model scores: the C candidate SNS HVCM had to pass a combo-10M minus random-init LeSaturn gate on its own cells, and six of the 0.9.7.2 drops (C 3W, bosch, soredd_abc; FE ngafid_hastall, substorm_omni, epa_aqs_pm25) were informed by scores (Amendment 13 items 1 and 6). A free forecast beating the best model was part of the reason to drop epa_aqs_pm25 and substorm_omni, while kept FE datasets where a free forecast also wins stay in; the boards show where that happens.
Conflict of interest
Forgis maintains CAFE and developed 5 of the 15 ranked models, all with CAFE Eval scores visible. Jonas Petersen of Forgis requested Amendment 13 with the 0.9.6 board known, and Amendment 15 (0.9.7.2) with the released 0.9.7 board and its per-dataset A signal-to-noise known (from 1.0 on UKWIND to 6.1 on KUKA), after UTAQ, RCFPOWER, PVLAZ and NOBOOM_M202210 had been measured without a model (2026-11-05 22:37Z to 22:49Z). Forgis staff chose the drops, adds, caps and thresholds of 0.9.7 with the 0.9.6 board, its separability table and a per-dataset comparison of the Forgis rows known; some drops were informed by scores (Amendment 13 item 1), the two C additions were accepted after a screening that scored pjgood-warp-xview-combo-10M ◊ against its random-init twin on them, and the A thresholds were placed in gaps of the 0.9.6 data. Applied to the 0.9.6 scores, the drops alone raise the mean ◊ lead (see What changed in 0.9.7.2). The pair count of the test that decides between 0.9.7.2 and 0.9.5 as the CAFE 1.0 candidate was fixed before any 0.9.7 cell existed (Amendment 13 item 9; Amendment 15 item 4 applies it to 0.9.7.2); its reading of the A signal-to-noise was fixed at 19:02Z on 2026-11-05, after the first 0.9.7 A cells existed and before any was read. The boards under older rules stay published at their tags. FE is built with PrecursorBench, a Forgis benchmark (built by a Forgis team member; Forgis/PrecursorBench on the Hub): 14 of the 15 FE datasets come from it, and the ◊ variant counts above include variants scored on PrecursorBench Eval data. The mean ◊ lead (mean ◊ row minus mean other ranked row) is +0.009 on C, +0.021 on A and +0.050 on FE; the boards without each task are under Sensitivities. The C admission gate of Amendment 13 item 6 measures the pretraining gain of one ◊ model (pjgood-warp-xview-combo-10M against the random-init LeSaturn row); no third-party model's gain is part of it, so it is score-informed in favour of the ◊ rows. It stays as written for this version and is to be replaced in the next version by a gate that reads no ranked row.
What the board does not show
The board does not show performance after fine-tuning, because nothing is fine-tuned. It does not cover datasets outside the list, and its intervals leave out pretraining seed, head training set and readout choice. It says nothing about value forecasting, because FE scores events only. Run time is reported and never scored. CAFE publishes scores and no data.
Known limitations, as written on the dataset card
- Each model keeps the readout chosen for it in 0.9.5 (Amendment 13 item 7), chosen without the 0.9.7.2 datasets.
- The drops of 0.9.7 were chosen with the 0.9.6 board known; some of them were informed by scores (Amendment 13 item 1), and the A thresholds sit in gaps seen in the 0.9.6 data, so they are post-hoc cut-offs.
- The SNS HVCM gate cells were computed after the A cells of the first admission waves, not first as Amendment 13 item 6 said (PREREG09 note of 2026-11-05 19:05Z); no score had been read.
- UR5e is under a non-commercial licence (CC BY-NC 4.0).
- On HAI (7 recordings), UKWIND (5 recordings), HOT (9 recordings), ESA (2 recordings), KUKA (33 recordings), UTAQ (7 recordings) and RCFPOWER (3 recordings), some A Tuning series are other blocks of the same recordings as Eval series, though no series is in both. The readouts were chosen in 0.9.5 on the Tuning series of CARE_A, CARE_C, ESA_M1, ESA_M2, HAI, HOT, MSL, SKAB, SMAP, UKWIND and W3, so this matters where those datasets overlap the 0.9.7.2 ones; for datasets new in 0.9.7.2 (KUKA among them) no readout was chosen on their Tuning series. The recording-clustered sensitivity of the test is under the 1.0 test. The A Tuning series were also the ◊ rows' development set, so on these datasets ◊ development touched recordings whose other blocks are in Eval.
- On 7 of 15 FE datasets (ndbc_buoy_v2_b, wind_genbearing_hot, towie_genbearing_hot, noaa_coops_surge_b, asos_lows_b, cdip_waves_c and heatpump_defrost) a forecast with no encoder scores above every ranked model; FE is also where the ◊ lead is largest. A free forecast beating the best model was part of the reason to drop epa_aqs_pm25 and substorm_omni, and the same holds on these kept or added datasets (see Baselines).
- On UR5E a data-free elapsed-time row (0.616) scores above every ranked model (best 0.612); see Baselines. Each UR5e series puts the last rows of a separate normal run, recorded earlier, before the anomalous run (build_ur5e.py), so prefix and scored part come from different runs.
- PreDist: the 7 days appended after each fault are the one build step that reads an event time; on PreDist and NoBOOM a score that follows elapsed time does well, and the data-free rows show by how much.
- Recording length carries label information in two C datasets, in the source data itself: a classifier that sees only the length scores uea/AsphaltPavementTypeCoordinates 0.720 and ucr/PLAID 0.596 (see Datasets admitted and removed); every other C dataset has one length per recording. The variable-length models see the length of recordings above 512 samples and the block-averaged models do not.
- FactoryNet's README warns that recording context partly predicts fault labels, so real fault evaluation should stay within one recording session.
mv06/vorausand the other pooled C datasets mix sessions, and a voraus split tests settings not seen in training. - voraus-AD comes from FactoryNet's copy, not the publisher's files, under CC BY-NC-SA 4.0. Forgis is a company, so CAFE publishes scores only, and a legal reading is still open.
- The weights of the Forgis rows are not public. Each carries a sha256 under Models, so a later release can be checked against it, and until then outsiders cannot rerun those rows.
- At least 66 distinct Saturn-family checkpoints, including the five ranked Forgis rows and two HEPA-lineage precursors, have CAFE or PrecursorBench 1.4 Eval scores on datasets of the 0.9.3.1 board, with records dated from 2026-08-04 to 2026-10-28. Before its submission, each ranked row had at least this many other variants scored: LeSaturn-warppool-factorized-7.4M 43, pjgood-warp-xview-combo-10M 59, pj_better_3p7m and pj_better_10m 64, and pj_better_1m 65. These are lower bounds counted from repository records, because some run trees and lane outputs are unavailable, and they exclude readout variants, controls, evaluation seeds, PrecursorBench v1 runs and development-harness runs.
- MantisV2 is read through the sweep's adapter, and its m0 is the sweep's released-readout rule, not independently confirmed.
- Hill of Towie labels are inferred stops, with rules made without any score. cdip_waves_c was rebuilt because
series.npydiffers from the pinned file; every ranked row was recomputed on the rebuilt file. - The near-duplicate rule clusters SMAP series with long constant stretches although their correlation is near zero, and four UKWIND turbines had identical series that still need checking at the source (found on the series of 0.9.7 and earlier; not rechecked on the 85 UKWIND Eval series of 0.9.7.2).
- Mantis and NuTime were pretrained on data that includes UCR and UEA training splits. The pretraining corpora of the ◊ rows are not stated on this card: the TheGem report (Forgis) says a generator of synthetic physical systems supplies all of Saturn's pretraining data, and the ◊ rows are Saturn-family models, but this card has not checked it, and whether any CAFE recording, its source system, or FactoryNet data was in their pretraining is not established for any ◊ row. This is an open item.
- FE reads the last 512 samples and A scores windows of 256 for every model; the ◊ rows were trained on 512-sample windows (the input caps under Models), and models with longer native contexts (Chronos-2, TimesFM-2.5, Toto) are cut to 512 on FE. The rule is the same for every model; whether a fixed 512-sample input favours models trained on that length was not measured.
- REASSEMBLE is built from a label-blind partial fetch (zip positions 0 to 78, one failed transfer; 18 Eval series); a full fetch would roughly double it, and it is the noisiest A dataset (see 0.9.7.2 beside 0.9.7).
- 23 tabular tasks ran over the 1-hour per-dataset cap of Amendment 3 and were not retried, so those tabular rows have no CAFE score; the missing cells are compute-capped, not failures of the method.
- Re-selection under the cap moved UKWIND__K06_b0004 (UKWIND) from Tuning into Eval: a Tuning series of 0.9.5 on which the readouts were chosen is now scored in Eval (the rule as written: hash order, Tuning = the first ceil(0.15 m)). It is the only such series of the 992.
- The 0.9.7.2 A series files were checked against the files staged on Clariden by hand (audit 16: 321 of 321 sha256 equal); the units_sha gate of gates097.json covers the 0.9.7 units only.
- The dataset builders ran in the environment recorded in
data097/src/ENV_builders0972.txt; rebuilding UTAQ under pandas 3.1 changes 9 series by at most 4.5e-13 (audit 16), far below any score digit shown. - The run's event log (
timing097.json) has no submit events for the 0.9.7.2 cluster jobs; for 0.9.7.2 the job record is sacct (the job table under What took how long). - On the Space, the tabs v0.9.6/ and v0.9.5/ were added by earlier releases and are never re-sent, so their banners still name 0.9.7 as the current release; the main page is always the current one.
- 0.9.7.1 was never released; its candidates were folded into 0.9.7.2 (Amendment 15 item 1). The FE candidate PyrNet named for 0.9.7.1 is not in 0.9.7.2: FE is unchanged by Amendment 15 item 4.
How to submit a model
CAFE has no upload form. To propose a model, open a discussion on the dataset page with a public checkpoint pinned to a commit, its licence, code that turns an array of shape (samples, channels, T) into an embedding, with the largest T it accepts, the list of readouts it exposes, and the number of variants you scored on CAFE datasets before submitting, which the protocol publishes with the row. Forgis then runs its cells under the rules above, and the row appears with its marks in a dated version.
Datasets and models
Datasets and licences
CAFE redistributes no data.
Models
Every model is frozen.
Version history
Figures and tables for reports
Every figure is a file in this Space. Use the links under each one. Tables are below in a form you can copy, and each also exists as a CSV file. Version 0.9.7.2.
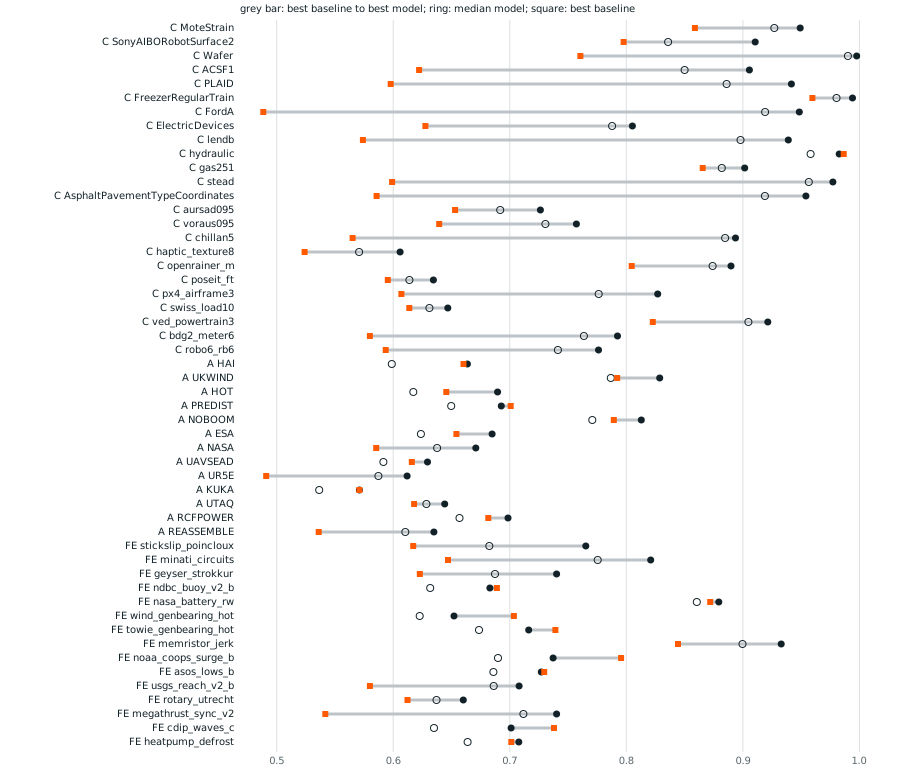


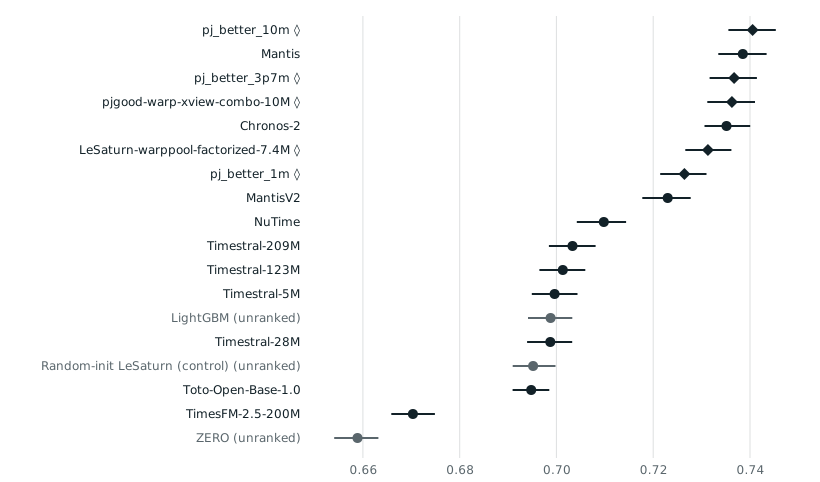
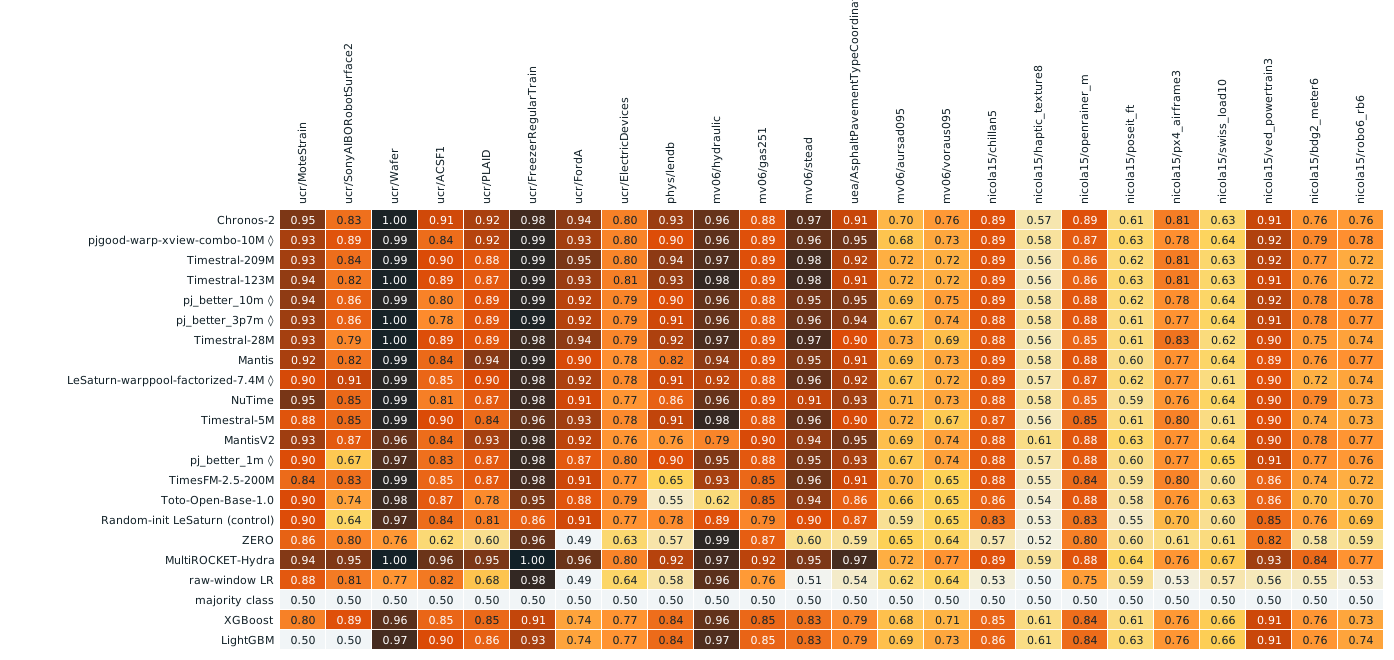
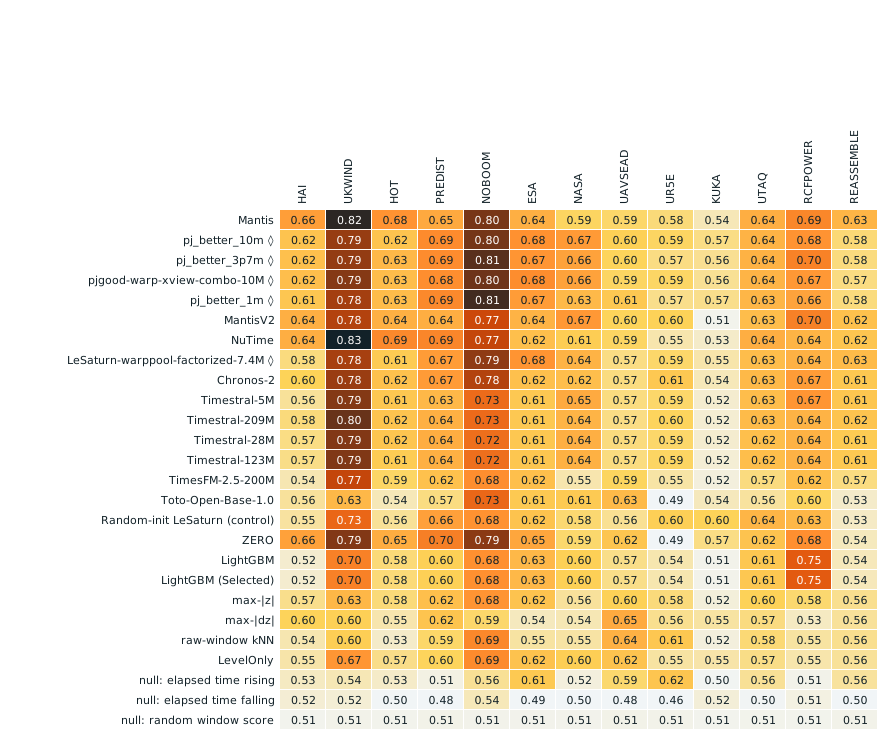
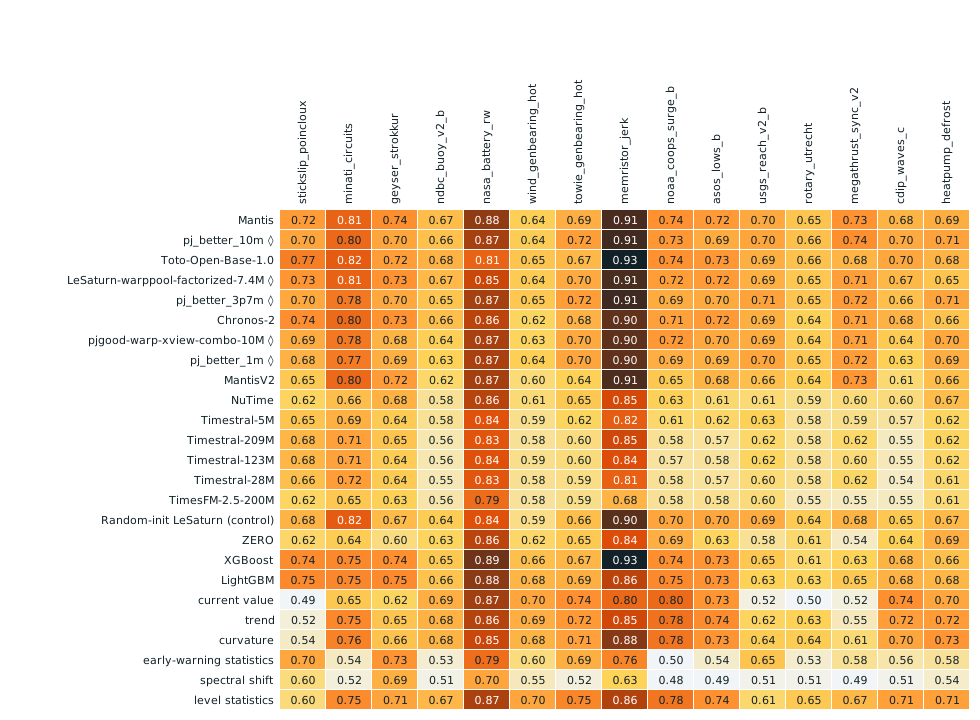
Not offered here (figures of the released 0.9.7 page, or older than this board): baselines097.svg, elo097.png, baselines.png, cost.png, elo_cost.png, gaps.png, leaderboard.png, method_board.png, money_plot.pdf, money_plot.png, variance_breakdown.png, variance_pie.png.
Tables
Glossary
- A
- Anomaly detection: find the abnormal stretches in a series. Scored by VUS-PR after the prefix.
- anomaly segments
- Labelled runs of consecutive anomalous steps in the Eval series of an A dataset.
- AUROC
- The chance that a randomly picked positive case gets a higher score than a randomly picked negative one. FE uses a stratified version, compared within fold, unit and month.
- balanced accuracy
- Accuracy averaged over classes, so a large class does not dominate. C rescales it so that chance is 0.5.
- baseline
- A row with no learned encoder: ZERO on every task, and current value on FE. Shown on every board, never ranked. The random-init control and the other references are listed beside them.
- best baseline
- On one dataset, the highest-scoring of the baselines the board compares with.
- board effect
- Pairs resolved on the CAFE score without a dataset minus with it; negative means the dataset helps.
- bootstrap
- Drawing the test material again with replacement to see how far a score moves. CAFE uses 10,000 draws.
- C
- Classification: say what a recording shows. Scored by balanced accuracy.
- CAFE score
- The mean of the task scores that count on this release: C, A and FE.
- cap
- The most series a source may give an A dataset: 300 for independent runs, 100 for several series per asset (Amendment 13 item 2).
- cell
- One model's score on one dataset, stored with its bootstrap draws.
- chance-normalised
- Rescaled so that random output gives 0.5 and a perfect result gives 1.
- check 2
- The admission check that the label is a state of, or an event in, the physical system.
- combo minus twin
- C score of pjgood-warp-xview-combo-10M minus that of the random-init LeSaturn row (3.7 M parameters, another architecture; not a matched twin of the 10.6 M combo), per repeat: a model-specific check that pretraining helps on a dataset.
- conflict of interest
- Forgis runs CAFE and also builds some of the models it ranks. Those rows carry the mark ◊.
- datasets resampled
- The board recomputed 10,000 times with the datasets of each task drawn with replacement as well as the test material; the measure of the 1.0 test.
- drops only
- The 0.9.6 board with the datasets removed in 0.9.7 taken out and nothing added.
- elapsed-time best
- The better of the two data-free scores that rise or fall with time since the prefix.
- elapsed-time gate
- A new A dataset is admitted only if the better of the rising and falling elapsed-time scores is at most 0.65.
- embedding
- The vector of numbers a frozen model returns for a window. It is all a head ever sees.
- Eval series
- The series of an A dataset that are scored. Tuning series are kept apart.
- F3 thresholds
- The highest time-since-last-event and time-of-day scores on the kept FE datasets; a new FE dataset may not exceed them.
- FE
- Forecasting events: say whether an event will happen within the next lead time. Scored by AUROC.
- foundation model
- A network pretrained on many time series and then used for jobs it did not see.
- free forecast
- An FE reference row that reads the series without a model, such as current value or trend.
- frozen
- The weights are not changed for CAFE. No fine-tuning on any dataset.
- GPU-hours, upper bound
- Sum of task wall times over 3600; tasks share GPUs, so the GPU time used is at most this.
- H0, H1, H2
- The C head candidates of Amendment 12: the 0.9.5 head, the same with an 11-value penalty grid, and that after a 256-component projection fitted on the training split.
- head
- The small model fitted on the embedding for one task. It is the same for every model.
- Holm
- A step-down correction that keeps the error rate over a whole family of pair tests at the stated level.
- input rules
- What each encoder gets: on C the whole recording (block-averaged to 512 for fixed-length models; stretched to 512 when it is 512 samples or shorter), on A a window of 256 real samples, on FE the last 512 samples. No padding, no mask.
- Kendall tau
- Agreement between two orderings: 1 means the same order, 0 means no relation.
- lead time
- How far ahead an FE head has to warn.
- Mahalanobis distance
- Distance that takes account of the spread and correlation of the normal windows.
- Median over Eval series of the labelled share of the scored part; at most 0.3 to be admitted.
- near-duplicate cluster
- Eval series joined by a rule on the data alone and resampled as one block, so that copies do not narrow the interval.
- node-hours
- Elapsed time of a cluster job times its nodes, from sacct.
- non-commercial
- A licence that allows use for non-commercial purposes only, such as CC BY-NC 4.0 (UR5e).
- not admitted
- A candidate measured without a model and left out by a rule, with the reason recorded before any cell.
- null
- A score that reads no model: elapsed time rising, elapsed time falling, or a random number per window.
- null floor
- A dataset's highest null. A model at or below it has shown nothing the clock or chance could not.
- One readout
- The one readout a model uses on C, A and FE, picked by the highest validation CAFE score without reading any test value. This is the main board's rule.
- pair noise
- Median over all pairs of ranked models of the bootstrap SD of their paired score difference.
- paired
- Every model is scored on the same random draws, so a difference between two models does not depend on which material a draw picked.
- pooled
- Datasets of one release or paper counted as one dataset, its score the mean over all their Eval series (Amendment 13 item 2).
- practically equal
- A verdict: not resolved, and the 95% interval of the difference lies inside plus or minus 0.01.
- prefix
- The normal stretch at the start of an A series, used to fit the head.
- readout
- Which internal tensor of a model is taken as its embedding.
- reference
- A hand-made row that embeds nothing, such as max-|z| or current value. Shown, never ranked.
- resolved alone
- Pairs of ranked models resolved on a board made of one dataset alone.
- signal-to-noise (separability)
- On one dataset or task, the mean absolute score gap between two ranked models divided by the median bootstrap SD of that gap.
- spread SD
- SD of the ranked models' scores on one dataset or task: how far apart the models are.
- tabular row
- A gradient-boosted or MLP learner on hand-written statistics of the window. Shown, never ranked.
- tau with the task
- Kendall tau between the models' order on one dataset and their mean over the task's other datasets.
- tier
- Models in score order. Tier 1 holds the models above the first one resolved below the top model; the next tier starts there and is built the same way, so a model in a lower tier can still be unresolved against the top one.
- Tuning series
- Series of an A dataset kept out of scoring. Only readout selection reads them.
- unresolved
- A verdict: the data do not separate the two models, and the interval is too wide to call them equal.
- VUS-PR
- Volume under the precision-recall surface, the metric for A.
- windows per second
- Scored A windows of a model's A cells divided by their task wall time.
- within seed noise
- A pair of single-seed models closer than 0.009 on the CAFE score or on a task board, 1.96 times the total SD of a single-seed difference in the 0.9.2 noise budget (0.0044, of which pretraining seed is 0.0018), a normal approximation.
- ZERO
- A fixed random projection of the raw window with no learning. The no-encoder reference.
- †
- A mean over fewer datasets than the view has, because some cells do not exist in this readout mode.
- ◊
- A model developed by Forgis with access to CAFE Eval scores.
- ◊ lead
- Mean CAFE score of the ◊ rows minus that of the other ranked rows; reported, part of no rule.