
0.9.6 did not pass the test fixed beforehand for CAFE 1.0 (51 resolved pairs with the datasets resampled; 54 were needed), so 0.9.5 stays the CAFE 1.0 candidate. How the two compare · the 0.9.5 page.
Main board
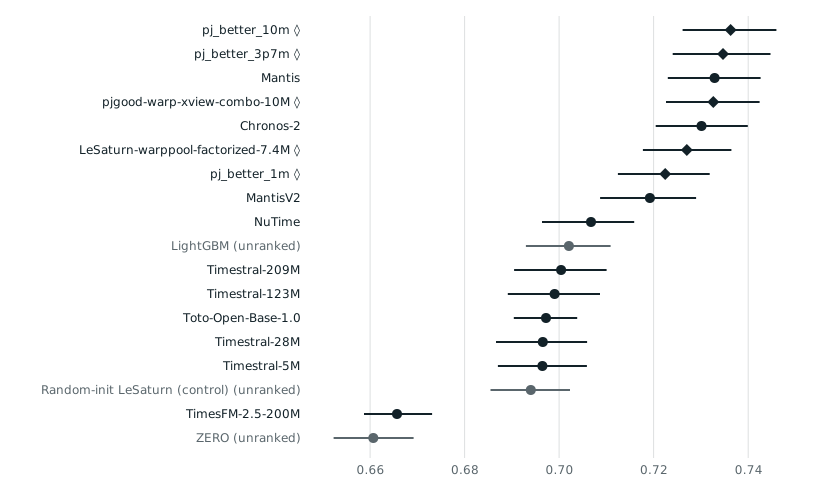
5 of 15 ranked models share tier 1, so the order inside that tier is no claim. The board rests on 25 C, 14 A and 17 FE datasets. Main board: one readout per model.
Forgis runs CAFE and developed 5 of the 15 ranked models, marked ◊, with CAFE test scores visible during their development. They get no special colour here. You can take them out of every table with the switch above the board.
◊ Forgis row. Kind tells unranked rows apart: baseline, reference, tabular. Click a column to sort. The glossary near the end explains every term.
0.9.5 and 0.9.6
0.9.6 adds 8 C datasets, 2 A datasets and 1 FE dataset to 0.9.5, and fits the C head over a wider grid of penalties (head H1). Every model keeps its 0.9.5 readout. Scores of the two versions are means over different datasets, so a change in score is not a change in the model; ranks and tiers are what can be compared. The full 0.9.5 page is kept here.
Before any 0.9.6 score was read, we fixed one test for which release becomes CAFE 1.0 (PREREG09 Amendment 11 item 7): count the pairs of the 15 ranked models that stay resolved when the datasets themselves are resampled (10,000 draws, Holm correction). 0.9.5 resolves 49 of 105 pairs and 0.9.6 resolves 51. The mark was 54: 0.9.6 does not reach it, and 0.9.5 stays the CAFE 1.0 candidate. No pair of models is called better in opposite directions by the two versions.
Pair verdicts on the main board, out of 105 pairs:
| board | better, 0.9.5 | better, 0.9.6 | unresolved, 0.9.5 | unresolved, 0.9.6 |
|---|---|---|---|---|
| CAFE score | 73 | 73 | 15 | 11 |
| C | 70 | 74 | 16 | 3 |
| A | 18 | 37 | 83 | 63 |
| FE | 87 | 87 | 9 | 7 |
Ranked rows of both versions, in the 0.9.6 order.
| model | rank 0.9.5 | rank 0.9.6 | move | tier 0.9.5 | tier 0.9.6 | score 0.9.5 | score 0.9.6 | change |
|---|---|---|---|---|---|---|---|---|
| pj_better_10m ◊ | 1 | 1 | = | 1 | 1 | 0.7448 | 0.7363 | −0.0086 |
| pj_better_3p7m ◊ | 2 | 2 | = | 1 | 1 | 0.7437 | 0.7347 | −0.0090 |
| Mantis | 3 | 3 | = | 1 | 1 | 0.7423 | 0.7329 | −0.0094 |
| pjgood-warp-xview-combo-10M ◊ | 4 | 4 | = | 1 | 1 | 0.7419 | 0.7326 | −0.0093 |
| Chronos-2 | 5 | 5 | = | 1 | 1 | 0.7400 | 0.7301 | −0.0099 |
| LeSaturn-warppool-factorized-7.4M ◊ | 6 | 6 | = | 1 | 2 | 0.7367 | 0.7270 | −0.0096 |
| pj_better_1m ◊ | 7 | 7 | = | 2 | 2 | 0.7295 | 0.7224 | −0.0071 |
| MantisV2 | 8 | 8 | = | 2 | 2 | 0.7275 | 0.7192 | −0.0083 |
| NuTime | 9 | 9 | = | 3 | 3 | 0.7148 | 0.7067 | −0.0080 |
| Timestral-209M | 10 | 10 | = | 3 | 3 | 0.7114 | 0.7004 | −0.0109 |
| Timestral-123M | 11 | 11 | = | 3 | 3 | 0.7096 | 0.6990 | −0.0106 |
| Toto-Open-Base-1.0 | 14 | 12 | ↑2 | 3 | 3 | 0.7027 | 0.6972 | −0.0055 |
| Timestral-28M | 13 | 13 | = | 3 | 3 | 0.7062 | 0.6965 | −0.0097 |
| Timestral-5M | 12 | 14 | ↓2 | 3 | 3 | 0.7067 | 0.6965 | −0.0103 |
| TimesFM-2.5-200M | 15 | 15 | = | 4 | 4 | 0.6726 | 0.6657 | −0.0069 |
Ranked rows of both versions, in the 0.9.6 order. 17 datasets in 0.9.5, 25 in 0.9.6.
| model | rank 0.9.5 | rank 0.9.6 | move | tier 0.9.5 | tier 0.9.6 | score 0.9.5 | score 0.9.6 | change |
|---|---|---|---|---|---|---|---|---|
| Chronos-2 | 1 | 1 | = | 1 | 1 | 0.8703 | 0.8365 | −0.0338 |
| Timestral-209M | 2 | 2 | = | 1 | 1 | 0.8700 | 0.8347 | −0.0353 |
| pjgood-warp-xview-combo-10M ◊ | 3 | 3 | = | 1 | 1 | 0.8674 | 0.8337 | −0.0336 |
| Timestral-123M | 4 | 4 | = | 1 | 1 | 0.8673 | 0.8327 | −0.0345 |
| pj_better_10m ◊ | 6 | 5 | ↑1 | 2 | 2 | 0.8607 | 0.8297 | −0.0310 |
| Timestral-28M | 5 | 6 | ↓1 | 2 | 2 | 0.8616 | 0.8290 | −0.0326 |
| pj_better_3p7m ◊ | 7 | 7 | = | 2 | 2 | 0.8601 | 0.8275 | −0.0326 |
| LeSaturn-warppool-factorized-7.4M ◊ | 8 | 8 | = | 2 | 3 | 0.8578 | 0.8232 | −0.0346 |
| Mantis | 10 | 9 | ↑1 | 3 | 3 | 0.8535 | 0.8225 | −0.0311 |
| NuTime | 11 | 10 | ↑1 | 3 | 3 | 0.8531 | 0.8215 | −0.0316 |
| Timestral-5M | 9 | 11 | ↓2 | 3 | 3 | 0.8545 | 0.8213 | −0.0332 |
| MantisV2 | 13 | 12 | ↑1 | 4 | 3 | 0.8458 | 0.8186 | −0.0272 |
| pj_better_1m ◊ | 12 | 13 | ↓1 | 4 | 4 | 0.8460 | 0.8150 | −0.0311 |
| TimesFM-2.5-200M | 14 | 14 | = | 5 | 5 | 0.8226 | 0.7952 | −0.0273 |
| Toto-Open-Base-1.0 | 15 | 15 | = | 6 | 6 | 0.7823 | 0.7678 | −0.0145 |
Ranked rows of both versions, in the 0.9.6 order. 12 datasets in 0.9.5, 14 in 0.9.6.
| model | rank 0.9.5 | rank 0.9.6 | move | tier 0.9.5 | tier 0.9.6 | score 0.9.5 | score 0.9.6 | change |
|---|---|---|---|---|---|---|---|---|
| pj_better_3p7m ◊ | 1 | 1 | = | 1 | 1 | 0.6643 | 0.6762 | +0.0119 |
| pjgood-warp-xview-combo-10M ◊ | 2 | 2 | = | 1 | 1 | 0.6610 | 0.6727 | +0.0116 |
| pj_better_10m ◊ | 3 | 3 | = | 1 | 1 | 0.6598 | 0.6718 | +0.0120 |
| MantisV2 | 4 | 4 | = | 1 | 1 | 0.6576 | 0.6649 | +0.0073 |
| Mantis | 5 | 5 | = | 1 | 1 | 0.6530 | 0.6634 | +0.0104 |
| pj_better_1m ◊ | 7 | 6 | ↑1 | 1 | 1 | 0.6477 | 0.6628 | +0.0151 |
| NuTime | 6 | 7 | ↓1 | 1 | 1 | 0.6496 | 0.6603 | +0.0107 |
| LeSaturn-warppool-factorized-7.4M ◊ | 8 | 8 | = | 1 | 2 | 0.6391 | 0.6518 | +0.0127 |
| Chronos-2 | 9 | 9 | = | 2 | 2 | 0.6390 | 0.6508 | +0.0117 |
| Timestral-209M | 10 | 10 | = | 2 | 2 | 0.6358 | 0.6420 | +0.0062 |
| Timestral-123M | 11 | 11 | = | 2 | 2 | 0.6344 | 0.6405 | +0.0061 |
| Timestral-28M | 12 | 12 | = | 2 | 2 | 0.6333 | 0.6402 | +0.0069 |
| Timestral-5M | 13 | 13 | = | 2 | 2 | 0.6320 | 0.6381 | +0.0061 |
| Toto-Open-Base-1.0 | 14 | 14 | = | 2 | 2 | 0.6077 | 0.6141 | +0.0063 |
| TimesFM-2.5-200M | 15 | 15 | = | 2 | 3 | 0.5947 | 0.6031 | +0.0085 |
Ranked rows of both versions, in the 0.9.6 order. 16 datasets in 0.9.5, 17 in 0.9.6.
| model | rank 0.9.5 | rank 0.9.6 | move | tier 0.9.5 | tier 0.9.6 | score 0.9.5 | score 0.9.6 | change |
|---|---|---|---|---|---|---|---|---|
| Mantis | 1 | 1 | = | 1 | 1 | 0.7205 | 0.7129 | −0.0076 |
| Toto-Open-Base-1.0 | 2 | 2 | = | 1 | 1 | 0.7182 | 0.7098 | −0.0084 |
| pj_better_10m ◊ | 3 | 3 | = | 1 | 1 | 0.7140 | 0.7073 | −0.0067 |
| LeSaturn-warppool-factorized-7.4M ◊ | 4 | 4 | = | 1 | 1 | 0.7131 | 0.7061 | −0.0070 |
| Chronos-2 | 5 | 5 | = | 2 | 2 | 0.7107 | 0.7031 | −0.0075 |
| pj_better_3p7m ◊ | 6 | 6 | = | 2 | 2 | 0.7066 | 0.7003 | −0.0063 |
| pjgood-warp-xview-combo-10M ◊ | 7 | 7 | = | 3 | 3 | 0.6973 | 0.6915 | −0.0058 |
| pj_better_1m ◊ | 8 | 8 | = | 3 | 3 | 0.6949 | 0.6896 | −0.0053 |
| MantisV2 | 9 | 9 | = | 4 | 4 | 0.6792 | 0.6741 | −0.0051 |
| NuTime | 10 | 10 | = | 5 | 5 | 0.6417 | 0.6385 | −0.0032 |
| Timestral-5M | 11 | 11 | = | 5 | 5 | 0.6337 | 0.6300 | −0.0037 |
| Timestral-209M | 12 | 12 | = | 6 | 6 | 0.6283 | 0.6246 | −0.0037 |
| Timestral-123M | 13 | 13 | = | 6 | 6 | 0.6273 | 0.6240 | −0.0033 |
| Timestral-28M | 14 | 14 | = | 6 | 6 | 0.6237 | 0.6204 | −0.0033 |
| TimesFM-2.5-200M | 15 | 15 | = | 7 | 7 | 0.6006 | 0.5987 | −0.0019 |
Heat maps
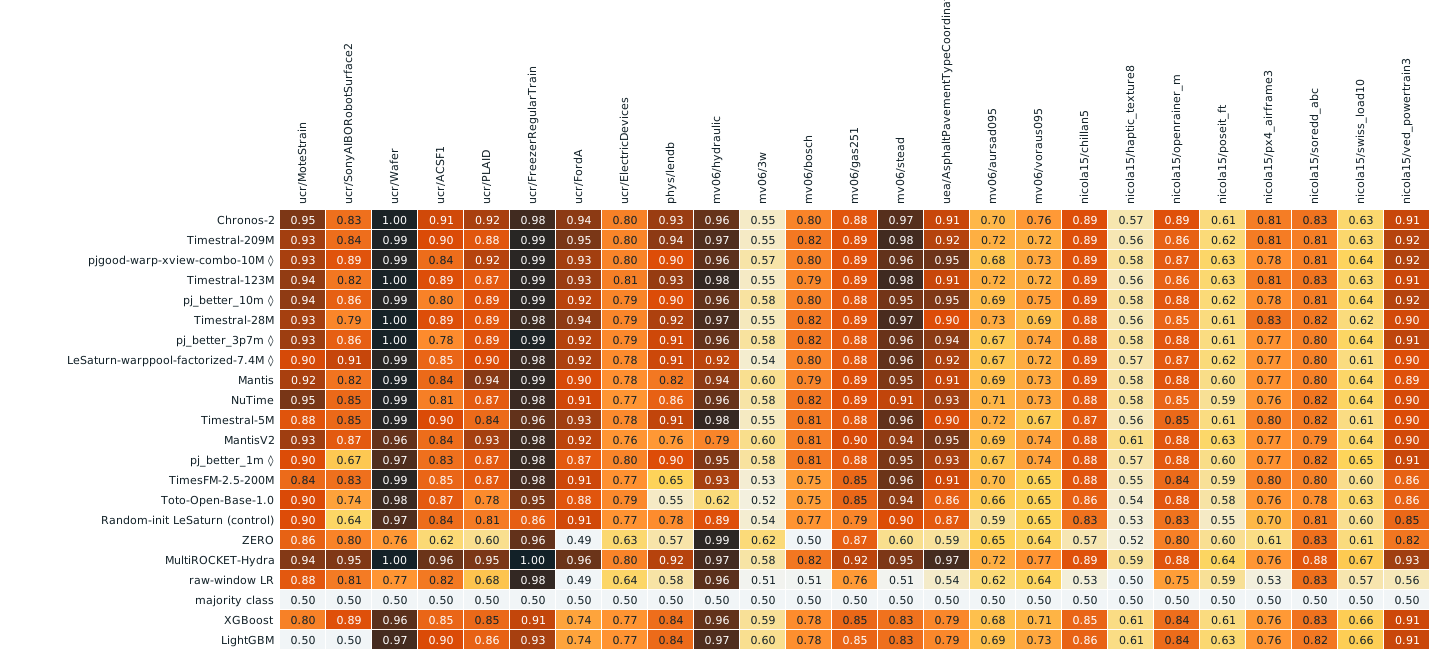
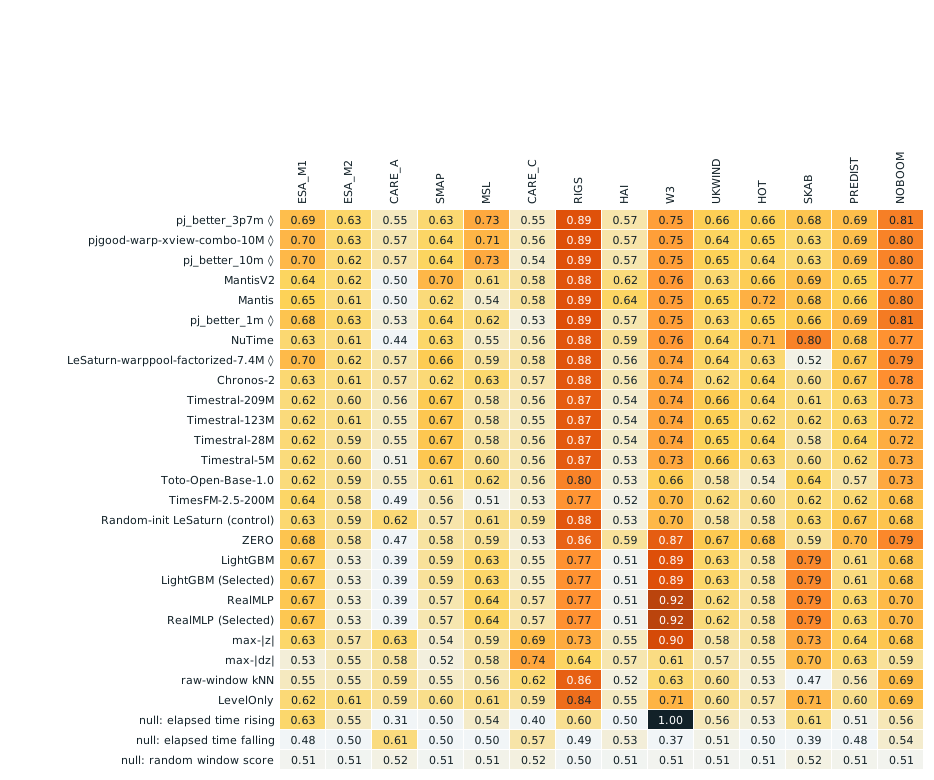
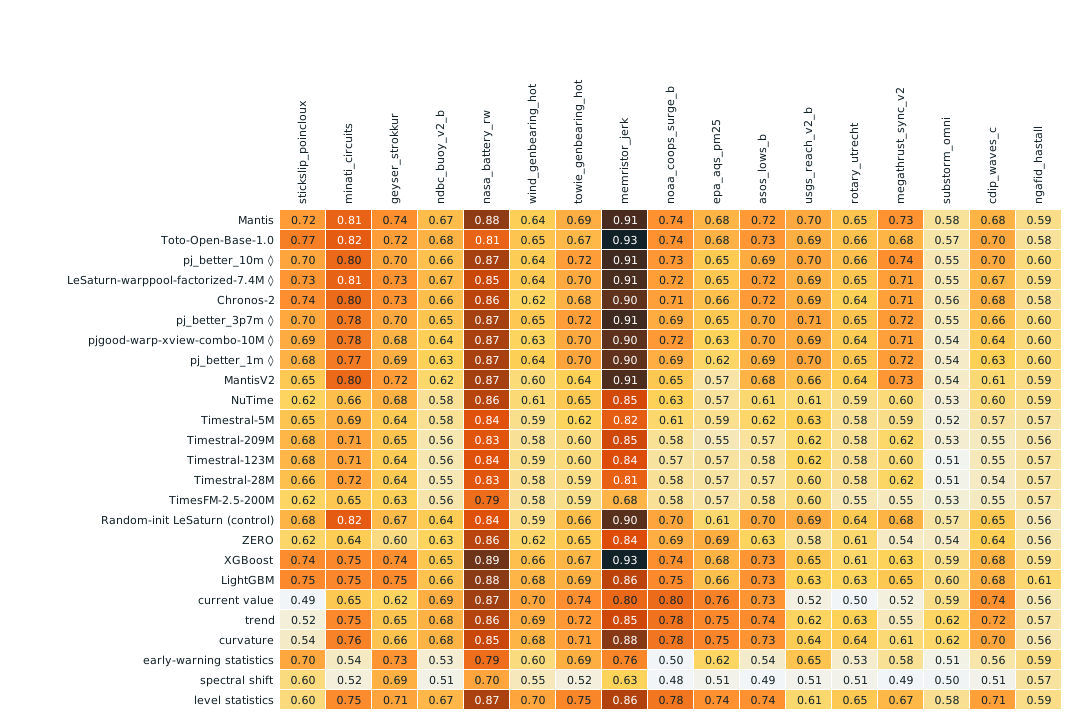
One row per model, one column per dataset. Lighter is lower and darker is higher, so the scale also reads in grey and for colour-blind readers. A thick edge marks the best ranked model on a dataset. The rows follow the switches above the board.
Breakdowns
Per dataset
Best and median are over ranked models. A flag says a baseline beats every model on that dataset, or reaches at least the median model. Those datasets stay in on purpose.
Dataset groups
Domain groups are for browsing and carry no weight in any score. Numbers are the main board's. To see the board without a group, use the switches at the top.
Pair verdicts
Row against column. Hover or tap a cell for the difference, its interval and the Holm p. Unresolved does not mean equal.
Tiers
CAFE score
Tier 1 pj_better_10m ◊, pj_better_3p7m ◊, Mantis, pjgood-warp-xview-combo-10M ◊, Chronos-2
Tier 2 LeSaturn-warppool-factorized-7.4M ◊, pj_better_1m ◊, MantisV2
Tier 3 NuTime, Timestral-209M, Timestral-123M, Toto-Open-Base-1.0, Timestral-28M, Timestral-5M
Tier 4 TimesFM-2.5-200M
C, classification
Tier 1 Chronos-2, Timestral-209M, pjgood-warp-xview-combo-10M ◊, Timestral-123M
Tier 2 pj_better_10m ◊, Timestral-28M, pj_better_3p7m ◊
Tier 3 LeSaturn-warppool-factorized-7.4M ◊, Mantis, NuTime, Timestral-5M, MantisV2
Tier 4 pj_better_1m ◊
Tier 5 TimesFM-2.5-200M
Tier 6 Toto-Open-Base-1.0
A, anomaly detection
Tier 1 pj_better_3p7m ◊, pjgood-warp-xview-combo-10M ◊, pj_better_10m ◊, MantisV2, Mantis, pj_better_1m ◊, NuTime
Tier 2 LeSaturn-warppool-factorized-7.4M ◊, Chronos-2, Timestral-209M, Timestral-123M, Timestral-28M, Timestral-5M, Toto-Open-Base-1.0
Tier 3 TimesFM-2.5-200M
FE, forecasting events
Tier 1 Mantis, Toto-Open-Base-1.0, pj_better_10m ◊, LeSaturn-warppool-factorized-7.4M ◊
Tier 2 Chronos-2, pj_better_3p7m ◊
Tier 3 pjgood-warp-xview-combo-10M ◊, pj_better_1m ◊
Tier 4 MantisV2
Tier 5 NuTime, Timestral-5M
Tier 6 Timestral-209M, Timestral-123M, Timestral-28M
Tier 7 TimesFM-2.5-200M
Sensitivities
With and without A
Computed from the per-dataset values on this page. Ranks count the ranked rows only.
Other rule sets and dataset choices
Each row is a whole board under one changed rule, from sens096.json.
Datasets resampled, and the chance of being first
The datasets are drawn again with replacement within each task. Computed by sens096.json (sens095.py), 10,000 draws, each also resampling the test material. This asks how much the order depends on which datasets are in the benchmark, which the board's own interval does not cover.
Noise
Signal-to-noise, this version
Recomputed from this version's draws: the spread of the ranked rows' scores divided by the test-material noise of a pair. The other sources below are not in it.
A null floors per dataset
Each null is normalised as the dataset's score is, so 0.5 is chance. They remove no dataset in 0.9.6: they are shown as unranked rows, and a dataset leaves A only if fewer than 5 of its series keep a prefix of 512 samples. These scores read no model.
14 A datasets are admitted; the rule asks for at least 5. The mean of their best data-free scores is 0.594, and 15 of 15 ranked rows score above it on those datasets; the rule asks for at least half. So A counts in the CAFE score.
Source: results/nulls096_summary.json (nulls095_summary.json plus PREDIST and NOBOOM from nulls096.json, centre assignment, Eval series).
Rules in plain words
Inputs
Every encoder gets real samples with no padding and no mask. What an encoder does inside, such as padding to its own context or normalising its input, counts as part of the model under test. The models table lists the input rules each row used.
On C, a recording of 512 samples or fewer is stretched to 512 by linear interpolation for every model, which changes the time scale in the same way for every encoder. A longer recording goes to the model whole: a model that accepts variable length gets it up to its maximum context, most recent samples kept, and a model with a fixed input length of 512 gets it block-averaged to 512. On A, the window is 256 real samples ending at the scored moment, never stretched; its score goes to the window's centre step, and a series needs a prefix of at least 512 samples or it leaves the list. On FE, every model gets the last 512 samples before the forecast time. Rows that embed no window, the tabular rows and hand-made references, keep their registered inputs.
Heads
The head is the only thing fitted, and it is the same for every model. C uses L2 logistic regression on one block per channel: a model's native width when it is at most 256 per channel, and wider embeddings projected to 256 per channel by a fixed random projection (at most 8,192 in total), with its penalty chosen by cross-validation inside the training split. A uses no labels: it scores a window by the mean of its 5 smallest Mahalanobis distances to the windows of the series' own prefix. FE fits one ridge regression per lead time on the embedding at the end of the context, with 3 head seeds.
Scores
Each dataset gives one number on the same scale, 0.5 for chance and 1 for perfect. C uses balanced accuracy rescaled for the number of classes, A uses VUS-PR after the prefix rescaled against random scores, and FE uses stratified AUROC averaged over lead times and head seeds. A task score is the plain mean over its datasets. The CAFE score is the mean of C, A and FE.
Readouts
Each model has one readout, the same on C, A and FE. The candidates are m0 (the released embedding), m1, m2, m3 and m6, as far as the model's code exposes them; the pick has the highest validation CAFE score, the mean over the tasks of cross-validation on the training split for C, the Tuning series for A and the inner cross-validation of the ridge head for FE. A candidate within 0.005 of the best loses to an earlier one. No test value is read.
Intervals
An interval is a paired 95% percentile bootstrap of the test material inside each dataset: test samples or splits on C, Eval series on A with near-duplicates resampled together, time blocks on FE. There are 10,000 draws, the same for every model. The datasets are held fixed, so an interval says nothing about how a model would do on other datasets; the resampled table under Sensitivities speaks to that.
Verdicts and tiers
Every pair of ranked models gets one of three verdicts. It is better if the Holm-corrected two-sided bootstrap p is below 0.05. It is practically equal if not resolved and the 95% interval of the difference lies inside plus or minus 0.01. Otherwise it is unresolved, which means the data do not say. A pair of single-seed models less than 0.009 apart is also marked within seed noise. Tier 1 holds the models above the first one resolved below the top model, and the next tier starts there, so a model in a lower tier can still be unresolved against the top one. Rank inside a tier is not a claim.
Admission checks
A dataset must come from an inanimate physical system, its label must be a state, type or identity of that system or an event observed in the record, it needs at least 100 test samples on C, 5 Eval series on A or 1,000 events on FE, and only the largest dataset of a recording campaign stays. A series needs the prefix above. The data-free nulls admit and remove nothing; they are shown beside the models. None of these checks reads a model's score, so datasets where a trivial row beats every encoder stay in and the boards show it.
Conflict of interest
Forgis maintains CAFE and developed 5 of the 15 ranked models. Those models were developed with access to CAFE test scores, and the owner of the benchmark asked for several rule changes while the order was known. Each amendment says what was known when it was written, and the boards under older rules stay published. Some of the latest rules help Forgis rows and some hurt them. Two decisions came after this board was seen. The 08:00Z deadline of 4 November, whose fallback would have made every model's readout m0, was withdrawn because 912 of the 920 jobs, the fallback's own m0 cells among them, finished after it (PREREG09, note of 2026-11-04 ~18:50Z); the m0 board is shown as a sensitivity. The note of 2026-11-04 ~22:05Z retired reporting-only sensitivities and gates that this version's rules make inapplicable, kept A at w = 512 as a sensitivity and scheduled the per-channel Forgis m0; both are pending for 0.9.5.1, as the dataset card lists. Forgis checkpoints that are not public carry a sha256, and the dataset card says which.
What the board does not show
The board does not show performance after fine-tuning, because nothing is fine-tuned. It does not cover datasets outside the list, and its intervals leave out pretraining seed, head training set and readout choice. It says nothing about value forecasting, because FE scores events only. Run time is reported and never scored. CAFE publishes scores and no data.
Known limitations, as written on the dataset card
- Each model keeps its 0.9.5 readout (Amendment 11 item 6), chosen with the old C head's validation values and without the new datasets.
- The new datasets were chosen with the 0.9.5 board known and with separability as the aim, which is score-informed selection (Amendment 11 item 1). On the eight new C datasets, the reviewers saw C scores of pjgood-warp-xview-combo-10M and its random-init twin while deciding; on the new A and FE datasets only model-free scores were run.
- The board with C resampled to 512 for every model was not recomputed under the new C head (Amendment 12 item 5).
- NGAFID has no tail number or pilot ID, so one aircraft or student pilot can be on both sides of a split.
- PreDist: the 7 days appended after each fault are the one build step that reads an event time; on PreDist and NoBOOM a score that follows elapsed time does well, and the data-free rows show by how much.
- Recording length carries label information in two C datasets, in the source data itself: a classifier that sees only the length scores uea/AsphaltPavementTypeCoordinates 0.720 and ucr/PLAID 0.596 (see Datasets admitted and removed); every other C dataset has one length per recording. The variable-length models see the length of recordings above 512 samples and the block-averaged models do not. The board with C resampled to 512 for every model is under Sensitivities.
- On W3 a score that reads only elapsed time reaches 0.9995, so a model that tracks drift scores well there without detecting anything. The A gate compares the ranked rows with 0.603, the mean over the A datasets of each dataset's best data-free score. The board without the five returned A datasets is under Sensitivities.
- On ESA_M1, ESA_M2, HAI, UKWIND and HOT some A Tuning series are other blocks of the same recordings as Eval series, though no series is in both, so the readout choice is less independent of the A test material than the split suggests.
- TiRex-2, a third-party model, was dropped with the 0.9.4.1 board known, where it ranked 8 in tier 1.
- FactoryNet's README warns that recording context partly predicts fault labels, so real fault evaluation should stay within one recording session.
mv06/vorausand the other pooled C datasets mix sessions, and a voraus split tests settings not seen in training. - voraus-AD comes from FactoryNet's copy, not the publisher's files, under CC BY-NC-SA 4.0. Forgis is a company, so CAFE publishes scores only, and a legal reading is still open.
- The weights of the Forgis rows are not public. Each carries a sha256 under Models, so a later release can be checked against it, and until then outsiders cannot rerun those rows.
- At least 66 distinct Saturn-family checkpoints, including the five ranked Forgis rows and two HEPA-lineage precursors, have CAFE or PrecursorBench 1.4 Eval scores on datasets of the 0.9.3.1 board, with records dated from 2026-08-04 to 2026-10-28. Before its submission, each ranked row had at least this many other variants scored: LeSaturn-warppool-factorized-7.4M 43, pjgood-warp-xview-combo-10M 59, pj_better_3p7m and pj_better_10m 64, and pj_better_1m 65. These are lower bounds counted from repository records, because some run trees and lane outputs are unavailable, and they exclude readout variants, controls, evaluation seeds, PrecursorBench v1 runs and development-harness runs.
- MantisV2 is read through the sweep's adapter, and its m0 is the sweep's released-readout rule, not independently confirmed.
- Hill of Towie labels are inferred stops, with rules made without any score. cdip_waves_c was rebuilt because
series.npydiffers from the pinned file; every ranked row was recomputed on the rebuilt file. - The near-duplicate rule clusters SMAP series with long constant stretches although their correlation is near zero, and four UKWIND turbines have identical series that still need checking at the source.
- Mantis and NuTime were pretrained on data that includes UCR and UEA training splits. Whether a Forgis checkpoint was pretrained on FactoryNet data was not established.
How to submit a model
CAFE has no upload form. To propose a model, open a discussion on the dataset page with a public checkpoint pinned to a commit, its licence, code that turns an array of shape (samples, channels, T) into an embedding, with the largest T it accepts, the list of readouts it exposes, and the number of variants you scored on CAFE datasets before submitting, which the protocol publishes with the row. Forgis then runs its cells under the rules above, and the row appears with its marks in a dated version.
Datasets and models
Datasets and licences
CAFE redistributes no data.
Models
Every model is frozen.
Version history
Figures and tables for reports
Every figure is a file in this Space. Use the links under each one. Tables are below in a form you can copy, and each also exists as a CSV file. Version 0.9.6.

Not offered here because they predate this board: baselines.png, cost.png, elo_cost.png, gaps.png, leaderboard.png, method_board.png, money_plot.pdf, money_plot.png, variance_breakdown.png, variance_pie.png.
Tables
Glossary
- A
- Anomaly detection: find the abnormal stretches in a series. Scored by VUS-PR after the prefix.
- AUROC
- The chance that a randomly picked positive case gets a higher score than a randomly picked negative one. FE uses a stratified version, compared within fold, unit and month.
- balanced accuracy
- Accuracy averaged over classes, so a large class does not dominate. C rescales it so that chance is 0.5.
- baseline
- A row with no learned encoder: ZERO on every task, and current value on FE. Shown on every board, never ranked. The random-init control and the other references are listed beside them.
- best baseline
- On one dataset, the highest-scoring of the baselines the board compares with.
- bootstrap
- Drawing the test material again with replacement to see how far a score moves. CAFE uses 10,000 draws.
- C
- Classification: say what a recording shows. Scored by balanced accuracy.
- CAFE score
- The mean of the task scores that count on this release: C, A and FE.
- cell
- One model's score on one dataset, stored with its bootstrap draws.
- chance-normalised
- Rescaled so that random output gives 0.5 and a perfect result gives 1.
- conflict of interest
- Forgis runs CAFE and also builds some of the models it ranks. Those rows carry the mark ◊.
- embedding
- The vector of numbers a frozen model returns for a window. It is all a head ever sees.
- Eval series
- The series of an A dataset that are scored. Tuning series are kept apart.
- FE
- Forecasting events: say whether an event will happen within the next lead time. Scored by AUROC.
- foundation model
- A network pretrained on many time series and then used for jobs it did not see.
- frozen
- The weights are not changed for CAFE. No fine-tuning on any dataset.
- head
- The small model fitted on the embedding for one task. It is the same for every model.
- Holm
- A step-down correction that keeps the error rate over a whole family of pair tests at the stated level.
- input rules
- What each encoder gets: on C the whole recording (block-averaged to 512 for fixed-length models; stretched to 512 when it is 512 samples or shorter), on A a window of 256 real samples, on FE the last 512 samples. No padding, no mask.
- Kendall tau
- Agreement between two orderings: 1 means the same order, 0 means no relation.
- lead time
- How far ahead an FE head has to warn.
- Mahalanobis distance
- Distance that takes account of the spread and correlation of the normal windows.
- near-duplicate cluster
- Eval series joined by a rule on the data alone and resampled as one block, so that copies do not narrow the interval.
- null
- A score that reads no model: elapsed time rising, elapsed time falling, or a random number per window.
- null floor
- A dataset's highest null. A model at or below it has shown nothing the clock or chance could not.
- One readout
- The one readout a model uses on C, A and FE, picked by the highest validation CAFE score without reading any test value. This is the main board's rule.
- paired
- Every model is scored on the same random draws, so a difference between two models does not depend on which material a draw picked.
- practically equal
- A verdict: not resolved, and the 95% interval of the difference lies inside plus or minus 0.01.
- prefix
- The normal stretch at the start of an A series, used to fit the head.
- readout
- Which internal tensor of a model is taken as its embedding.
- reference
- A hand-made row that embeds nothing, such as max-|z| or current value. Shown, never ranked.
- tabular row
- A gradient-boosted or MLP learner on hand-written statistics of the window. Shown, never ranked.
- tier
- Models in score order. Tier 1 holds the models above the first one resolved below the top model; the next tier starts there and is built the same way, so a model in a lower tier can still be unresolved against the top one.
- Tuning series
- Series of an A dataset kept out of scoring. Only readout selection reads them.
- unresolved
- A verdict: the data do not separate the two models, and the interval is too wide to call them equal.
- VUS-PR
- Volume under the precision-recall surface, the metric for A.
- within seed noise
- A pair of single-seed models closer than 0.009 on the CAFE score or on a task board, 1.96 times the total SD of a single-seed difference in the 0.9.2 noise budget (0.0044, of which pretraining seed is 0.0018), a normal approximation.
- ZERO
- A fixed random projection of the raw window with no learning. The no-encoder reference.
- †
- A mean over fewer datasets than the view has, because some cells do not exist in this readout mode.
- ◊
- A model developed by Forgis with access to CAFE Eval scores.